Synopsis
Get basic statistical functions working in Perl as if they were part of List::Util, like min, max, sum, etc.
Getting help
h prints any function's section of this document to STDOUT and returns, in
the spirit of R's ?function at the prompt. It takes the name three ways:
h('quantile');    # by name
h(*quantile);     # by name, unquoted
h(\&quantile);    # by reference
h();              # this section, and the list of documented functions

perl -MStats::LikeR -e 'h(*agg)'   # straight from the shell
h works for every function in the distribution looking the name up in the module's own POD rather than watching an argument list. That POD is generated from this file, so what h
prints is what you are reading.
Note that h(bedroc), with no quotes and no sigil, cannot be made to work:
every function here is exported, so Perl parses the bareword as a call to
bedroc() before h is ever reached. Use one of the three forms above.
Functions/Subroutines
add_data
Add data to an existing hash or array reference. This function acts as the equivalent of adding new rows, as well as an ljoin (described below). It dynamically infers your target data structure, handles deeply nested records, and seamlessly coerces mismatched data shapes to preserve the structural integrity of your primary reference.
Hash of Hashes (HoH)
When the target is a Hash of Hashes, incoming hash keys update existing rows, and new keys create new rows.
$data = { 'Jack Smith' => { age => 30 } };

$n = {
    'Jack Smith' => {    # Update existing (Hash)
        dept => 'Engineering'
     },
    'Jane Doe'   => { age => 25, dept => 'Sales' }, # Add new (Hash)
    'Invalid'    => 'Not a reference'               # Edge case safety
};

add_data($data, $n);
Resulting Structure:
{
    "Jack Smith":  {
        "age":  30,
        "dept": "Engineering"
    },
    "Jane Doe":    {
        "age":  25,
        "dept": "Sales"
    }
}
Hash of Arrays (HoA)
When the target is a Hash of Arrays, incoming arrays are pushed onto the existing arrays, appending the new elements, similarly to R's rbind.
$data = { 'Project Alpha' => [ 'task1', 'task2' ] };
$n = {
    'Project Alpha' => [ 'task3' ],         # Appends to existing array
    'Project Beta'  => [ 'task1', 'task2' ] # Creates new array row
};
add_data($data, $n);
Resulting Structure:
{
    "Project Alpha": [ "task1", "task2", "task3" ],
    "Project Beta":  [ "task1", "task2" ]
}
Array of Hashes / Arrays (AoH / AoA)
add_data now natively supports Array references at the root level. When targeting an Array, it iterates through the source array and merges data at the corresponding indices.
$data = [
    { id => 1, name => 'Alice' }
];

$n = [
    { role => 'Admin' },             # Updates index 0
    { id => 2, name => 'Bob' }       # Creates index 1
];

add_data($data, $n);
Resulting Structure:
[
    { "id": 1, "name": "Alice", "role": "Admin" },
    { "id": 2, "name": "Bob" }
]
Advanced Structural Coercion & Cross-Merging
add_data strictly enforces the primary structure of your target reference (determined by inspecting its outer and inner bounds). If you mix Array and Hash types, the function automatically coerces the incoming data to match the target.
1. Inner Coercion (Mixing Rows):
- Target is HoH: Source Array rows are read in pairs and converted to key-value pairs.
- Target is HoA: Source Hash rows are flattened into key-value pairs and pushed onto the array.
2. Root-Level Coercion (Mixing Outer Containers):
- Target is Array, Source is Hash: The function evaluates the Hash keys as numeric indices. (e.g., source key
"0"merges into target array index[0]). Non-numeric keys are safely ignored. - Target is Hash, Source is Array: The function converts the Array indices into stringified Hash keys. (e.g., source array index
[1]merges into target hash key"1").
Source is a mixed Hash. Keys dictate the target array index!
$n = {
    '0' => { y => 20 },                 # Merges into $data->[0]
    '1' => [ 'z', 30 ],                 # Array pair coerced to Hash, creates $data->[1]
    'ignored' => { k => 'v' }           # Ignored: cannot map to an array index
};

add_data($data, $n);
Resulting Structure strictly remains an Array of Hashes:
[
    { "x": 10, "y": 20 },
    { "z": 30 }
]
NB: If add_data is called on a completely empty target reference (e.g., $data = {} or $data = []), it will intelligently infer the required inner structure (Hashes vs Arrays) by inspecting the first valid row of the source data.
age_standardize
Directly standardized rate: reweights stratum-specific rates (e.g. age-specific
disease rates) to a standard population so rates from populations with different
age structures can be compared. The confidence interval uses the Fay-Feuer gamma
method, matching R's epitools::ageadjust.direct, and is accurate even for rare
events. Validated numerically against R.
my @count  = (5, 20, 55, 60);       # events per age stratum
my @pop    = (1000, 3000, 4000, 2000);  # person-time / population per stratum
my @stdpop = (2000, 3000, 3000, 2000);  # standard population weights

my $r = age_standardize(\@count, \@pop, \@stdpop, per => 100_000);
printf "age-adjusted rate = %.1f per 100k (95%% CI %.1f-%.1f)\n",
    $r->{adj_rate}, $r->{'conf_int'}[0], $r->{'conf_int'}[1];
Arguments may be positional (count, pop, stdpop) or named; pass rate
instead of count if you already have stratum-specific rates.
Input Parameters
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| count | ArrayRef | (count or rate required) | Event count per stratum. | \@count |
| rate | ArrayRef | (count or rate required) | Stratum-specific rate (alternative to count). | \@rate |
| pop | ArrayRef | None (Required) | Population / person-time per stratum. | \@pop |
| stdpop | ArrayRef | None (Required) | Standard-population weight per stratum. | \@stdpop |
| conf_level | Number | 0.95 | Confidence level for the gamma interval. | 0.90 |
| per | Number | 1 | Scale factor applied to every reported rate. | 100_000 |
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| crude_rate | Double | Unadjusted overall rate (× per). | 1400.0 |
| adj_rate | Double | Directly standardized rate (× per). | 1312.5 |
| conf_int | ArrayRef | Fay-Feuer gamma [lower, upper] (× per). | [1097.8, 1569.6] |
| se | Double | Standard error of the standardized rate (× per). | |
| conf_level | Double | Confidence level used. | 0.95 |
| per | Number | The scale factor applied. | 100000 |
agg
Split-apply-combine over a data frame: split the rows into groups, apply one or
more aggregators to chosen columns, and combine the results into a new frame.
This is the combine half that group_by (which only splits) leaves to you,
and the analog of pandas df.groupby(...).agg(...). With no by it collapses
the whole frame to a single row, like pandas df.agg(...).
agg accepts all four data-frame shapes and, by default, returns the same shape
it was given:
AoA  [ [ .. ], [ .. ] ]      array of arrayrefs   (positional columns)
AoH  [ { .. }, { .. } ]      array of hashrefs    (the read_table default)
HoA  { c => [ .. ], .. }     hash of arrayrefs    (column-major)
HoH  { r => { .. }, .. }     hash of hashrefs     (named rows)
For AoA the column identifiers in by and in the agg spec are integer
positions (a negative one counts from the end, as $row->[-1] does); for the
other three shapes they are column names. A column that no row has is an error,
so a misspelled name dies rather than coming back as a column of undef. An undef
row of an AoA or AoH is skipped. The original frame is never modified, down to
its scalars: a numeric cell is not given a cached string, nor a string cell a
cached number.
The split is done in C, in one pass that hashes each row's by cells into its
group and a second that drops each aggregated cell straight into its group's
array, sharing the frame's own scalars wherever only the numeric aggregators
read them. On a million-row AoH in a thousand groups it takes about a quarter of
the time the pure-Perl split it replaced did, in about a fifth of the extra
memory.
Usage
use Stats::LikeR;

# grouped, one aggregator per column
my $out = agg($df, by => 'sex', agg => { wt => 'mean' });

# grouped, several aggregators, several columns
my $out = agg($df,
    by  => 'sex',
    agg => { wt => [ 'mean', 'sd' ], age => [ 'mean', 'count' ] },
);

# ungrouped: the whole frame becomes one row
my $out = agg($df, agg => { wt => 'mean', age => 'count' });

# group on two columns and emit a hash of hashes
my $out = agg($df,
    by            => [ 'a', 'b' ],
    agg           => { v => 'sum' },
    'output_type' => 'hoh',
);
Arguments
agg takes the data frame first, then name => value pairs.
- agg (required) — a hashref mapping each column to an aggregator spec. A spec is one of: a single aggregator name (string), an arrayref of names, or a coderef. See Aggregators below.
- by — a single column or an arrayref of columns to group on. Omit it to aggregate the entire frame into one row.
- skipna —
1(default) drops undef cells before a numeric aggregator runs.0makes any undef in a group poison the numeric result for that group (the cell comes back undef), matching pandasskipna=False; that coversmean,median,sum,sd,var,min,maxandmode.count,n,nunique,first, andlastignore this flag. - sort —
1(default) sorts the output groups by key;0keeps first-seen order. Eachbycolumn is compared on its own terms: numerically when every value in it looks like a number, otherwise as strings. Within a column an undef key sorts last (where pandas puts its NaN group) and a NaN sorts after every number. - output_type —
aoa,aoh,hoa, orhoh. Defaults to the same family as the input frame.
Aggregators
Named aggregators may be combined in any order per column:
| name | result |
|-----------|-------------------------------------------------------------|
| mean | arithmetic mean (needs ≥ 1 defined cell, else undef) |
| median | median (needs ≥ 1) |
| sum | sum (needs ≥ 1) |
| sd | sample standard deviation (needs ≥ 2, else undef) |
| var | sample variance (needs ≥ 2, else undef) |
| min | minimum (needs ≥ 1) |
| max | maximum (needs ≥ 1) |
| count | number of defined cells |
| n | number of cells, undef included |
| nunique | number of distinct defined cells |
| first | first defined cell (undef if none) |
| last | last defined cell (undef if none) |
| mode | modal defined cell; ties broken deterministically |
The numeric aggregators call the module's functions of the same name, so they
inherit their precision. agg filters undef itself before calling them, so they
never croak on missing cells. mode is made deterministic: on a tie it returns
the smallest number, or the lowest string when the values are not numeric.
A coderef may be supplied instead of a name for full control. It is called
once per group as $code->(\@cells), where @cells are every cell for that
column in the group including undef, and must return a single scalar. It
is called in scalar context, so sub { grep { .. } @{ $_[0] } } returns a
count. The cells are copies; changing them does not change the frame:
# count the missing values in each group
my $out = agg($df, by => 'sex', agg => {
    age => sub {
        my $cells = shift;
        scalar grep { !defined } @$cells;
    },
});
Output shape and column naming
Output columns are laid out deterministically: the by columns first, in the
order given, then the aggregated columns sorted (numerically for AoA integer
columns, otherwise as strings), each expanded over its aggregator list in the
order supplied.
A column reduced by a single aggregator keeps its own name; reduced by
two or more it becomes <col>_<func>. A coderef's <func> is fn, or
fn1, fn2, .. when a column has more than one. A column that is also a by
column is always named <col>_<func>, so by => 'g', agg => { g => 'count' }
gives g and g_count. Any name that would still be generated twice is an
error, except under output_type => 'aoa', whose columns are positional:
my $df = [
    { sex => 'M', wt => 70, age => 30    },
    { sex => 'F', wt => 60, age => 25    },
    { sex => 'M', wt => 80, age => 40    },
    { sex => 'F', wt => 55, age => undef },
];

my $out = agg($df,
    by  => 'sex',
    agg => { wt => [ 'mean', 'sd' ], age => [ 'mean', 'count' ] },
);
Resulting Structure (AoH in, AoH out):
[
    {
        sex       => 'F',
        wt_mean   => 57.5,
        wt_sd     => 3.53553390593274,
        age_mean  => 25,     # the undef age was skipped
        age_count => 1,      # count excludes the undef
    },
    {
        sex       => 'M',
        wt_mean   => 75,
        wt_sd     => 7.07106781186548,
        age_mean  => 35,
        age_count => 2,
    },
]
Ungrouped
Without by, the frame collapses to one row:
my $out = agg($df, agg => { wt => 'mean', age => 'count' });

# [ { wt => 66.25, age => 3 } ]
That holds for a frame with no rows too, as for pandas df.agg: count and n
are 0 and the numeric aggregators undef. A grouped empty frame has no groups.
Array of Arrays (AoA)
Columns are integer positions. Grouping on column 0 and reducing column 1:
my $aoa = [ [ 'M', 70 ], [ 'F', 60 ], [ 'M', 80 ] ];
my $out = agg($aoa, by => 0, agg => { 1 => [ 'mean', 'max' ] });

# [ [ 'F', 60, 60 ], [ 'M', 75, 80 ] ]
#     ^grp  ^mean ^max
The output row is positional: the by columns first, then each aggregated
column in the plan order.
Hash of Hashes (HoH) output
With output_type => 'hoh' the row label is the group value; multiple by
columns are joined with a dot, an ungrouped result is keyed all, and a
collision is made unique with a .N suffix.
my $out = agg($df, by => 'sex', agg => { wt => 'mean' }, 'output_type' => 'hoh');

# {
#     F => { sex => 'F', wt => 57.5 },
#     M => { sex => 'M', wt => 75   },
# }
Missing values
By default (skipna => 1) undef cells are removed before a numeric aggregator
runs, so a group of (60, 55) with a third undef still yields the mean of the
two defined values. count reports only defined cells while n counts undef
too. With skipna => 0, a group containing any undef returns undef for the
numeric aggregators (mean median sum sd var min max mode); the counting and
positional aggregators are unaffected.
A group without enough data yields undef rather than an error: sd and var
need at least two defined cells, the other numeric aggregators need at least
one.
Errors
agg dies (with a trailing newline, so the message prints cleanly) when:
- the first argument is not an ARRAY or HASH ref;
- no
aggspec is given, or it is not a non-empty hashref; - an unknown option is passed;
- an aggregator name is not recognized;
- an aggregator list for a column is empty, or holds something that is neither a name nor a coderef;
output_typeis not one ofaoa,aoh,hoa,hoh;- the trailing arguments are not
name => valuepairs; - a column in
byor in the spec is undef, is in no row, is not an integer position (AoA), or is not an arrayref (HoA); - a row of an AoA or AoH is defined but not an ARRAY or HASH ref;
- two output columns would get the same name (see above);
- a numeric aggregator meets a cell that is not a number. The message names
the aggregator, the column and the group, as in
agg: mean of column 'v' over group (g = 'F'): mean: non-numeric value ...
See also
group_by (the split step), concat / rbind (row-binding frames),
dropna, assign, value_counts.
anova
Sequential (Type-I) ANOVA table for a linear model, in the same shape aov
returns. anova fits response ~ terms, then decomposes the model sum of
squares one term at a time, in R's term order -- main effects first, then
two-way interactions, and so on, each group in formula order -- and F-tests
each term against the residual mean square. The formula is read by the same
parser lm and glm use.
anova(
{
    yield => [5.5, 5.4, 5.8, 4.5, 4.8, 4.2],
    ctrl  => [1,     1,   1,   0,   0,   0]
},
'yield ~ ctrl');
returns
{
    ctrl        {
        Df          1,
        "F value"   25.6000000000001,
        "Mean Sq"   1.70666666666667,
        "Pr(>F)"    0.00718232855871859,
        "Sum Sq"    1.70666666666667
    },
    Residuals   {
        Df          4,
        "Mean Sq"   0.0666666666666665,
        "Sum Sq"    0.266666666666666
    }
}
Each term's Sum Sq is what it adds to the terms before it in the formula,
not what it would explain alone. When the regressors are correlated, as in
anova.lm's own example on R's LifeCycleSavings, reversing the formula
moves sum of squares from one term to another and changes their p-values. The
total of the terms and the Residuals row do not move. In a balanced design
such as warpbreaks the terms are orthogonal, so the order changes nothing.

Two-way (and higher) models use the * operator, which implicitly evaluates
the main effects alongside the interaction (a * b expands to a + b + a:b;
a * b * c to the full factorial a + b + c + a:b + a:c + b:c + a:b:c):
my $res_2way = anova($data_2way, 'len ~ supp * dose');
Bare string columns are treated as factors; numeric columns, I(x^2) and
log(x) enter as single regressors. A factor is coded by treatment contrasts
or by a full set of indicators exactly as R decides it (its "margin rule"), so
nested and per-group-slope models come out as in R: y ~ a + a:b gives a:b
levels(a) * (levels(b) - 1) degrees of freedom, and y ~ g + g:x fits a
separate slope of x in each group. - 1, + 0 and 0 + remove the
intercept, . stands for every other column (taken in sorted order, since a
hash has no column order), offset(z) is subtracted from the response, and
a:b and b:a are the same term. A term with no estimable column -- one that
is collinear with the terms before it -- is kept with 0 degrees of freedom and
0 sum of squares, where R leaves it out of the table. A column is judged
collinear by R's own rule: when what the earlier columns leave of it has a
norm below 1e-7 of its own.
The fit keeps memory independent of the number of rows: it rotates one row at
a time into a p-by-p triangular factor (p the number of design columns),
so a 100,000-row model with 801 columns needs about 2.5 MB rather than a
640 MB design matrix.
Given two or more formulas, anova compares nested models instead and returns
an array ref of rows, one per model in the order supplied — R's
anova(m1, m2, ...). Each row carries Res_Df, RSS and formula; every row
after the first adds Df and Sum of Sq, the drops from the row before it,
and F and Pr(>F):
my $tab = anova($data, 'y ~ 1', 'y ~ x1', 'y ~ x1 + x2');
printf "adding x2: F = %.4g, p = %.4g\n", $tab->[2]{F}, $tab->[2]{'Pr(>F)'};
F is the Sum of Sq per Df over the residual mean square of the model with
the fewest residual degrees of freedom, and its p-value is taken on the
absolute Df, so models listed largest first are tested too. As in R's
stat.anova, F and Pr(>F) are left out where Df is 0 or F would be
negative (models that are not nested), and also where that residual mean
square is 0. Every model is fitted on the same rows: those complete for all of
them. As R's anova.lmlist does, a model whose response differs from the
first model's is dropped with a warning, and if only one model is left, its
single-model table is returned.
Below, warpbreaks is fitted as four nested formulas, each adding one term.
Each row's Sum of Sq is the drop in RSS from the row before it. Because
every F is taken over the largest model's residual mean square, the chain
gives the same F values as the single-model table of the largest formula.

Given two or more fitted models instead -- lm or glm fits (or
negbin glm fits) of the same response on the same rows -- anova compares
them as R's anova(m0, m1, ...) does, and also returns an array ref of rows
in the order supplied. For lm fits it is anova.lmlist's F test, on the
largest model's residual mean square (Res_Df, RSS, Df, Sum of Sq, F,
Pr(>F)). For glm fits it is anova.glmlist's table (Resid. Df,
Resid. Dev, Df, Deviance) with a test chosen as R chooses it: a
likelihood-ratio Pr(>Chi) for the families with a known dispersion, an F on
the largest model's dispersion for gaussian; ask for one with
test => 'Chisq', 'LRT' or 'F', or fix the scale with dispersion.
negbin fits give MASS::anova.negbin's likelihood-ratio table (theta,
Resid. df, 2 x log-lik., df, LR stat., Pr(Chi)), whose rows
are ordered by residual degrees of freedom.
my $m0 = glm(formula => 'y ~ age',         data => \%d, family => 'poisson');
my $m1 = glm(formula => 'y ~ age + hours', data => \%d, family => 'poisson');
my $t  = anova($m0, $m1);
printf "LR test for hours: p = %.3g\n", $t->[1]{'Pr(>Chi)'};
This is also how a first-stage F on a block of instruments is had without
ivreg.
Both forms evaluate Pr(>F) in the upper tail of the F distribution rather
than as 1 - pf(F, df1, df2); see
F and z tail p-values.
Input Parameters
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| data_sv | HashRef or ArrayRef | (Required) | The dataset. A Hash of Arrays (HoA, columns, all the same length), Hash of Hashes (HoH) or Array of Hashes (AoH, rows) — the forms lm accepts. |
| formula_sv | String | (Required) | Symbolic model 'response ~ rhs', with +, :, *, ., - 1/0 + and offset(), as lm reads it. Unlike aov, anova does not auto-stack, so a formula is mandatory. Give two or more to compare models. | 'yield ~ N * P' |
Output Variables
A single HashRef; keys are the parsed term names, so the structure varies
with the formula.
| Parameter | Type | Description | Example |
| --- | --- | --- | --- |
| (Term Name) | HashRef | ANOVA-table stats for each term ('ctrl', 'N:P', …), named as R names them: an interaction's variables in the order they first appear in the formula. 'Mean Sq', 'F value' and 'Pr(>F)' are omitted for 0-df (aliased) terms. | {'Df'=>1,'Sum Sq'=>14.2,'Mean Sq'=>14.2,'F value'=>25.81,'Pr(>F)'=>0.0004} |
| Residuals | HashRef | Residual (error) statistics; never carries an F test. | {'Df'=>10,'Sum Sq'=>5.5,'Mean Sq'=>0.55} |
anova vs aov — what's the difference?
For a single model they compute the identical Type-I table — in R,
anova(lm(f)) and summary(aov(f)) return the same sums of squares, and the
same holds here (anova(\%d,'yield ~ ctrl') reproduces the aov table
above exactly). The difference is one of role, not arithmetic:
-
aovis the model-fitting idiom for designed experiments. It leans toward factors and balanced designs, and in this module it adds two conveniencesanovadeliberately leaves out: it can auto-stack a named list when you omit the formula (R'sstack()+Value ~ Group), and it returns agroup_statsblock of per-group means and counts alongside the table. Reach foraovwhen your question is "do these treatment groups differ, and what do the groups look like?" -
anovais the model-table idiom. It always wants an explicit formula and returns just the decomposition — nothing descriptive. Reach for it when you already have a model in mind and only want its term-by-term SS / F-tests, or when you want the leaner object to feed onward.
In short: same numbers for one model; aov is the richer "fit + describe"
call (and the only one that stacks), anova is the minimal "give me the
table" call. Note that both are Type-I / sequential, so the order of terms
of the same degree matters, and both share this module's pf, so p-values
agree with oneway_test and the rest of Stats::LikeR. Both read the formula
with lm's parser and fit it the same way, so any formula one accepts the
other fits identically.
Comparing nested models -- anova(m1, m2) in R -- is done by giving anova
two or more formulas, or two or more fitted models; see above.
aoh2h
Fold a two-column array-of-hashes back down into a plain hash. This is the
reverse of h2aoh, and the two are exact opposites under their
defaults.
my $h = aoh2h($aoh);
my $h = aoh2h($aoh, var_name => 'gene', value_name => 'n');
One column supplies the keys, the other the values; every other column in the
row is ignored. R spells this tibble::deframe(); pandas spells it
df.set_index('k')['v'].to_dict().
Arguments
$aoh — an array ref of hash refs. Required. Every row has to be a hash ref
carrying both named columns.
Everything after it is name => value pairs:
| Option | Default | Meaning |
| --- | --- | --- |
| var_name | variable | The column holding the keys. |
| value_name | value | The column holding the values. |
| duplicates | die | What to do when two rows carry the same key: die is fatal, first keeps the earliest row, last keeps the latest. |
var_name and value_name must differ.
Returns
A hash ref mapping each row's var_name cell to its value_name cell. An
empty array ref gives back {}.
Values are assigned across, so a value that is itself a reference is shared
with the input rather than cloned — the same shallow copy aoh2hoa makes.
Example
my $aoh = [
    { gene => 'TP53',  n => 12 },
    { gene => 'BRCA1', n =>  7 },
];
my $h = aoh2h($aoh, var_name => 'gene', value_name => 'n');
# { TP53 => 12, BRCA1 => 7 }

# keep the last of a repeated key instead of dying
my $last = aoh2h([ { variable => 'a', value => 1 },
                   { variable => 'a', value => 9 } ], duplicates => 'last');
# { a => 9 }
Round trip
is_deeply( aoh2h( h2aoh(\%h) ), \%h ); # true for any flat hash
The one thing that does not survive the trip is the type of a key: Perl hash keys are strings, so a numeric key comes back as the string that prints the same way.
Errors
aoh2h dies when the first argument is undefined or not an array ref, when the
options are not name => value pairs, when an option is unknown, when
var_name equals value_name, when duplicates is not one of the three
allowed words, when a row is not a hash ref, when a row is missing either named
column, when a row's key cell is undef, or — under the default
duplicates => 'die' — when two rows share a key. Every message names the
offending row by index.
See also
h2aoh is the reverse. aoh2hoh also indexes rows by a
column, but keeps the whole row as the value instead of one cell.
aoh2hoa
aoh2hoa($aoh) — transpose an array-of-hashes (row-major) into a hash-of-arrays (column-major).
my $hoa = aoh2hoa([ { a => 1, b => 2 }, { a => 3 } ]);
# $hoa = { a => [1, 3], b => [2, undef] }
Rows go in, columns come out: each distinct key across the input rows becomes one output column, and the values are gathered down that column in row order.
Arguments
$aoh — an array ref of hash refs, one hash per row. This is the only argument, and it is required. Passing anything that is not an array ref is fatal:
aoh2hoa({ a => 1 }); # dies: argument must be an arrayref of hashrefs
Returns
A hash ref of array refs. Each key is a column name (the union of all keys seen across the rows); each value is an array ref holding that column's cells. Every column has exactly scalar @$aoh elements, so the result is rectangular even when the input is ragged.
Behavior
The column set is the union of every row's keys — a key that appears in only some rows still produces a full-length column, with undef in the rows that lacked it.
Each column is padded to exactly the row count. Cells missing from a given row come through as undef, including trailing gaps (a column whose last contributing row is early still runs the full length). These absent cells are cheap holes in the array, not stored SVs.
Values are copied (newSVsv), so the returned structure is independent of the input — mutating $aoh afterward won't disturb the result. The copy is shallow: a value that is itself a reference is copied the same way $col->[$i] = $row->{$k} would, i.e. the ref is duplicated but its referent is shared.
Keys are handled SV-first (hv_iterkeysv / hv_fetch_ent), so UTF-8 and otherwise non-trivial hash keys round-trip correctly.
A row that is not a hash ref is skipped rather than fatal: it contributes undef to every column at its index. So a stray undef or scalar in the input thins the columns at that position instead of dying.
Notes
The output column order follows hash iteration order and is therefore not guaranteed — sort the keys if you need a stable layout. Round-tripping through hoa2aoh (or the reverse) reconstructs the data but not necessarily the original key/row ordering, and rows originally absent a key will gain it as an explicit undef.
aoh2hoh
Index an Array-of-Hashes into a Hash-of-Hashes, keyed by the value of one column.
my $hoh = aoh2hoh($aoh, $key);
Where aoh2hoa transposes rows into columns, aoh2hoh indexes rows by a chosen field, turning a sequential list into a lookup table. The chosen field is treated as a primary key: it must be unique across the rows, and a repeat is fatal.
Signature
| Argument | Type | Meaning |
|----------|-------------|------------------------------------------------------|
| $aoh | arrayref | The rows: an arrayref of hashrefs. |
| $key | scalar | The column name whose value indexes each row. |
Returns a hashref. Each top-level key is a row's $row->{$key} value; each value is a shallow copy of that row.
my $rows = [
    { id => 'p1', kd => 12.4, chain => 'A' },
    { id => 'p2', kd =>  3.1, chain => 'B' },
];

my $by_id = aoh2hoh($rows, 'id');
# {
#   p1 => { id => 'p1', kd => 12.4, chain => 'A' },
#   p2 => { id => 'p2', kd =>  3.1, chain => 'B' },
# }

$by_id->{p2}{kd};   # 3.1 -- O(1) lookup instead of a linear scan
Semantics
These choices are the parts most worth keeping in mind, because the AoH->HoH mapping is ambiguous where a transpose is not.
Duplicate keys are fatal. If two rows share the same key value, the call dies rather than silently dropping a row:
aoh2hoh([ { id => 'a', x => 1 }, { id => 'a', x => 9 } ], 'id');
# dies: aoh2hoh: duplicate key 'a' has >= 2 occurrences
This makes the chosen column an enforced primary key: the result is only returned if every row maps to a distinct bucket. If your data legitimately has repeats and you want to keep them, you want a hash-of-arrays-of-rows instead -- a different return shape. If you want last-wins or first-wins collapse, dedup the input before calling.
The key column is retained inside each inner hash (the copy is of the whole row). Drop it deliberately if you don't want the redundancy.
Shallow copy. Inner hashes are fresh, so adding or removing keys on the output never touches the input. But a value that is itself a reference is shared, exactly like $out{$rk}{$_} = $row->{$_}:
my $shared = [ 1, 2, 3 ];
my $out = aoh2hoh([ { id => 'a', data => $shared } ], 'id');
push @{ $out->{a}{data} }, 4;   # $shared now has 4 elements too
A row that is not a hashref, or that lacks a defined value at $key, is fatal.
Numeric vs string keys collide. Hash keys are strings, so 1 and "1" map to the same bucket and therefore trip the duplicate-key die. Normalize the key column first if a row could carry both forms.
Use cases
Join / enrichment lookups. Build an index once, then attach fields from one dataset onto another by shared id without an O(n*m) nested loop -- and the duplicate-key die guarantees the join side really is keyed uniquely:
my $meta = aoh2hoh($pdb_metadata, 'pdb_id');
for my $hit (@$results) {
    $hit->{resolution} = $meta->{ $hit->{pdb_id} }{resolution};
}
Primary-key validation. Because a repeat is fatal, the call doubles as an assertion that a column is unique -- a cheap way to catch a malformed table (duplicate accession, duplicate peptide id) at load time rather than downstream.
Random-access reshaping of tabular data. After parsing a CSV/TSV into an array of row-hashes, re-index by a primary key so downstream code can fetch a row by name rather than scanning. Pairs naturally with the CSV-parsing side of the toolkit.
Set membership and difference. exists $hoh->{$k} gives a cheap presence test, useful for asking which ids in one table are missing from another.
Relationship to aoh2hoa
| Function | Output shape | Indexed by | Typical question it answers |
|------------|------------------------|-----------------|------------------------------------------|
| aoh2hoa | hash of arrayrefs | column name | "give me every value in column X" |
| aoh2hoh | hash of hashrefs | a row's key val | "give me the whole row whose id is Y" |
Reach for aoh2hoa when you want columns (vectors to feed a statistic or a plot); reach for aoh2hoh when you want addressable rows keyed by a unique field.
aov
Warning: assumes normal distribution
aov(
{
    yield => [5.5, 5.4, 5.8, 4.5, 4.8, 4.2],
    ctrl  => [1,     1,   1,   0,   0,   0]
},
'yield ~ ctrl');
which returns
{
    ctrl        {
        Df          1,
        "F value"   25.6000000000001,
        "Mean Sq"   1.70666666666667,
        Pr(>F)      0.00718232855871859,
        "Sum Sq"    1.70666666666667
    },
    Residuals   {
        Df          4,
        "Mean Sq"   0.0666666666666665,
        "Sum Sq"    0.266666666666666
   }
}
With one factor, the table is built like this. The factor's Sum Sq is how
far its group means lie from the grand mean, and the Residuals Sum Sq is
how far the observations lie from their own group's mean, each squared and
summed. Each is divided by its Df to
give its Mean Sq. F value is the term's Mean Sq over the residual one,
and Pr(>F) is the area of the F distribution on those two Df beyond it.
Below, R's PlantGrowth is given as a named list of three groups, which aov
stacks into Value ~ Group. The vertical lines on the left are the two kinds
of deviation: blue for each group's mean from the grand mean, grey for each
observation from its group's mean. The right-hand panel magnifies the tail
that Pr(>F) measures, which is too thin to see at full scale.

You can also perform Two-Way ANOVA with categorical interactions using the * operator. The parser will implicitly evaluate the main effects alongside the interaction:
my $res_2way = aov($data_2way, 'len ~ supp * dose');
The formula is read by lm's parser, the same one anova uses, so it
accepts everything lm does: +, :, * (a*b*c is every main effect and
interaction), ., - 1/0 + and offset(). Factors are coded by R's margin
rule, so an interaction need not have its main effects: y ~ a:b spans every
cell, y ~ a + a:b nests b in a, and y ~ g + g:x fits a slope per group.
Terms are taken in R's order (main effects, then two-way interactions, …),
and a:b and b:a are one term, named as R names it. A column of strings is
a factor with its levels sorted; a column of numbers is a covariate.
It is robust against rank deficiency: a column is aliased when what the
earlier columns leave of it has a norm below 1e-7 of its own, R's lm.fit
rule, and a term left with no columns stays in the table with 0 degrees of
freedom and 0 sum of squares. R's anova() leaves such a term out.
The fit is Gentleman's Givens rotations, one row at a time, as anova and
R's biglm fit, so memory does not grow with the number of rows beyond the
row names that fitted_values is keyed by. y ~ g*h + x over 100,000 rows
with a 50-level g takes 1.8 s and 52 MB.
Pr(>F) is evaluated in the upper tail of the F distribution rather than as
1 - pf(F, df1, df2), so a highly significant term reports its actual p-value
instead of a flat 0; see F and z tail p-values.
Input Parameters
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| data_sv | HashRef or ArrayRef | (Required) | The dataset to analyze. Accepts a Hash of Arrays (HoA) or Array of Hashes (AoH). If no formula is provided, it must be an HoA to allow automatic stacking (mimicking R's stack() on a named list). |
| formula_sv | String | undef | A symbolic description of the model to be fitted. If omitted, the formula automatically defaults to 'Value ~ Group' and the input data is stacked, with Group a factor whatever its names look like. | 'yield ~ N * P' |
Output Variables
The function returns a single HashRef containing the evaluated statistical results. Because the keys map dynamically to the terms parsed from your formula, the structure will vary based on your inputs.
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| (Term Name) | HashRef | undef | A nested hash for each term of the model (e.g., 'Group', 'N:P'), containing its ANOVA table statistics. 'Mean Sq' is omitted for a 0-df (aliased) term, and 'F value' and 'Pr(>F)' wherever there are no residual degrees of freedom or the fit is exact (R's NA). | {'Df' => 1, 'Sum Sq' => 14.2, 'Mean Sq' => 14.2, 'F value' => 25.81, 'Pr(>F)' => 0.0004} |
| Residuals | HashRef | undef | A nested hash containing the residual (error) statistics for the fitted model. 'Mean Sq' is omitted when there are no residual degrees of freedom. | {'Df' => 10, 'Sum Sq' => 5.5, 'Mean Sq' => 0.55} |
| group_stats | HashRef | undef | The response's mean and count in each level of each factor of the model, over the rows the model was fitted on. With one factor -- the stacked form's Group, or y ~ g -- mean and size are keyed by level, the shape oneway_test returns; with several, by factor and then level. A model with no factor has none, and both are empty. A stacked group with no usable value has size 0 and a NaN mean. | {'mean' => {'A' => 2.1, 'B' => 5.4}, 'size' => {'A' => 10, 'B' => 10}}, or {'mean' => {'wool' => {'A' => 31.04, 'B' => 25.26}, 'tension' => {...}}, ...} |
| coefficients | HashRef | undef | The coefficients, under treatment contrasts and with R's names (Intercept, woolB, woolB:tensionL). An aliased one is NaN, R's NA. | {'Intercept' => 2, 'gB' => 3} |
| fitted_values | HashRef | undef | Fitted values, offsets included, keyed by row name: the HoH key, a row_names column, or 1..n. Rows dropped for a missing value have none. | {'1' => 2, '2' => 2} |
| xlevels | HashRef | undef | Each factor's levels, sorted, the reference level first; with family ('gaussian'), what predict reads. | {'g' => ['A', 'B', 'C']} |
The coefficients are steps away from one reference cell, which is the first
level of each factor in xlevels. Because the levels are sorted, R's
warpbreaks under breaks ~ wool * tension has tension H as its reference,
not L. Intercept is that cell's mean. Every other cell adds a main effect
for each of its non-reference levels and an interaction for each
non-reference pair, and the sum is the cell's fitted value. In a full
factorial such as this one, that fitted value is the cell mean.

group_stats is something else again. It holds each factor's own means, each
averaged over the other factors, so the cell means above are not among them.
The table has one row per term in R's order, followed by Residuals, which
has no F test of its own.

omitting formula
In the case of an omitted formula, stacking is done:
aov(
{
    yield => [5.5, 5.4, 5.8, 4.5, 4.8, 4.2],
    ctrl  => [1,     1,   1,   0,   0,   0]
},
);
is the equivalent of:
yield <- c(5.5, 5.4, 5.8, 4.5, 4.8, 4.2)
ctrl <- c(1,     1,   1,   0,   0,   0)

# Combine them into a named list (the R equivalent of your hash)
my_list <- list(yield = yield, ctrl = ctrl)

# Convert the list into a "long" dataframe
# This creates two columns: "values" and "ind" (the group name)
my_data <- stack(my_list)

# Rename columns for clarity (optional but good practice)
colnames(my_data) <- c("Value", "Group")
anova_model <- aov(Value ~ Group, data = my_data)
summary(anova_model)
in R
assign
Add new columns to a data frame, computed from the columns already there — or handed in ready-made.
Usage
assign($df, new_name => VALUE, another => VALUE, ...);
$df— your data frame, in any of three shapes:- AoH — arrayref of row hashrefs:
[ {weight=>70, height=>1.75}, ... ] - HoA — hashref of column arrayrefs:
{ weight=>[70,...], height=>[1.75,...] } - HoH — hashref of row hashrefs, keyed by row name:
{ Alice=>{weight=>65}, ... }
- AoH — arrayref of row hashrefs:
new_name => VALUE— one or more pairs.VALUEis a coderef (computed from the row), an arrayref (a ready-made column), or amap_cell { ... }block (an in-place edit of the named column — see below).
It changes $df in place and also returns it (handy for chaining).
Coderef values
A coderef is called in list context, on every row, and is classified by what it returns for the first row:
-
One scalar → per-row. The sub is called once per row and that scalar is the cell.
$_(and$_[0]) is the current row as a hashref, so you read other columns with$_->{colname}.$_[1]is the row's index (0-based).$_[2]is the row key — HoH only.- A single arrayref return is stored as the cell, so
sub { [split /,/, $_->{tags}] }gives an arrayref-valued column. - List context holds for every row, not just the first:
sub { $_->{id} =~ /(\d+)/ }stores the captured digits in each row, and a match that fails returns the empty list, so its cell isundef. A later row that returns more than one value dies.
-
A list of more than one value → whole column. The list becomes the entire column, distributed positionally. This is the natural fit for column functions like
rank:assign($df, 'ΔG rank' => sub { rank( vals($df, 'dG_kcal_mol') ) }); # rank() returns a list, so the whole ranking lands in one column.
Arrayref values
Pass a column you already have and it is copied in:
assign($df, 'ΔG rank' => [ rank( vals($df, 'dG_kcal_mol') ) ]);
This is also how you install a computed list when you'd otherwise trip the "single arrayref = one cell" rule above.
In-place edits with map_cell
A plain coderef stores its return value, so an in-place transform of an existing column means the "copy, edit, return" dance — and s///r isn't available on the older perls this module supports:
# awkward: copy to $v, edit $v, return $v
assign($df, 'Res.' => sub { (my $v = $_->{'Res.'}) =~ s/^[A-Z]://; $v });
map_cell { ... } removes the ceremony. Inside the block, $_ is the named column's current cell (not the whole row), the block's return value is ignored, and the modified $_ is stored back -- for a HoA, $_ aliases the cell itself, so the edit is made where the cell lies:
use Stats::LikeR;   # exports map_cell alongside assign

assign($df, 'Res.' => map_cell { s/^[A-Z]:// });   # strip a leading "X:"
assign($df, 'Res.' => map_cell { $_ = uc });        # upper-case in place
The row is still reachable as $_[0] for sibling columns, the index as $_[1], and (HoH only) the row key as $_[2]:
assign($df, label => map_cell { $_ = "$_[0]{name} ($_[1])" });
Notes:
- Undef cells pass through untouched (undef in → undef out). The block never runs on an undefined or missing cell, so
s///and friends don't warn on uninitialized values and a missing cell stays missing rather than becoming''. - Works on all three shapes (AoH, HoA, HoH). For HoA the target column must already exist (there's no column to edit otherwise) —
map_cellon a missing HoA column dies. - A plain
sub { ... }keeps its existing meaning ($_= the whole row, return value stored);map_cellis purely additive and changes nothing for existing callers.
Ordering and length
- AoH distributes by array order; HoH by sorted key order — so any list you compute or hand in must be in
sort keys %$dforder. - Whole-column and arrayref values must have exactly one entry per row; a length mismatch dies.
- A HoA may also hold plain scalar (or
undef) entries; each row view carries them through unchanged. An empty hash is an empty HoA, and its first arrayref value sets the row count, soassign({}, x => [1, 2, 3], y => sub { $_->{x} * 2 })builds a frame from nothing. - Rows, value types, arrayref lengths and
map_celltargets are all checked before anything is written, so a call that dies on one of those leaves$dfas it found it. A coderef that dies part-way through does not roll back the rows already written.
Example
my $df = [
    { weight => 70, height => 1.75 },
    { weight => 90, height => 1.80 },
];
assign($df, bmi => sub { $_->{weight} / $_->{height} ** 2 });
# $df is now:
# [ { weight=>70, height=>1.75, bmi=>22.86 },
#   { weight=>90, height=>1.80, bmi=>27.78 } ]
Good to know
-
Pairs run in order, so a later column can use one you just made:
assign($df, bmi => sub { $_->{weight} / $_->{height} ** 2 }, class => sub { $_->{bmi} > 25 ? 'high' : 'ok' }, # uses bmi ); -
Same recipe, all shapes. The same per-row
sub { $_->{weight} / ... }works for AoH, HoA, and HoH; you always read the row through$_. -
$_is the real row, in every shape. For an AoH or HoH it is the row hash itself. For a HoA it is a view: one hash for the whole call, whose values are the frame's cells for the current row, not copies of them. Either way, a write through$_->{col}changes the frame:assign($hoa, z => sub { $_->{x} *= 10; $_->{x} + 1 }); # x is now 10 times bigger tooFor a HoA, that one view is re-pointed at each row in turn. A key the block adds to it is gone on the next row and never reaches the frame; a key it deletes comes back, and the column stays. Writing to a cell past the end of a short column is dropped rather than growing the column. A block that keeps
$_(pushes it somewhere, or returns it) keeps that one view, which shows whichever row was visited last. A tied HoA, or one with a tied column, is the exception: its view is a fresh hash of copies on every row. -
It modifies your data frame. If you need to keep the original, pass a copy:
assign(clone($df), ...). -
Reusing a column name overwrites that column.
auc
The area under the ROC curve (the c-statistic) for scores and 0/1 labels: the
chance a random positive scores higher than a random negative. 1.0 is perfect,
0.5 is a coin flip.
use Stats::LikeR 'auc';

my $auc = auc(\@scores, \@labels); # e.g. 0.848
Options: positive (which label is the positive class, default 1) and
direction ('>' = higher score is more positive, the default; '<' flips it).
For the full curve and a confidence interval, see roc.
auroc
The same number as auc, but with the argument order of Python's
sklearn.metrics.roc_auc_score — labels first, scores second — so code
ported from scikit-learn works unchanged. Higher score means the positive class.
use Stats::LikeR 'auroc';

my $a = auroc(\@labels, \@scores);          # like roc_auc_score(y, s)
Options: positive (which label is the positive class, default 1) and
direction ('<' treats a lower score as more positive, i.e. the same as
sklearn's roc_auc_score(y, -pred)). It can also turn a numeric column into
labels for you: cutoff => x marks values >= x as positive, or
active_frac => 0.1 with active_side => 'low'|'high' takes that fraction of
the extreme tail as positive.
avals
vals as a list. avals takes the same two arguments, accepts the
same three data-frame shapes, uses the same shape detection, copies every cell
the same way and dies with the same messages — it only differs in the return,
pushing the column's values onto the stack instead of wrapping them in an array
reference:
use Stats::LikeR qw(avals vals);

my @ages =    avals($df, 'age');
my @same = @{  vals($df, 'age') };   # identical, one arrayref later
Reach for it wherever the column is going straight into a list — another
function's arguments, a sort/map/grep chain, a push, an array or hash
slice:
my @sorted = sort { $a <=> $b } avals($df, 'ldl');
push @pooled, avals($df, 'ldl');
The functions that take a column by reference still want vals:
mean(vals($df, 'age')) is right, and mean(avals($df, 'age')) hands mean a
bare list instead of the arrayref it expects.
An empty frame — an empty AoH, or an empty hash — yields the empty list. In
scalar context a list return collapses to its last element, which for a column
is almost never what was meant; assign to an array, or use vals.
See vals for the argument table, the AoH / HoA / HoH detection rules,
the sorted key order of a HoH, and the missing-column behavior: apart from the
return, they are the same function.
bedroc
BEDROC — Boltzmann-Enhanced Discrimination of ROC (Truchon & Bayly, J. Chem.
Inf. Model. 2007) — is an early-recognition metric. Unlike auc,
which weights a correct ranking equally everywhere, BEDROC rewards actives
(positives) that appear near the top of a score-sorted list far more than
actives buried deep in it. That is what you want when only the first handful of
ranked candidates will ever be followed up (virtual screening, prioritised
review, triage). The result lies in [0, 1]: 1 is ideal early recognition,
0 is the worst possible ranking.
use Stats::LikeR 'bedroc';

my $r = bedroc(\@scores, \@labels, alpha => 20);
print $r->{bedroc};             # e.g. 0.9989
@scores is the ranking score for each item and the second array marks which
items are active. The single tuning knob is alpha, the early-recognition
weight: larger alpha concentrates the emphasis on a smaller top fraction of
the list. The Truchon–Bayly default is 20 (roughly 80% of the score comes
from the top 8% of the ranking). Ties in the scores are resolved with average
(mid)ranks.
Easier to use than the usual Python implementations. The common Python
recipes either demand a pre-built 0/1 label array (sklearn-style
bedroc_score(y_true, scores)) or hand-roll a bespoke "regression variant" in
each script that binarizes a continuous target by fraction. This bedroc folds
both jobs into one call: hand it a raw numeric column and let cutoff or
active_frac (below) define the actives for you — no separate label-building
step, and it never dies just because you passed a continuous column where a 0/1
vector was expected. active_frac => 0.10, active_side => 'low' reproduces the
Pep-PriML regression BEDROC (actives = strongest binders, the lowest-ΔG 10%) to
machine precision in a single line.
Options
alpha— early-recognition weight, must be> 0(default20).positive— label value that marks an active, compared as a string (default1). Ignored whencutoffis given.cutoff— instead of class labels, treat the second array as a numeric column and count an item as active when its value is>= cutoff. Handy when "active" is defined by a measured quantity (an affinity, a titre, an expression level) rather than a pre-baked 0/1 label.active_frac(aliasactive) — a fraction in(0, 1). Binarizes the second array by marking the most extremeceil(active_frac * n)items as active (seeactive_side). This is the one-call convenience that removes the "build a 0/1 label first" step; the count is clamped to[1, n-1]so both classes always exist and the call never dies for want of a label. Mutually exclusive withcutoff.active_side— which tailactive_fractakes:'high'(default) marks the largest values active (matchingcutoff's>=sense);'low'marks the smallest (e.g. actives = strongest binders when the column is ΔG).direction—'>'(default) means a higher score ranks first;'<'flips it so lower scores rank first.top(aliasfraction) — a fraction in(0, 1]. When given, the result also reports classic enrichment in the top slice of the ranking (see below).
Result keys
bedroc— the BEDROC score in[0, 1].rie,rie_min,rie_max— the underlying Robust Initial Enhancement and its bounds for thisalphaand active fraction; BEDROC isrierescaled onto[0, 1].n,n_active,n_inactive— counts.ra— the active fractionn_active / n.alpha,direction,method— the settings used, echoed back.enrichment— present only whentopwas given; a hashref withfraction,n_top(compounds in the top slice,ceil(top * n)),active_count(actives found there),expected(actives expected by chance,ra * n_top), andenrichment_factor((active_count / n_top) / ra).
Examples
# cutoff-defined actives (value >= 6.5) plus top-5% enrichment
my $r = bedroc(\@scores, \@affinity,
    alpha  => 20,
    cutoff => 6.5,
    top    => 0.05);
print $r->{bedroc};
print $r->{enrichment}{'enrichment_factor'}; # e.g. 2.0 => 2x over random

# fraction-defined actives straight from a raw ΔG column: the strongest-
# binding 10% (lowest ΔG) are the actives, best predictions rank first.
# No pre-built 0/1 label, no per-script regression variant.
my $b = bedroc(\@predicted, \@delta_G,
    alpha       => 32.2,
    active_frac => 0.10,
    active_side => 'low',    # lowest ΔG = strongest binders = actives
    direction   => '<');     # lower predicted ΔG ranks first
print $b->{bedroc};

# lower score = better ranker
bedroc(\@scores, \@labels, direction => '<');

# string labels
bedroc(\@scores, ['case','ctrl',...], positive => 'case');
Call h('bedroc') for this section at the prompt. bedroc also carries its own
short usage summary in XS, printed by bedroc('h'), bedroc('H') or
bedroc('?'); it is the one function that reads its arguments that way. See
Getting help.
bfill
Back-fill NA (undef) cells with the next valid value seen below them along the
row axis, like pandas.DataFrame.bfill. See ffill for the forward direction
and fillna for constant fills.
bfill($df,
    cols  => [ 'v' ],   # restrict to these columns (default: every column)
    limit => 2,         # max consecutive fills per gap (default: unlimited)
);
Column identifiers are names for AoH/HoA/HoH and 0-based positions for AoA. The row axis is positional for AoA/AoH/HoA and string-sorted key order for HoH (the only deterministic order a HoH has). Filling stays within each column's existing length: ragged HoA columns are not extended, and AoA rows are not extended past their own length.
limit caps the number of consecutive NA cells filled in a single gap; the
remaining cells in an over-long gap stay NA, and the count resets after the
next real value. A trailing run of NA (with nothing below it) is left as NA.
Returns a NEW frame; the input is never modified.
Example
bfill([ { v => undef }, { v => 2 }, { v => undef } ], cols => [ 'v' ]);
# [ { v => 2 }, { v => 2 }, { v => undef } ]   # trailing NA stays

bfill({ b => { x => undef }, a => { x => 5 }, c => { x => undef } }, cols => [ 'x' ]);
# sorted-key order a,b,c; nothing after a to pull back, so:
# { a => { x => 5 }, b => { x => undef }, c => { x => undef } }
Errors
Dies on: undefined data; an odd trailing argument list; an unknown argument; a
cols column that does not exist; or a limit that is not a positive integer.
binom_test
binom_test answers one question: you ran a yes/no experiment n times and
got x successes — is that consistent with some assumed success rate, or is it
too far off to be chance? It is the exact binomial test, the same as R's
binom.test.
A toddler and two cards
Show a toddler two cards each round and ask him/her to point at the one with the
star. If he/she is only guessing, he/she will be right half the time, so the
"pure guessing" success rate is p = 0.5.
You play 10 rounds and the toddler gets 6 right. Real skill, or just luck?
use Stats::LikeR 'binom_test';

my $r = binom_test(6, 10, p => 0.5); # 6 wins, 10 rounds, guessing rate 0.5

print $r->{'p_value'};               # 0.7539
The full result is a hashref:
{
    statistic   => 6,            # times the toddler was right
    parameter   => 10,           # rounds played
    estimate    => 0.6,          # observed rate, 6/10
    null_value  => 0.5,          # the "pure guessing" rate we test against
    p_value     => 0.7539,
    conf_int    => [0.262, 0.878],
    conf_level  => 0.95,
    alternative => 'two.sided',
    method      => 'Exact binomial test',
}
Reading the p-value
The p-value is the chance of seeing a result at least this surprising if the toddler were really just guessing.
Here p = 0.75 means no evidence of skill.
What "legit" would look like
Suppose the toddler had gone 9 for 10 instead:
my $r = binom_test(9, 10, p => 0.5);

print $r->{'p_value'};                 # 0.0215
Now p = 0.02, under 0.05. A pure guesser almost never does that well, so
this is good evidence the toddler can actually tell the cards apart.
The confidence interval
conf_int is the plausible range for the toddler's true success rate. For
6/10 it runs from about 0.26 to 0.88 — wide, and it comfortably includes
0.5. That overlap with the guessing rate is another way of seeing that luck
cannot be ruled out. For 9/10 the interval would sit well above 0.5.
Options
pis the assumed success rate (default0.5).alternativeis'two.sided'(default),'less', or'greater'. Use'greater'when you only care whether the toddler beats guessing, not whether they do worse.conf_levelsets the interval width (default0.95).
You can also pass the counts as binom_test([6, 4]) — 6 right, 4 wrong — when
you have wins and losses instead of wins and a total.
cfilter
Select columns out of a table and return it in the same shape. A column is the inner (second-level) key of a hash of hashes or an array of hashes, or the outer key of a hash of arrays:
use Stats::LikeR;
my %hoa = ( x => [1,2,3], y => [4,5,6], z => [0,0,0] );
cfilter(\%hoa, keep   => ['x','y']);  # { x => [1,2,3], y => [4,5,6] }
cfilter(\%hoa, remove => ['z']);      # { x => [1,2,3], y => [4,5,6] }
cfilter takes exactly one of keep or remove. keep returns only the
matching columns; remove returns everything except them. The result is the
same shape as the input (HoH → HoH, HoA → HoA, AoH → AoH), with cell values
copied and the original structure left untouched. That includes the position
of an each loop you are part-way through on the data or on one of its rows,
which carries on where it was. Tied hashes and arrays are accepted anywhere in
the data.
The selector — the value of keep or remove — can be given three ways:
- an array ref of exact column names,
- a
qr//regex matched against column names, - a predicate (CODE ref or function name) evaluated against a column's values.
The first two select by name; the predicate is the one that looks at the data.
Selecting by name
Pass an array ref of column names. Naming a column that is not present in the data is an error (it catches typos), and a row that happens not to contain a kept column simply comes back without it:
my @aoh = ( { a => 1, b => 2 }, { a => 3 } );
cfilter(\@aoh, keep => ['b']);   # [ { b => 2 }, {} ]
Selecting by a name pattern
Pass a qr// regex, and columns are kept (or removed) according to whether
their name matches. This is the concise way to act on a family of columns:
# drop every column whose name contains "step" or "bias_"
cfilter(\%md, remove => qr/(?:step|bias_)/);
# keep only the y0, y1, ... columns
cfilter(\%md, keep => qr/^y\d+$/);
The pattern matches anywhere in the name (it is not anchored), exactly like
Perl's =~. Unlike a named column, a pattern that matches nothing is not an
error — it simply keeps or removes nothing.
Selecting by a predicate
Instead of names, keep/remove accept a predicate — a CODE ref or a
function name — evaluated once per column. It is called as
$predicate->($column_values, $column_name)
where $column_values is an array ref of a copy of every cell in the
column, in row order, with undef standing in for an undef or missing cell.
With keep, columns for which the predicate is true are kept; with remove,
those columns are dropped.
Two options change what the predicate is given, for functions that cannot take undef:
na => 'omit'drops the undef and missing cells, so a one-column function such assdgets clean input.na => 'keep'is the default described above.against => 'col'compares every column with the column namedcol. The predicate is called with three arguments,$predicate->($column_values, $col_values, $column_name), and both arrays hold only the rows where both columns are defined (pairwise complete), so a two-column function such ascorcan take them directly.
na and against cannot be given together.
# Keep only the constant columns (standard deviation zero):
my $const = cfilter(\%hoa, keep => sub { sd($_[0]) == 0 });   # { z => [0,0,0] }
# Drop the constant columns instead:
my $varying = cfilter(\%hoa, remove => sub { sd($_[0]) == 0 }); # { x=>..., y=>... }
# A bare function name resolves in Stats::LikeR:: (use a package for your own):
cfilter(\%hoa, keep => 'some_predicate');
# Drop the constant columns of data with gaps: sd() gets only defined cells
cfilter(\%gappy, remove => sub { sd($_[0]) == 0 }, na => 'omit');
# Keep the columns strongly correlated with y (y itself included)
cfilter(\%hoa, keep => sub { abs(cor($_[0], $_[1])) > 0.9 }, against => 'y');
A bare string is always treated as a function name, not a single column
name, so to keep one column by name use an array ref: keep => ['x'].
Errors
cfilter dies (via croak) when:
- neither
keepnorremoveis given, or both are, - a named column is not present in the data,
- the selector is not an array ref, a
qr//regex, or a code ref / function name, or the function name cannot be resolved, naoragainstis given with a by-name or regex selector (they apply only to a value predicate), both are given,nais not'keep'or'omit', or theagainstcolumn is not present in the data,- the predicate itself dies, or replaces a row or column of the data with
something of the wrong shape while
cfilteris running, - an unknown option is given, or the options are not
name => valuepairs, - the data is not a hash/array reference of the expected shape (a hash of hash refs or array refs, or an array of hash refs).
chisq_test
The chisq_test function performs chi-squared contingency table tests and goodness-of-fit tests. It natively accepts both arrays and hashes (1D and 2D) and mathematically mirrors R's chisq.test(), returning a structured hash reference of the results.
For 2x2 matrices, Yates' Continuity Correction is applied automatically.
Signature
my $res = chisq_test($data);
my $res = chisq_test($data, correct     => 0);          # 2x2: no Yates' correction
my $res = chisq_test($data, p           => $probs);     # goodness of fit against $probs
my $res = chisq_test($data, p           => $weights,
                            'rescale_p' => 1);          # ... rescaled to sum to 1
Accepted Inputs
| Input Type | Data Structure | Applied Test |
| --- | --- | --- |
| 1D Array | [ $v1, $v2, ... ] | Chi-squared test for given probabilities |
| 2D Array | [ [ $v1, $v2 ], [ $v3, $v4 ] ] | Pearson's Chi-squared test (Yates' correction if 2x2) |
| 1D Hash | { key1 => $v1, key2 => $v2 } | Chi-squared test for given probabilities |
| 2D Hash | { row1 => { c1 => $v1, c2 => $v2 } } | Pearson's Chi-squared test (Yates' correction if 2x2) |
Every entry must be a nonnegative, finite number, and at least one of them must be positive; anything else — an undef, a string, a negative count, an infinity — is a fatal error rather than a silent zero, exactly as in R. A 2D array must not be ragged, and every row of a 2D hash must carry the same column keys.
A table with only one row or only one column is not a contingency table: as in R, it collapses to its cells and the goodness-of-fit test is run on them. So [[10, 20, 30]] and [10, 20, 30] give the same test, with df = 2 — not the vacuous df = 0.
As in R, a warning is issued when any expected count falls below 5, the usual rule of thumb for the chi-squared approximation being trustworthy. Use fisher_test for a small table.
Named Options
| Option | Default | Description |
| --- | --- | --- |
| correct | 1 | Apply Yates' continuity correction. Only ever affects a 2x2 table, and is R's correct. Set to 0 for the uncorrected Pearson statistic. |
| p | uniform | Null probabilities for the goodness-of-fit test. An array ref, in the order of the data, when the data is an array ref; a hash ref keyed the same as the data when the data is a hash ref. They must sum to 1 unless rescale_p says otherwise, and it is an error to pass them with a contingency table. |
| rescale_p | 0 | Divide p by its own sum first, so counts, weights or percentages can be passed instead of probabilities. R's dotted rescale.p is refused as an unknown argument. |
# goodness of fit against a non-uniform null
my $res = chisq_test([89, 37, 30, 28, 2],
                     p => [0.40, 0.20, 0.20, 0.19, 0.01]);
# $res->{statistic}{'X-squared'} == 5.79470854555744, df 4, p == 0.215013095920786

# the same, from unnormalised weights
my $res = chisq_test([89, 37, 30, 28, 2],
                     p => [40, 20, 20, 19, 1], 'rescale_p' => 1);

# keyed data takes keyed probabilities
my $res = chisq_test({ A => 10, B => 20, C => 30 },
                     p => { A => 0.2, B => 0.3, C => 0.5 });
Output Object Structure
The function returns a single Hash Reference containing the following key-value pairs. The internal structure of expected and observed will always identically match the structure of your input.
| Key | Data Type | Description |
| --- | --- | --- |
| data_name | String | Identifies the input type (e.g., "Perl ArrayRef" or "Perl HashRef"). |
| expected | Array/Hash Ref | The expected frequencies, matching the geometry of the input. |
| method | String | The specific statistical test applied. |
| observed | Array/Hash Ref | The original data passed to the function. |
| p_value | Float | The calculated p-value of the test. |
| parameter | Hash Ref | Contains the degrees of freedom (df). |
| statistic | Hash Ref | Contains the test statistic (X-squared). |
Two-Dimensional Array
Passing an Array of Arrays (AoA) triggers a standard Pearson's Chi-squared test. If the input is exactly a 2x2 matrix, Yates' continuity correction is applied automatically.
my $test_data = [
    [762, 327, 468],
    [484, 239, 477]
];
my $res = chisq_test($test_data);
Output:
{
    'data_name' => 'Perl ArrayRef',
    'expected'  => [
        [ 703.671381936888, 319.645266594124, 533.683351468988 ],
        [ 542.328618063112, 246.354733405876, 411.316648531012 ]
    ],
    'method'    => "Pearson's Chi-squared test",
    'observed'  => [
        [ 762, 327, 468 ],
        [ 484, 239, 477 ]
    ],
    'p_value'   => 2.95358918321176e-07,
    'parameter' => { 'df' => 2 },
    'statistic' => { 'X-squared' => 30.0701490957547 }
}
1-Dimensional Array (Goodness of Fit)
Passing a flat Array Reference triggers a Goodness of Fit test, assuming equal expected probabilities across all items.
my $data = [10, 20, 30];
my $res = chisq_test($data);
Output:
{
    'data_name' => 'Perl ArrayRef',
    'expected'  => [ 20, 20, 20 ],
    'method'    => 'Chi-squared test for given probabilities',
    'observed'  => [ 10, 20, 30 ],
    'p_value'   => 0.00673794699908547,
    'parameter' => { 'df' => 2 },
    'statistic' => { 'X-squared' => 10 }
}
2-Dimensional Hash (Pearson's Chi-squared)
Passing a Hash of Hashes (HoH) applies the exact same logic as a 2D Array, but preserves your nested string keys in the output. This is particularly useful when mapping data extracted directly from JSON, databases, or categorical mappings.
my $data = {
    GroupA => { Success => 10, Failure => 15 },
    GroupB => { Success => 20, Failure => 5  }
};

my $res = chisq_test($data);
Output:
{
    'data_name' => 'Perl HashRef',
    'expected'  => {
    'GroupA' => { 'Failure' => 10, 'Success' => 15 },
    'GroupB' => { 'Failure' => 10, 'Success' => 15 }
},
'method'    => "Pearson's Chi-squared test with Yates' continuity correction",
    'observed'  => {
    'GroupA' => { 'Failure' => 15, 'Success' => 10 },
    'GroupB' => { 'Failure' => 5,  'Success' => 20 }
    },
    'p_value'   => 0.00937475878430379,
    'parameter' => { 'df' => 1 },
    'statistic' => { 'X-squared' => 6.75 }
}
One-Dimensional Hash (Goodness of Fit)
Flat Hash References evaluate Goodness of Fit while preserving your categorical keys in the expected and observed output blocks.
my $data = {
	Apples  => 10,
	Oranges => 20,
	Bananas => 30
};

my $res = chisq_test($data);
chunk
Split an array into contiguous, roughly equal groups by position. Unlike
qcut, chunk does not inspect values, sort, or compute cutpoints; it
slices the array in the order given. Use it for batching work, paginating, or
grouping non-numeric data such as strings.
Signature
my @groups = chunk($data, size  => $n);   # fixed elements per group
my @groups = chunk($data, parts => $k);   # fixed number of groups
$data— an array reference. Its contents are never examined or sorted; elements are grouped in input order.
Pass exactly one of size or parts. Passing both, or neither, is a fatal
error — the two readings of "equal groups" differ (see below), so the caller
chooses which one is meant rather than relying on a default.
size => $n— each group holds$nelements; the final group holds whatever remains.parts => $k— the array is divided into$kgroups as equal as possible, with any remainder spread across the leading groups.
Return value
A list of array references, in input order — call it in list context:
my @groups = chunk($data, parts => 4);
Passing more parts than there are elements yields trailing empty groups
(matching numpy.array_split), so no elements are ever dropped. An empty input
array returns an empty list.
Examples
size fixes the elements per group; the last group is the remainder. Splitting
the 26 letters into groups of five leaves one over:
my @groups = chunk(['a' .. 'z'], size => 5);
# 6 groups, sizes 5,5,5,5,5,1
# [a b c d e] [f g h i j] [k l m n o] [p q r s t] [u v w x y] [z]
parts fixes the number of groups; the remainder is absorbed by the leading
groups instead:
my @groups = chunk(['a' .. 'z'], parts => 5);
# 5 groups, sizes 5,5,5,5,6
# [a b c d e] [f g h i j] [k l m n o] [p q r s t] [u v w x y z]
When the split is even the two forms agree:
my @a = chunk([1 .. 10], size  => 2);
my @b = chunk([1 .. 10], parts => 5);
# identical: 5 groups of 2
Order is preserved — chunk never sorts. Sort the array yourself first if you
want ordered groups:
my @groups = chunk([3, 1, 2], size => 2);
# ([3, 1], [2])
More parts than elements gives empty trailing groups, losing nothing:
my @groups = chunk([1, 2, 3], parts => 5);
# 5 groups; flattening them back gives (1, 2, 3)
cmh_test
The Cochran–Mantel–Haenszel test: pool several 2×2 tables (one per stratum)
into a single test of association while adjusting for the stratifying variable —
e.g. an exposure/outcome odds ratio adjusted for study site. Same as R's
mantelhaen.test.
use Stats::LikeR 'cmh_test';

my $r = cmh_test([ [10,3,5,12],     # stratum 1 as [a,b,c,d]
                   [20,6,8,15],     # stratum 2
                   [ 7,4,9,11] ]);  # stratum 3

print $r->{'p_value'};  # combined test across strata
print $r->{estimate};   # Mantel–Haenszel common odds ratio
Each 2×2 uses the same layout as epi_2x2. Options: correct
(continuity correction, default 1) and conf_level (default 0.95). The
result also has statistic (chi-squared), parameter (df = 1), conf_int (for
the common OR), and k (number of strata).
cohen_d
Cohen's d effect size for the difference between two independent groups, using the pooled standard deviation. It also returns the Hedges' g small-sample correction and a large-sample (normal-approximation) confidence interval. Validated numerically against R.
my $d = cohen_d(\@treatment, \@control);           # or conf_level => 0.90
printf "d = %.2f (95%% CI %.2f–%.2f), Hedges g = %.2f\n",
    $d->{estimate}, $d->{'conf_int'}[0], $d->{'conf_int'}[1], $d->{hedges_g};
Compare with smd, which standardizes by the simple (unweighted) average of the group variances and is the convention for covariate-balance tables.
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| estimate | Double | Cohen's d (mean₁ − mean₂ over the pooled SD). | 2.3146 |
| hedges_g | Double | Hedges' g (bias-corrected d). | 2.1668 |
| pooled_sd | Double | Pooled standard deviation. | 1.2344 |
| se | Double | Approximate standard error of d. | 0.6907 |
| conf_int | ArrayRef | [lower, upper] normal-approximation CI for d. | [0.96, 3.67] |
| conf_level | Double | Confidence level used. | 0.95 |
| n1, n2 | Integer | Group sizes. | 7, 7 |
col2col
Apply a two-column function to every pair of columns in a table and collect the answers in a hash of hashes.
It's the workhorse behind things like correlation matrices: give it your data and
the name of a function that takes two columns (cor, t_test, …) and you get
back every column compared against every other column.
use Stats::LikeR;

my %data = (
    height => [ 170, 165, 180, 175 ],
    weight => [  70,  60,  85,  77 ],
    age    => [  30,  41,  25,  38 ],
);

my $result = col2col(\%data, 'cor');

# $result->{height}{weight}  == correlation of height vs weight
# $result->{height}{age}     == correlation of height vs age
# ...and so on for every pair
Arguments
col2col( $data, $command, $cols, %options )
col2col( $data, $command, \%options )      # options in place of $cols
| Position | Argument | What it is |
|----------|-------------|------------|
| 1 | $data | Your table, as a reference (see Data shapes below). |
| 2 | $command | A code block or the name of a two-column function. |
| 3 | $cols | (optional) Which columns to use as the "from" side. Omit for all. |
| 4+ | %options | (optional) na, skip_errors, … (see Options). |
Data shapes
col2col understands three layouts. In every case a column is the thing that
gets compared, and the result is keyed by column name.
Hash of arrays (HoA) — keys are column names:
my %hoa = ( a => [1, 2, 3], b => [4, 5, 6] );
Hash of hashes (HoH) — First keys are row names, second keys are columns:
my %hoh = (
    row1 => { a => 1, b => 4 },
    row2 => { a => 2, b => 5 },
);
Array of hashes (AoH) — each element is a row, inner keys are columns:
my @aoh = ( { a => 1, b => 4 }, { a => 2, b => 5 } );
All three produce the same result for the same underlying numbers. Missing or
undef cells are handled by the na option (below).
The command
The second argument is the function applied to each pair of columns. It is called as:
$command->( $column_a, $column_b ) # two ARRAY refs
so inside a block the two columns arrive in @_:
my $result = col2col(\%data, sub {
    my ($x, $y) = @_;       # $x and $y are array refs
    cor($x, $y);
});
You can also pass a function name as a string. A bare name is looked up in
Stats::LikeR::, so these two are equivalent:
col2col(\%data, 'cor');
col2col(\%data, sub { cor($_[0], $_[1]) });
The result
Always a hash of hashes: $result->{from}{to}.
for my $from (sort keys %$result) {
   for my $to (sort keys %{ $result->{$from} }) {
      printf "%s vs %s = %s\n", $from, $to, $result->{$from}{$to};
   }
}
A column is never compared with itself, so $result->{a}{a} does not exist.
Restricting columns ($cols)
By default every column is used as the "from" side. The third argument narrows that down — handy when you only care about one variable.
# all columns vs all columns
my $all = col2col(\%data, 'cor');
# just ONE column vs every other column
my $one = col2col(\%data, 'cor', 'height');
my $cors = $one->{height};          # { weight => ..., age => ... }
# a FEW specific columns vs every other column
my $few = col2col(\%data, 'cor', ['height', 'weight']);
The "to" side is always every other column; $cols only limits the outer keys.
Options
Options can be given two ways:
col2col(\%data, 'cor', $cols, 'skip_errors' => 0);   # after $cols
col2col(\%data, 'cor', { 'skip_errors' => 0 });      # hash ref, no $cols needed
The hash-ref form is convenient when you have no column restriction — it saves
you from passing a placeholder. (A hash ref replaces $cols, so you can't use
it to restrict columns at the same time; use the trailing form for that.)
na — how undefined values are handled
Real data has gaps. na decides what the function sees.
| Value | Behaviour | Use for |
|-------------------------|-----------|---------|
| 'pairwise' (default)| A row is used for a pair only if both columns are defined there. The two columns arrive aligned and equal-length. | Paired stats like cor. |
| 'omit' | Each column drops its own undefined values independently. The two columns may end up different lengths. | Unpaired tests like t_test, kruskal_test, where a gap in one sample shouldn't discard a value in the other. |
| 'keep' | Every row is passed through, undef and all. | When your function does its own missing-data handling. |
# correlation: keep only complete pairs (the default)
col2col(\%data, 'cor');
# two-sample test: each column keeps its own values
col2col(\%data, 't_test', undef, na => 'omit');
col2col(\%data, 't_test', { na => 'omit' });        # same, no placeholder
rm_undef / rm_na remain as boolean aliases for backward compatibility:
true means 'pairwise', false means 'keep'. Don't combine them with na.
The old dotted spellings rm.undef and rm.na are refused as unknown options.
skip_errors — keep going when a pair fails (default: true)
Some functions croak on degenerate input — for example cor dies if a column has
zero variance. By default col2col traps that croak per pair: instead of
aborting the whole run, it stores the first line of the error message in that
cell, so the result tells you which pair failed and why. Every other cell is
computed normally.
my $r = col2col(\%data, 'cor');
# a good pair:   $r->{a}{b} == 0.83
# a bad pair:    $r->{a}{const} eq 'cor: standard deviation of y is 0'
To restore the old "die on the first error" behaviour, turn it off:
col2col(\%data, 'cor', undef, 'skip_errors' => 0);
col2col(\%data, 'cor', { 'skip_errors' => 0 });
Only errors from your function are trapped. Mistakes in the call itself (unknown column, bad data, unknown function name, unknown option) always die.
Worked examples
Full correlation matrix:
my $m = col2col(\%data, 'cor');
One variable against all others, sorted strongest first, skipping failures:
my $col  = 'Testosterone, total (nmol/L)';
my $cors = col2col($hoa, 'cor', $col)->{$col};
for my $other (sort { ($cors->{$b} // -2) <=> ($cors->{$a} // -2) } keys %$cors) {
    next unless $cors->{$other} =~ /^-?\d/;        # skip cells holding an error message
    printf "%-30s % .3f\n", $other, $cors->{$other};
}
Two-sample test across columns of unequal completeness:
my $t = col2col($hoa, 't_test', undef, na => 'omit');
Find which pairs could not be computed:
my $m = col2col($hoa, 'cor');
for my $from (sort keys %$m) {
    for my $to (sort keys %{ $m->{$from} }) {
        my $v = $m->{$from}{$to};
        warn "$from vs $to: $v\n" if defined $v && $v !~ /^-?\d/;   # non-numeric = error
    }
}
Gotchas
- Your function receives two array refs,
($col_a, $col_b)— not a column and a name. Unpack withmy ($x, $y) = @_;. 'pairwise'can still hit a constant subset. A column with overall variance can be flat on just the rows it shares with one partner, socormay still croak for that pair. With the defaultskip_errors, that shows up as a message in the single offending cell rather than killing the run.col2coldoes not modify your data. It reads the table and returns a new hash of hashes.- In the error message, "x" is the first column and "y" is the second — i.e.
yis the inner ("to") key. So$result->{A}{B}reading…deviation of y is 0means columnBis the degenerate one for that pair.
colnames
Return the column names of a data frame, as a list (like R's colnames).
Works on all four Stats::LikeR frame shapes and mirrors the column order
view shows:
AoA— 0-based integer indices,0 .. widest_row-1AoH— the string-sorted union of the keys of every rowHoA— the string-sorted keys (the keys are the columns)HoH— the string-sorted union of the inner-row keys
In scalar context it returns the count, so scalar colnames($df) equals
ncol($df) for a rectangular frame.
my $aoh = [ { b => 2, a => 1 }, { a => 3, c => 9 } ];
my @cols = colnames($aoh);        # ('a', 'b', 'c')  -- union, sorted

my $hoa = { z => [1,2], a => [3,4], m => [5,6] };
my @cols = colnames($hoa);        # ('a', 'm', 'z')

my $aoa = [ [1,2,3], [4,5,6] ];
my @cols = colnames($aoa);        # (0, 1, 2)

my $n = colnames($hoa);           # 3  (scalar context == ncol)
concat
Row-bind two or more data frames: stack their rows into one new frame, the
analog of pandas concat(..., axis=0) and R's rbind. rbind is provided as a
true synonym (the same subroutine), so the two names are interchangeable.
concat accepts all four data-frame shapes and returns a new frame of that same
shape:
AoA  [ [ .. ], [ .. ] ]      array of arrayrefs   (positional columns)
AoH  [ { .. }, { .. } ]      array of hashrefs    (the read_table default)
HoA  { c => [ .. ], .. }     hash of arrayrefs    (column-major)
HoH  { r => { .. }, .. }     hash of hashrefs     (named rows)
Every frame must be the same shape; mixing shapes dies with a hint to convert
first (aoh2hoa, hoa2aoh, hoh2hoa, aoh2hoh). undef frames and empty
frames are skipped, and the shape is taken from the first non-empty frame. The
original frames are never modified.
Usage
use Stats::LikeR;

my $all = concat($df1, $df2, $df3);   # any number of frames
my $all = rbind($df1, $df2);          # identical: rbind is a synonym
Array of Arrays (AoA)
The outer arrays are concatenated in order and the row arrayrefs are reused by reference (not copied). Ragged rows are kept as-is; reading past a short row yields undef.
my $a = [ [ 1, 2 ], [ 3, 4 ] ];
my $b = [ [ 5, 6 ], [ 7 ]    ];   # ragged last row
my $c = concat($a, $b);
Resulting Structure:
[ [ 1, 2 ], [ 3, 4 ], [ 5, 6 ], [ 7 ] ]
Array of Hashes (AoH)
The rows are concatenated in order and the row hashrefs are reused by reference.
The result is the union of columns; a column absent from a given row simply
reads as undef, matching this module's "missing key means undef" convention
(as used by dropna, view, and summary).
my $a = [ { id => 1, x => 10 } ];
my $b = [ { id => 2, x => 20, y => 99 } ];   # extra column y
my $c = concat($a, $b);
Resulting Structure:
[
    { id => 1, x => 10           },   # no 'y' key -> reads as undef
    { id => 2, x => 20, y => 99  },
]
Hash of Arrays (HoA)
The output columns are the union of all input columns, sorted for a deterministic layout. Each column is the per-frame arrays joined in frame order. Because HoA is column-major, a column missing from a frame — or a ragged short column within a frame — is padded with undef so every output column ends up the same length (the total number of rows).
my $a = { g => [ 'a', 'a' ], v => [ 1, 2 ] };
my $b = { g => [ 'b' ],      w => [ 9 ]    };   # v absent here, w is new
my $c = concat($a, $b);
Resulting Structure:
{
    g => [ 'a',   'a',   'b' ],
    v => [ 1,     2,     undef ],   # padded for the frame that lacked 'v'
    w => [ undef, undef, 9     ],   # padded for the frame that lacked 'w'
}
Hash of Hashes (HoH)
The outer hashes are merged in frame order and the inner row hashrefs are reused
by reference. Because a Perl hash cannot hold duplicate keys, a repeated row
name is made unique R-style — name, name.1, name.2, … — and a single
warning is emitted noting that row names collided.
my $a = { r => { v => 1 } };
my $b = { r => { v => 2 } };
my $c = concat($a, $b);
# warns: concat: duplicate HoH row name(s) made unique with a .N suffix
Resulting Structure:
{
    r     => { v => 1 },
    'r.1' => { v => 2 },
}
Empty and single inputs
undef and empty frames are skipped, so they can be threaded through a pipeline harmlessly:
concat(undef, [], [ { n => 1 } ], [ { n => 2 } ]); # two rows
When every frame is empty the result is an empty frame matching the first
argument's reference type ([] for an arrayref, {} for a hashref). A single
frame round-trips unchanged.
rbind
rbind is the same subroutine as concat, exported under a second name for
readers who know it from R:
my $c = rbind($df1, $df2);

# they are literally the same code reference:
\&Stats::LikeR::rbind == \&Stats::LikeR::concat;   # true
Errors
concat (and therefore rbind) dies (with a trailing newline) when:
- no usable frame is given;
- a frame is neither an ARRAY nor a HASH ref;
- the frames are not all the same shape (the message names the two shapes and suggests the relevant converter);
- an AoA element is not an arrayref, or an AoH/HoH row is not a hashref.
See also
agg (split-apply-combine), add_data (which also appends HoA columns and
merges HoH rows), ljoin, aoh2hoa, hoa2aoh, hoh2hoa, aoh2hoh.
cor
cor($array1, $array2, $method = 'pearson'),
that is, pearson is the default and will be used if $method is not specified.
Just like R, pearson, spearman, and kendall are available
If you provide an array of arrays (a matrix), cor will compute the correlation matrix automatically.
cor_test
my $result = cor_test(
		'x'         => $x,
		'y'         => $y,
		alternative => 'two.sided',
		method      => 'pearson',
		continuity  => 1
	);
cor_test safely handles undef (or NA) values seamlessly by computing over pairwise complete observations.
For the spearman and kendall methods, cor_test falls back to a
large-sample normal approximation when n is large or the data contain ties
(and always when you pass exact => 0). That approximation's p_value is
evaluated on the tail it belongs to, so a strong rank correlation reports its
actual p-value instead of a flat 0; see
F and z tail p-values. Checked against R's
cor.test(..., exact = FALSE) over 54 Spearman and Kendall cases spanning
n = 60 to 500 and all three alternatives: estimate agrees to 3e-15,
Kendall's statistic to 2e-15, and p_value to 1.7e-12 — the worst of
those at a p-value of 2.2e-297.
Spearman: which method, and what statistic holds
spearman follows R's cor.test exactly: exact defaults to true, and an
exact request is served by permutation enumeration for n ≤ 9, by the AS 89
Edgeworth series for 10 ≤ n ≤ 1290, and by the asymptotic t above that or
whenever the data contain ties. Passing exact => 1 never enumerates past
n = 9, because n! is 6.2 × 10²³ by n = 24.
statistic is Spearman's S on every one of those paths, formed the way R
forms it — (n³ − n)(1 − ρ)/6, which is the sum of squared rank differences
only when there are no ties. One difference from R remains, and it is not about
the mathematics: at a perfect correlation R's cor() returns a ρ that is
2.2e-16 short of 1, so R reports 3.6637359812630166e-14 for an exact 0 at
n = 10 where the Welford accumulation here returns exactly 1 and so gives
exactly 0. Pinned in t/cor_test.spearman.R.t.
Kendall: ties, and the confidence interval
kendall's normal approximation carries R's full tie correction —
var_S = (v0 − vt − vu)/18 + v1/(2n(n−1)) + v2/(9n(n−1)(n−2))
built from the tie-group sizes of each vector. That branch is reached exactly
when there are ties (without them, and below n = 50, the exact distribution
is used instead), so the correction is never idle. The counts behind it come
from Knight's O(n log n) algorithm, the same one cor uses, which
is why a Kendall cor_test on 64 000 points takes 0.014 s rather than 15.
pearson reports a conf_int, and it follows alternative: a one-sided test
gets a one-sided interval, with the open end at exactly −1 or 1, as R's does.
There is no interval below n = 4, again as in R — Fisher's z has
1/√(n−3) for its standard error, so there is nothing to report. spearman and
kendall return no interval at all, which is also R's behaviour.
cov
cov($array1, $array2, 'pearson')
or
cov($array1, $array2, 'spearman')
or
cov($array1, $array2, 'kendall')
coxph
Cox proportional-hazards regression: how covariates raise or lower the hazard
(the risk of an event over time). It is the survival-analysis counterpart of
glm and reports hazard ratios, like R's survival::coxph (Efron ties).
Give times, an event flag (1 = event, 0 = censored), and one or more covariates
(a single \@x, or [\@x1, \@x2, ...]):
use Stats::LikeR 'coxph';

my $fit = coxph(\@time, \@status, [\@age, \@sex],
                names => ['age', 'sex']);

print $fit->{'exp_coef'}[0];  # hazard ratio for age
print $fit->{'p_value'}[0];   # its p-value
Or name the columns of a data set in a formula, as survival::coxph does. The
response is Surv(time, status), or Surv(start, stop, status) for
counting-process data; covariates expand as they do for lm and
glm (factors, interactions, I(), log()), and strata(g) and
cluster(id) terms are taken out of the covariates and used as below:
my $fit = coxph(formula => 'Surv(tstart, tstop, event) ~ hours + age + strata(tech)',
                data => \%d, cluster => 'child_id');
Counting-process data -- one row per interval (start, stop] over which a
subject's covariates are constant -- is what a time-varying covariate and late
entry both need. A subject is at risk at an event time only in the interval
that covers it. In the positional form give the start times as start => \@t0.
Intervals that span no event contribute nothing and are skipped, as
survival's agreg.fit skips them.
Strata (strata(g) in a formula, or strata => \@g) give each level its
own baseline hazard, with the covariate effects shared.
Robust variance. With a cluster (cluster(id), or cluster => \@id or a
column name), se is the grouped-jackknife (dfbeta) robust standard error that
coxph(..., cluster = id) reports, and the model-based one moves to
naive_se. robust => 1 without a cluster makes each row its own cluster,
which (start, stop] data does not allow: a subject's intervals have to be
grouped by a cluster.
weights are case weights and offset a term with coefficient fixed at 1.
A changepoint profile needs no function of its own: refit over a grid of
candidate thresholds and keep each loglik. The maximum is the estimate; the
thresholds within qchisq(0.95, 1) / 2 = 1.92 of it are a likelihood-ratio
interval, which for a changepoint is only approximate, since the profile is a
step function of c and the usual regularity conditions do not hold.
my @grid = map { 40 + $_ } 0 .. 30;
my %ll;
for my $c (@grid) {
    $d{above} = [ map { $_ > $c ? 1 : 0 } @{ $d{hours} } ];
    $ll{$c} = coxph(formula => 'Surv(tstart, tstop, event) ~ above + age + strata(tech)',
                    data => \%d)->{loglik};
}
my ($best) = sort { $ll{$b} <=> $ll{$a} } @grid;
my @ci = grep { $ll{$best} - $ll{$_} <= 1.92 } @grid;
Options
| Option | Default | Description |
| --- | --- | --- |
| names | x1, x2, ... | Covariate names in the positional form. |
| ties | 'efron' | 'efron' or 'breslow'. |
| conf_level | 0.95 | Level of conf_int. |
| maxit | 20 | Newton iteration limit (R's iter.max, also accepted as iter_max; the dotted spelling is refused). |
| eps | 1e-9 | Convergence tolerance on the relative log-likelihood change, coxph.control(eps = ). |
| start | none | Positional form: interval start times, for (start, stop] data. |
| strata | none | Positional form: one stratum label per row. |
| cluster | none | One cluster label per row, or (formula form) a column name. |
| weights | none | Case weights. |
| offset | none | One offset per row. |
| robust | 0, or 1 with a cluster | Report the robust variance. |
Result
Parallel per-covariate arrays coef (log-HR), exp_coef (HR), se, z,
p_value and conf_int (HR scale), with names; coefficients by name;
var (a matrix) and vcov (a hash of hashes by name), the covariance the standard errors
come from; model-level loglik (at the fit) and loglik_null,
lr_stat/lr_df/lr_p_value (likelihood-ratio test), score_test and
wald_test, n, nevent, iterations and converged. With a robust
variance it adds naive_se and naive_var, robust_score_test, and
n_clusters; with strata, strata lists their labels. See
survfit and logrank_test.
cramers_v
Cramér's V, a measure of association for an r × c contingency table derived from the (uncorrected) Pearson chi-square. Also returns the Bergsma (2013) bias-corrected variant, which is preferable for small samples or sparse tables. Validated numerically against R.
# from a count table
my $v = cramers_v([[10, 20, 30], [15, 25, 10]]);
printf "V = %.3f (bias-corrected %.3f)\n", $v->{estimate}, $v->{bias_corrected};

# or from two parallel categorical vectors (cross-tabulated automatically)
my $v2 = cramers_v(\@exposure, \@outcome);
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| estimate | Double | Cramér's V ∈ [0, 1]. | 0.3124 |
| bias_corrected | Double | Bergsma bias-corrected V. | 0.2828 |
| chisq | Double | Uncorrected Pearson chi-square. | 10.735 |
| df | Integer | Degrees of freedom, (r-1)(c-1). | 2 |
| n | Integer | Table total. | 110 |
csort
Sort a data frame by a column or a custom comparator, returning a new (sorted) copy. The input is never mutated.
my $sorted = csort($data, $by);
my $sorted = csort($data, $by, $output_shape);
my $sorted = csort($hoh,  $by, 'aoh', 'row_name');   # HoH only
$data may be any of four shapes:
AoH   array-of-hashes    [ { col => val, ... }, ... ]   columns are hash keys
HoA   hash-of-arrays      { col => [ val, ... ], ... }   columns are hash keys
HoH   hash-of-hashes      { rowname => { col => val }, ... }
AoA   array-of-arrays    [ [ val, ... ], ... ]           columns are integer indices
The shape is detected automatically. An array-ref whose first row is itself an array-ref is treated as an AoA; otherwise an array-ref is an AoH. A hash-ref whose first value is a hash-ref is a HoH (its outer keys are folded into a row-name column, see below); any other hash-ref is a HoA.
$by selects the sort key:
'No.'                          # a column: name (AoH/HoA/HoH) or integer index (AoA)
2                              # AoA: sort by column index 2
sub { $a->{'No.'} <=> $b->{'No.'} }   # comparator; $a/$b are the rows
For a column sort the values are compared numerically when every present
value looks like a number, and with string cmp otherwise. For a
comparator, $a and $b are the row references (a hash-ref for
AoH/HoA/HoH, an array-ref for AoA), exactly as with Perl's own sort.
Sorting an AoA
Columns in an AoA are addressed by non-negative integer index:
my $rows = [
    [ 3, 30, 'gamma' ],
    [ 1, 10, 'alpha' ],
    [ 2, 20, 'beta'  ],
];

my $s = csort($rows, 0);       # by column 0 -> id 1, 2, 3
my $s = csort($rows, 2);       # by column 2 -> alpha, beta, gamma
my $s = csort($rows, sub { $b->[1] <=> $a->[1] });   # by column 1, descending
The result reuses the original row array-refs (a reorder, not a deep copy), so it is cheap and the caller's data is left untouched. A non-integer or negative index croaks; an index no row contains is reported as a missing column.
Undefined and missing values
Undefined or missing cells always sort to the end. A "missing" cell is a
row that lacks the key (AoH/HoH) or is shorter than the index (AoA); it
is treated the same as an explicit undef. Defined values are ordered
first (ascending, or per the comparison type), undef/missing last, and
undef rows keep their original relative order.
my $rows = [
    [ 1, 5 ],
    [ 2 ],           # no column 1
    [ 3, undef ],
    [ 4, 1 ],
];
my $s = csort($rows, 1);       # column-0 order: 4, 1, 2, 3
This holds for every shape, for numeric and string columns, and for both a column/index sort and a comparator sort:
# no need to guard undef yourself -- this does not warn or die,
# even under  use warnings FATAL => 'all'
my $s = csort($df, sub { $a->{'tau p'} <=> $b->{'tau p'} }, 'hoa');
For a comparator, csort can't see which field you key on, so it probes
each row once (comparing the row to itself) to find rows whose comparator
would read an undef; those rows are moved to the end and the rest are
sorted normally, so your comparator never sees an undef. A few
consequences worth knowing:
- If your comparator reads several keys (a tie-break), a row is treated as undef-keyed when any key the comparator actually evaluates for that row is undef. Such rows go to the bottom.
- A comparator that handles undef itself (e.g.
$a->{v} // 0) never trips the probe, so csort leaves its ordering completely alone. - A comparator that dies for a real reason still propagates that error unchanged.
- The probe calls your comparator once per row, so keep comparators free of side effects (they should be anyway).
Choosing the output shape
The optional third argument picks the returned shape, one of 'aoh',
'hoa', or 'aoa' (case-insensitive). It defaults to the input shape
(HoH defaults to AoH). Any shape can be converted to any other:
csort($aoa, 0)            # AoA -> AoA (default)
csort($aoa, 0, 'hoa')     # AoA -> HoA
csort($aoh, 'No.', 'aoa') # AoH -> AoA
When the target is AoH or HoA, an AoA's columns are keyed by their
stringified index ('0', '1', ...). When the target is AoA, the
positional column order is deterministic:
from HoA   sorted column-key name
from AoH   union of the rows' keys, sorted by name
from AoA   integer index 0 .. widest-row-1 (ragged rows pad with undef)
Because Perl randomizes hash iteration order, the sort of key names is what makes keyed-to-AoA conversions reproducible from run to run.
Sorting a HoH
For a HoH, each outer key is the row name. It is folded into a real
column so it survives into the output; the column is named row_name by
default, overridable with a fourth argument:
my $s = csort($hoh, 'score', 'aoh');           # row name in 'row_name'
my $s = csort($hoh, 'score', 'aoh', 'sample'); # ... named 'sample' instead
density
Kernel density estimation — a smooth curve through a sample, the continuous
answer to what hist answers in bars. This is a port of R's density(), down
to the algorithm: the mass of the sample is dispersed over a regular grid of at
least 512 points, that grid is convolved with a discretised kernel using the
fast Fourier transform, and the result is interpolated back onto the points you
asked for. It returns the same grid, the same bandwidth and the same estimate R
would.
my $d = density(\@x);
printf "%g\t%g\n", $d->{x}[$_], $d->{y}[$_] for 0 .. $#{ $d->{x} };
What that computes is one kernel — a little bump of area 1/n — centred on
every observation, added together. On the left below, seven observations and
their seven gaussian kernels; the blue curve through them is what density
returns. On the right, the same thing over R's faithful$eruptions, against
the histogram of the same sample: the two answer the same question, one in
bars and one as a curve.
Arguments may be given positionally (the sample first) or by name. Names use
underscores where R's use a dot (na_rm, old_coords, give_rkern); R's
dotted spellings (na.rm, old.coords, give.Rkern) are refused as unknown
arguments. R's warnWbw is accepted as well as warn_wbw.
my $d = density(x => \@x, bw => 'SJ', kernel => 'epanechnikov', n => 1024);
Arguments
x— the sample, an array reference. Required (except withgive_rkern). A missing value (undeforNaN) is an error unlessna_rmis set; anything else non-numeric is always an error. An infinite observation is treated as a point mass at ±∞, so it is counted innand takes its share of the mass with it, leaving a sub-density on (−∞, ∞).bw— the smoothing bandwidth, which is the standard deviation of the kernel. Either a positive number, or the name of a rule to choose one:'nrd0'(the default),'nrd','ucv','bcv','SJ'/'SJ-ste', or'SJ-dpi'. Rule names are case-insensitive. The five rules are also available on their own asbw_nrd0,bw_nrd,bw_ucv,bw_bcvandbw_sj, described below.adjust— the bandwidth actually used isadjust * bw, soadjust => 0.5asks for half the default smoothing. Defaults to 1.kernel— one of'gaussian'(the default),'epanechnikov','rectangular','triangular','biweight','cosine'or'optcosine'. Any unambiguous abbreviation will do, so a single letter is enough for every one of them, and the match is case-insensitive. All seven are scaled so thatbwis the kernel's standard deviation, which is why changing the kernel barely changes the estimate.window— an alias forkernel, for compatibility with S. An explicitkernelwins.width— also for compatibility with S, where the argument is the length of the kernel's support rather than a multiple of its standard deviation (for the gaussian, four standard deviations). Consulted only whenbwis not given. A string names a rule, exactly asbwdoes.weights— an array reference of non-negative observation weights, one per element ofx— including the missing ones, so it is always the same length asxwas to begin with. The default is1/nxeach. Weights that do not sum to 1 give a sub-density and draw a warning; passsubdensity => 1if that is what you meant. Ifna_rmremoves observations and the original weights summed to one, the survivors are rescaled so they still do. Bandwidth rules ignore the weights, and say so;warn_wbw => 0silences that, and it is silent anyway when the weights do not vary.n— the number of equally spaced points at which to estimate. Defaults to 512. Values above 512 are rounded up to a power of two internally (that is what makes the FFT cheap) and the result is interpolated back to exactly thenyou asked for, so a power of two is the efficient choice.from,to— the ends of the output grid. The defaults arecutbandwidths outside the range of the data.cut— how many bandwidths past the extremes of the data the defaultfromandtoreach, so that the estimate has room to fall to about zero. Defaults to 3.ext— how many further bandwidths the internal FFT grid extends beyondfromandto. Defaults to 4. Do not change it unless you know why you are changing it; it does not move the output grid, only the accuracy of the values on it.na_rm— drop missing values instead of failing on them. Defaults to off, which is R's default too.subdensity— suppress the "weights do not sum to one" warning, because a sub-density is what was wanted.warn_wbw— whether to warn that an automatic bandwidth ignored the weights. Defaults on when the weights vary.old_coords— reproduce the pre-R-4.4.0 grid, whose values are too large by a factor of about1 + 1/(2n-2). For reproducing old results only.give_rkern— return R(K), the kernel's canonical bandwidth, and no density at all. See below.nb— the number of bins the'ucv','bcv'and'SJ'rules use for their pair counts. Defaults to 1000, as in R.
What the arguments do
bw is the whole ballgame. It is the standard deviation of the kernel, so it
sets how wide each bump is, and adjust multiplies it: adjust => 0.5 is half
the default smoothing. Too little and the estimate follows the individual
observations (the ticks along the bottom are the sample); too much and the two
modes of eruptions melt into one. bw is reported back in the return value,
so the number in each label below is $d->{bw}.
kernel chooses the shape of the bump. All seven are scaled so that bw is
the kernel's standard deviation, which is why they are interchangeable in
practice. Each panel below is one kernel on a common scale, drawn by asking for
the density of a single observation at zero — density([0], bw => 1) is the
kernel — and titled with the R(K) that give_rkern returns. The last panel
puts all seven over one sample at one bandwidth, where they are hard to tell
apart.
from, to and cut decide only where the grid stops: cut bandwidths past
the extremes of the data, three by default. Changing it moves the ends of
$d->{x} (marked below) and nothing else — the estimate itself is the same
function. weights, on the other hand, changes the estimate: each observation
takes its own share of the mass rather than 1/n, which is how a sample that
was collected with unequal probabilities gets its population back.
Return value
A hash reference:
-
x— thengrid points at which the density was estimated, an array reference, strictly increasing fromfromtoto. -
y— the estimated density there, an array reference of the same length. Never negative, though it can be zero. -
bw— the bandwidth actually used, i.e.adjusttimes whateverbwresolved to. Worth reading back when a rule chose it. -
n— the sample size after missing values were removed. Infinite observations still count. -
kernel— the kernel that was used, spelled out in full, so an abbreviation comes back resolved. -
old_coords,has_na— echoes of the corresponding R fields;has_nais always 0.my $d = density(@x, bw => 'SJ'); printf "bandwidth %.4f over %d observations\n", $d->{bw}, $d->{n};
With give_rkern => 1 the return is instead a plain number: R(K) = ∫K²(t)dt
for the chosen kernel, the scale-invariant quantity that says how efficient
that kernel is. No data is needed, and any that is given is ignored.
my $rk = density(kernel => 'epanechnikov', give_rkern => 1); # 0.2683283
Bandwidths that are "exactly equivalent" across kernels are then
(R(K_gaussian)/R(K))**0.2 times each other — the adjustment is within about
1% either way, which is why the choice of kernel rarely matters.
The bandwidth rules: bw_nrd0, bw_nrd, bw_ucv, bw_bcv, bw_sj
The five rules density's bw => string can name are also callable in their
own right, and are ports of R's bw.nrd0, bw.nrd, bw.ucv, bw.bcv and
bw.SJ. Each takes the sample the same two ways density does and returns a
plain number.
my $h = bw_nrd0(\@x);
my $h = bw_sj(x => \@x, method => 'dpi');
They disagree, and on a bimodal sample they disagree by a factor of four. Each
panel below is eruptions at the bandwidth that rule chose, over the same
histogram: nrd0 and nrd assume one mode and oversmooth this sample, ucv
goes the other way, and the two SJ variants land in between.
bw_nrd0— Silverman's rule of thumb,0.9 * min(sd, IQR/1.34) * n**-0.2, anddensity's default. It is the default for historical reasons rather than because it is the best choice.bw_nrd— Scott's variation on the same rule, with 1.06 in place of 0.9.bw_ucv,bw_bcv— unbiased (least-squares) and biased cross-validation. Both minimise a criterion over a range of bandwidths and warn, as R does, if the minimum turned up at one end of that range.bw_sj— the Sheather & Jones (1991) selector, usually the one to reach for.method => 'ste'(the default) solves the equation;method => 'dpi'plugs in directly. These are whatbw => 'SJ'andbw => 'SJ-dpi'select.
The three that search also accept nb (the number of bins for the pair
counts, 1000 by default), lower and upper (the range searched) and tol
(where the search stops, 0.1 * lower by default). Unlike density, these
five want a clean numeric sample: a missing or infinite value is an error, not
something to drop.
Validated against R 4.6.1 — its own regression suite, the examples in
?density and ?bw.nrd, and their pinned output — by t/density.R.scipy.t,
which also cross-checks the whole binning/FFT/interpolation pipeline against
SciPy's exact gaussian_kde.
The figures above are drawn by density.plots.pl in the repository, from the
same eruptions and precip samples that test file uses. It is an author-only
script — it is not installed, and it needs Matplotlib::Simple, python3 and
matplotlib — so re-run it only when a figure needs to change.
Distribution functions
pnorm and dnorm have never had company: there was no way to ask for a
quantile, or for any distribution but the normal, so a confidence bound or a
custom test statistic could not be finished outside the module. These eight
close that, with R's names, R's argument order and R's semantics:
| function | R's | what it gives |
| --- | --- | --- |
| qnorm($p, mean => 0, sd => 1) | qnorm | the normal quantile — the inverse of pnorm |
| pt($q, $df) | pt | Student t CDF |
| qt($p, $df) | qt | Student t quantile |
| pchisq($q, $df) | pchisq | chi-square CDF |
| qchisq($p, $df) | qchisq | chi-square quantile |
| pf($q, $df1, $df2) | pf | F CDF |
| qf($p, $df1, $df2) | qf | F quantile |
| pbinom($q, $size, $prob) | pbinom | binomial CDF |
Every one takes its distribution parameters either positionally or by name, because R is called both ways:
pt(2.5, 10);              pt(2.5, df => 10);
pf(3, 2, 10);             pf(3, df2 => 10, df1 => 2);
pbinom(3, 10, 0.25);      pbinom(3, size => 10, prob => 0.25);
and every one takes the same two flags pnorm does, under both
spellings:
| option | meaning |
| --- | --- |
| lower / lower_tail | 1 (default) for the lower tail, 0 for the upper |
| log / log_p | on a p* function, return the log of the probability; on a q* function, the probability argument is a log |
R's dotted lower.tail and log.p are refused as unknown arguments.
The first argument may be a single number or an array reference, and an array
reference comes back the same length and in the same order — again as pnorm
does. An undef element becomes NaN.
my $z  = qnorm(0.975);                 # 1.959963984540054
my $zs = qnorm([0.025, 0.5, 0.975]);   # [-1.9599639845, 0, 1.9599639845]
What each one does, in one picture
The same identity read from two ends: a p* function is given the boundary and
returns the shaded area; the matching q* function is given the area and
returns the boundary. Each figure shades the region it integrates and writes the
integral it evaluates. Regenerate them all with
perl -Iblib/lib -Iblib/arch distribution.plots.pl.
qnorm — given an area under the normal density, return the cut-point:
pt — the area of the t density to the left of a t statistic:
qt — the t that leaves a given area to its left, which is where the 1.96 of
a confidence interval comes from:
pchisq — the chi-square tail beyond an observed statistic, which is what every
chi-square test reports as its p-value:
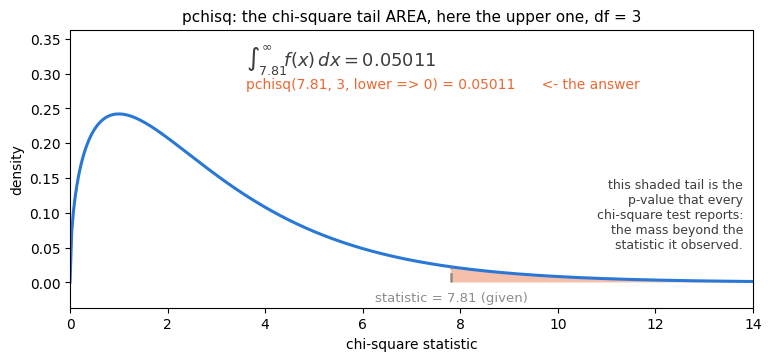
qchisq — the critical value that cuts off a tail of a given size:
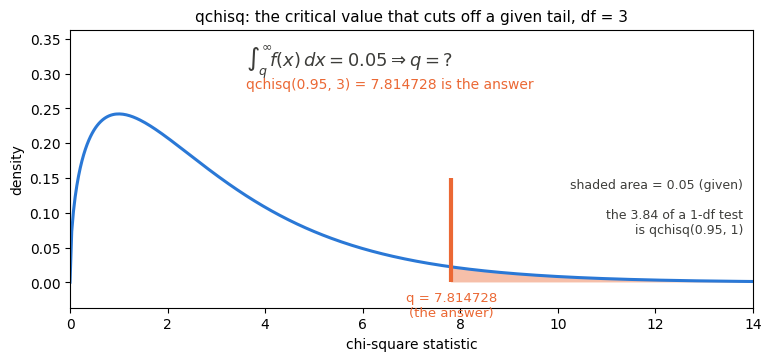
pf — the F tail beyond an observed F, the Pr(>F) column of an ANOVA
table:
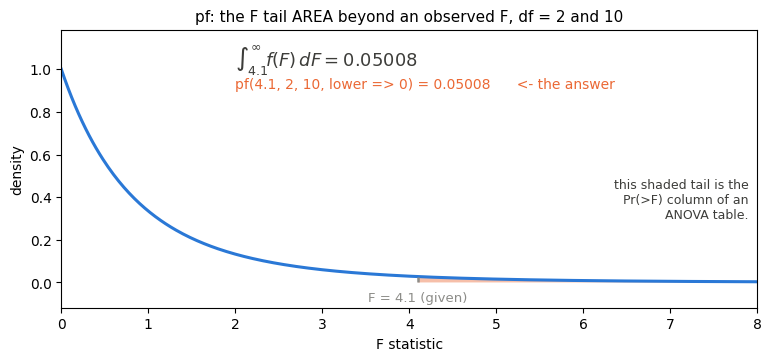
qf — the F that cuts off a given upper tail, the number an F table used to
be printed for:
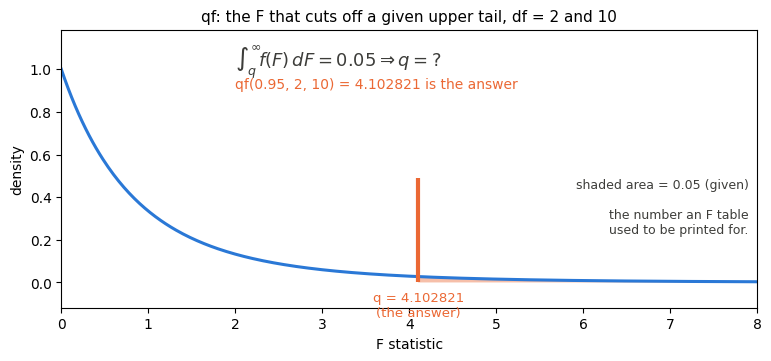
pbinom — the one that is not an integral. A binomial is discrete, so its
lower tail is a finite sum of bar heights, and the figure says so rather than
drawing an integral sign over a histogram:
Why you want them
A Wald interval, or any p-value the module does not already package, becomes a one-liner instead of a table lookup:
my $z  = qnorm(1 - (1 - 0.95) / 2);          # 1.959963984540054
my ($lo, $hi) = ($est - $z * $se, $est + $z * $se);

# a likelihood-ratio test between two nested glm fits
my $lr = $small->{deviance} - $big->{deviance};
my $p  = pchisq($lr, $small->{'df_residual'} - $big->{'df_residual'},
                lower => 0);
The tail you ask for is the tail that gets computed
No tail is ever formed as 1 - the other one. That subtraction costs every
digit below machine epsilon, which is exactly the range a p-value is
interesting in, so each function is routed to the parameterisation that
computes the requested side directly:
pchisq(1e-30, 1);            # 7.978845608028654e-16, not 0
pt(-75, 15);                 # 5.4e-21, from the lower tail itself
qnorm, qchisq and qf reflect a probability above 0.5 onto 1 - p
before inverting, for the same reason in the other direction — that keeps the
root-finder comparing small numbers instead of numbers that agree to fifteen
places. The reflection is free rather than a trade: for p >= 0.5 the two
operands of 1 - p lie within a factor of two of each other, so Sterbenz's
lemma makes that subtraction exact, and nothing is given up in exchange for
what it removes. Measured against mpmath at 60 digits, at the p that
1 - (1 - conf_level) / 2 actually forms:
| conf_level | z, unreflected | z, reflected | |---|---|---| | 0.95 | 0.4 ulp | 0.1 ulp | | 0.99 | 3.0 ulp | 0.1 ulp | | 0.999 | 37 ulp | 0.3 ulp | | 0.9999 | 254 ulp | 0.4 ulp |
The error grows with the confidence level because that is where p and
pnorm(z) agree to the most places, so it is the intervals a cautious caller
asks for that were losing the most digits.
The same critical value every interval in the module is built from
qnorm is not a second opinion about the normal quantile. Since 0.303 it is
the same call — std_qnorm() in LikeR.xs — that glm, cor_test,
prop_test, epi_2x2, cmh_test, roc, survfit, coxph, wilcox_test,
cohen_d and shapiro_test build their own numbers from. So a bound written
by hand lands on the bound the function reports:
my $m  = glm(data => \%d, formula => 'y ~ x', family => 'binomial');
my $se = $m->{summary}{x}{'Std. Error'};
my $z  = qnorm(1 - (1 - 0.95) / 2);
$m->{summary}{x}{'Estimate'} - $z * $se;   # is $m->{'conf_int'}{x}[0]
bit for bit on a double build. On the wider NVs the only thing that can
separate them is the compiler's freedom to contract est - z * se into a
single FMA where perl rounds twice, which is one ulp.
t/qnorm.crit.R.scipy.t asserts that, and goes the other way as well: it
recovers the critical value back out of each function's reported interval —
undoing the exp for coxph and epi_2x2's odds ratio, the tanh for
cor_test — and requires it to be the one qnorm returns, at conf_level 0.8
through 0.9999. cmh_test is the one site not covered, because recovering its
z would mean reimplementing the Robins-Breslow-Greenland variance it does not
report, which would test the reimplementation.
Against mpmath at mp.dps = 60, bisecting the defining equation
erfc(-z/sqrt(2)) / 2 = p rather than calling a library inverse, worst relative
error over those six confidence levels:
| | worst relative error | |
|---|---|---|
| R 4.6.1 qnorm (Wichura's AS 241) | 4.8e-16 | 2.1 ulp |
| SciPy 1.18.0 norm.ppf (Cephes ndtri) | 1.5e-16 | 0.7 ulp |
| this module | 8.2e-17 | 0.4 ulp |
t/std_qnorm.mpmath.py is the arbiter and prints that table, along with the
frozen rows of the test it generates. Like the other generators it is committed
next to its test and nothing in the suite calls it.
Accuracy, and the one place log is not R's
These are glue over routines the module already had — normal_quantile_hp,
pt_upper/qt_tail, the incomplete gamma and beta — whose series and
continued fractions stop at a relative 1e-15 on every build. So they are
double-accurate on a long-double or __float128 perl too, rather than more
accurate there, and they agree with R to about 1e-14 relative.
Two things are deliberately not R:
log => 1on ap*function returnslog()of the probability already computed, not a log carried through the series. A tail that underflowed to0therefore logs to-Inf, and a tail that rounded to1logs to0rather than to the tiny negative number R reports. R'spt/pchisq/pfcarrylog_pthrough and can do better;pnormhere does too, because R's Cody algorithm was ported whole. Theq*functions takelog_pproperly: the argument is exponentiated, which is exact, and lets you name quantiles the linear scale cannot —qnorm(-800, log_p => 1)is reachable whereexp(-800)is just0.qfdisagrees with R in the far tail of F, and is right. Atqf(2^-20, 1, 10)R is 9.9e-4 away from the 60-digit value and this module is 1.0e-15 away; R's ownpfconfirms it, inverting this module's answer to 1.6e-15 and its own to 4.9e-4. Thirteen such rows are pinned int/distributions.R.scipy.tagainst mpmath atmp.dps = 60, each asserted both to be right and to still disagree with R, so the divergence cannot quietly change.
Non-centrality (ncp) is not implemented; nor is qbinom. Everything is
cross-validated in t/distributions.R.scipy.t (2041 tests) against a frozen
table of R 4.6.1 values, SciPy 1.18.0's own mpmath reference cases, and R's own
round-trip identities from tests/d-p-q-r-tests.R.
dnorm
gives the density of the normal distribution, with the specified mean and standard deviation.
In other words, the predicted height of the value x, given a mean, standard deviation, and whether or not to use a log value.
returns a single scalar/number if a single value is given, otherwise returns an array reference.
Usage:
dnorm(4) # assumes a mean of 0 and standard deviation of 1
but default mean, standard deviation, and log can be passed as parameters:
$x = dnorm(0, mean => 0, sd => 2, 'log' => 0);
drop_cols
Return a new data frame with the named columns removed and the rest kept —
df.drop(columns=[...]). Same identifiers and argument forms as
select_cols.
my $hoa = { a => [1,4], b => [2,5], c => [3,6] };
$aoa = drop_cols($hoa, 'b');
# { a => [1,4], c => [3,6] }

my $aoa = [ [1,2,3], [4,5,6] ];
$aoa = drop_cols($aoa, 1); # result is re-indexed 0,1
# [ [1,3], [4,6] ]
Unlike select_cols, drop_cols touches only the keys a row actually has,
so a ragged frame stays ragged:
drop_cols([ {a=>1,b=>2}, {a=>3,c=>9} ], 'a');
# [ { b => 2 }, { c => 9 } ]
drop_duplicates
Remove duplicate rows, loosely modeled on pandas' DataFrame.drop_duplicates.
Works on the three positional/columnar shapes — AoA [ [..], .. ], AoH
[ {A=>..}, .. ], and HoA { A=>[..], .. } — but not HoH: its rows are
labeled, so row-level de-duplication has no natural meaning (convert with
hoh2aoh/hoh2hoa first).
Usage
drop_duplicates($df);                          # dedupe on every column
drop_duplicates($df, subset => 'id');          # only look at column 'id'
drop_duplicates($df, subset => ['a', 'b']);    # a composite key
drop_duplicates($df, keep => 'last');          # keep the last occurrence
drop_duplicates($df, keep => 0);               # drop EVERY duplicated row
Two rows are duplicates when their cells are equal in every subset column.
Comparison is by stringified value with a distinct undef (NA) — the same
key semantics merge uses — so 1 and "1.0" are not equal, while two
undef cells are equal to each other.
subset — which columns define a row's identity
Defaults to every column. Column identifiers are 0-based integer positions for AoA and names for AoH/HoA. Pass a single column as a scalar or several as an arrayref. The default column set is the widest row's positions for AoA, the sorted union of row keys for AoH, and the sorted keys for HoA.
my $aoh = [ { id => 1, v => 'a' }, { id => 1, v => 'b' }, { id => 2, v => 'c' } ];
drop_duplicates($aoh, subset => 'id');
# [ { id => 1, v => 'a' }, { id => 2, v => 'c' } ]
Columns outside subset are not compared, but they stay aligned — a surviving
row keeps all of its columns.
keep — which occurrence survives
-
'first'(default) — keep the earliest occurrence of each row. -
'last'— keep the latest occurrence. -
0(or'none') — drop every row that has a duplicate, keeping only rows that were unique.my $df = { id => [1, 1, 2], v => [10, 20, 30] }; drop_duplicates($df, subset => 'id'); # { id => [1, 2], v => [10, 30] } drop_duplicates($df, subset => 'id', keep => 'last'); # { id => [1, 2], v => [20, 30] }
Row order is preserved: the survivors come out in their original first-seen positions.
Good to know
- Returns a new data frame; the original is never modified. What survives
is shared, not deep-copied: for AoA and AoH the surviving row references are
reused, and for HoA the column arrays are new but hold the same cell SVs. So
the frame, and an HoA's column arrays, can be reshaped without touching the
input — but assigning through a survivor (
$out->{col}[0] = ..., or$out->[0]{col} = ...for AoA/AoH) writes to the input's cell as well. Clone the result if you need full independence. - A tied HoA column is the one exception: its cells have no independent existence to share — the tie hands them out one temporary at a time — so they are copied, and the result is independent of the input for that column. A tied AoA/AoH row is still shared, because the row itself is a real reference whatever the array holding it does.
- It dies on: undefined or non-ref data; an HoH frame; an unknown argument;
an empty or duplicated
subset; an invalidkeep; an AoA position that is not a non-negative integer or is out of range; or asubsetname absent from an AoH or HoA. - An empty frame returns empty rather than erroring.
dropna
Drop missing data from a data frame, loosely modeled on pandas' dropna. Works
on all three shapes: AoH [ {A=>..}, .. ], HoA { A=>[..], .. }, and
HoH { r1=>{A=>..}, .. }.
Usage
# NA mode: drop rows that are undef in the named columns
dropna($df, cols => ['A', 'B']);
dropna($df, cols => ['A', 'B'], how => 'all');
# deletion mode: remove specific rows outright
dropna($df, rows => [2, 5]);          # indices for AoH/HoA, keys for HoH
You pass exactly one of cols or rows.
cols — drop rows with missing values
Inspect only the named columns and drop the rows where they're undef. Columns you don't name are never inspected, but they stay aligned (their cell at a dropped row goes too). A missing key counts as undef.
how controls the threshold:
-
'any'(default) — drop a row if any named column is undef there. -
'all'— drop a row only if every named column is undef there.my $df = { A => [1, 2, undef], B => [1, 2, 3], C => [undef, 2, 4] }; dropna($df, cols => ['A', 'B']);
{ A => [1, 2], B => [1, 2], C => [undef, 2] }
{ A => [1, 2], B => [1, 2], C => [undef, 2] }
Index 2 is dropped because A is undef there. C is not consulted, so its own
undef at index 0 doesn't trigger a drop — but index 2 is still removed from C
so every column stays the same length.
rows — delete specific rows
Remove exactly the rows you list — no missing-value logic. Rows are 0-based indices for AoH and HoA, or the outer keys for HoH. Anything not present is ignored.
dropna({ A => [10, 20, 30] }, rows => [1]); # { A => [10, 30] }
Good to know
- Returns a new data frame; the original is never modified. For HoA the column arrays are rebuilt (cell values copied); for AoH and HoH the surviving row references are reused, not deep-copied (dropna never mutates a row). Clone the result if you need full independence.
- It dies on: a non-ref data frame; passing both or neither of
cols/rows; a non-arrayref selector; acolsname absent from a non-empty HoA or AoH; an invalidhow; an unknown argument; or a hashref that mixes array and hash values (ambiguous HoA vs HoH). - An empty AoH or HoA returns empty rather than erroring.
- HoH results come back in hash order, since HoH rows are unordered.
dunn_test
Dunn's (1964) post-hoc test, the standard follow-up to a significant
kruskal_test (Kruskal-Wallis). It performs all pairwise
comparisons of group rank-means using the shared ranking and tie correction
from the omnibus test, then adjusts the p-values for multiple comparisons.
Two-sided p-values are reported (the FSA::dunnTest convention). Validated
numerically against the canonical formula computed in base R.
my @values = (2.1,3.4,1.9,5.6,4.2, 6.1,7.3,5.9,8.2,6.6, 3.3,4.4,2.2,3.3,5.5);
my @group  = ((('A') x 5), (('B') x 5), (('C') x 5));

my $res = dunn_test(\@values, \@group, method => 'bh');
for my $c (@$res) {
    printf "%-9s  Z=%+.3f  p=%.4f  (adj %.4f)\n",
        $c->{comparison}, $c->{Z}, $c->{'p_value'}, $c->{'p_adjust'};
}
Values and groups are given as two parallel arrays; observations with a missing value or group are dropped.
Input Parameters
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| values | ArrayRef | None (Required) | Numeric observations. | \@values |
| groups | ArrayRef | None (Required) | Group label for each observation (same length as values). | \@group |
| method | String | 'holm' | Multiple-comparison adjustment: none, bonferroni, sidak, holm, hs (Holm-Sidak), bh (Benjamini-Hochberg / FDR), or by (Benjamini-Yekutieli). | 'bh' |
Output
Returns an array reference with one hash per pairwise comparison (in sorted group order), each containing:
| Key | Type | Description | Example |
| --- | --- | --- | --- |
| comparison | String | "group1 - group2". | "A - B" |
| group1, group2 | String | The two groups being compared. | "A", "B" |
| Z | Double | Dunn's z statistic for the rank-mean difference. | -2.7602 |
| p_value | Double | Unadjusted two-sided p-value. | 0.005777 |
| p_adjust | Double | p-value after the chosen adjustment. | 0.017331 |
epi_2x2
The standard 2×2 effect measures — odds ratio, risk ratio, and risk difference, each with a confidence interval, plus number needed to treat — for one exposure×outcome table. Rows are exposure, columns are outcome:
           outcome+   outcome-
    exp+       a          b
    exp-       c          d
Pass the four counts (or a [a,b,c,d] / [[a,b],[c,d]] array ref):
use Stats::LikeR 'epi_2x2';

my $r = epi_2x2(30, 70, 20, 80);
print $r->{'odds_ratio'};           # 1.714
print "@{ $r->{'odds_ratio_ci'} }"; # 0.895 3.285
Options: conf_level (default 0.95) and correct (add 0.5 to every cell,
done automatically when a cell is 0). Result keys: odds_ratio, risk_ratio,
risk_diff (each with a matching *_ci), risk_exposed, risk_unexposed, and
nnt. For a significance test use fisher_test or
chisq_test; to adjust across strata use cmh_test.
eta_squared
Eta-squared (η²) and related effect sizes for a one-way ANOVA, computed from the
sums of squares. Returns η², partial η² (equal to η² for a one-way design), and
ω² (omega-squared, a less biased estimator). Accepts either raw values and group
labels or an existing aov result. Validated numerically against R.
my $e = eta_squared(\@values, \@group);            # or eta_squared($aov_result)
printf "eta^2 = %.3f, omega^2 = %.3f\n", $e->{eta_sq}, $e->{omega_sq};
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| eta_sq | Double | η² = SS_effect / SS_total. | 0.8457 |
| partial_eta_sq | Double | Partial η² = SS_effect / (SS_effect + SS_resid). | 0.8457 |
| omega_sq | Double | ω², adjusted for bias. | 0.7743 |
| term | String | Name of the effect term used. | "grp" |
ffill
Forward-fill NA (undef) cells with the last valid value seen above them along
the row axis, like pandas.DataFrame.ffill. See bfill for the backward
direction and fillna for constant fills.
ffill($df,
    cols  => [ 'v' ],   # restrict to these columns (default: every column)
    limit => 2,         # max consecutive fills per gap (default: unlimited)
);
Column identifiers are names for AoH/HoA/HoH and 0-based positions for AoA. The row axis is positional for AoA/AoH/HoA and string-sorted key order for HoH (the only deterministic order a HoH has). Filling stays within each column's existing length: ragged HoA columns are not extended, and AoA rows are not extended past their own length.
limit caps the number of consecutive NA cells filled in a single gap; the
remaining cells in an over-long gap stay NA, and the count resets after the
next real value. A leading run of NA (with nothing above it) is left as NA.
Returns a NEW frame; the input is never modified.
Example
ffill([ { v => 1 }, { v => undef }, { v => undef }, { v => 4 }, { v => undef } ],
    cols => [ 'v' ]);
# [ { v => 1 }, { v => 1 }, { v => 1 }, { v => 4 }, { v => 4 } ]

ffill([ { v => 1 }, { v => undef }, { v => undef }, { v => 4 } ],
    cols => [ 'v' ], limit => 1);
# [ { v => 1 }, { v => 1 }, { v => undef }, { v => 4 } ]
Errors
Dies on: undefined data; an odd trailing argument list; an unknown argument; a
cols column that does not exist; or a limit that is not a positive integer.
fillna
Replace NA (undef) cells with a constant, like pandas.DataFrame.fillna with
a scalar or a dict. For propagation from neighbouring rows instead of a
constant, use ffill/bfill.
fillna($df,
    value => 0,                    # scalar: fill every NA (or only within `cols`)
    value => { a => 9, b => -1 },  # dict: fill only these columns
    cols  => [ 'a', 'b' ],         # restrict a scalar fill (forbidden with a dict)
);
value is required. Column identifiers are names for AoH/HoA/HoH and 0-based
positions for AoA. A missing hash key counts as NA and is materialised when
filled (as in dropna's NA view). AoA rows are never extended past their own
length. Ragged HoA columns are extended to the longest column's length before
filling.
A scalar value fills every NA in the frame, or — with cols — only NA
cells in the named columns. A hashref value fills only the columns it
names; a dict key that matches no existing column is ignored (matching
pandas), and cols may not be combined with a dict.
Returns a NEW frame; the input is never modified.
Example
fillna([ { a => 1, b => undef }, { a => undef, b => 4 } ], value => 0);
# [ { a => 1, b => 0 }, { a => 0, b => 4 } ]

fillna([ { a => undef, b => undef } ], value => { a => 9, Z => 1 });
# [ { a => 9, b => undef } ]   # Z ignored, b left NA

fillna([ { a => undef, b => undef } ], value => 7, cols => [ 'b' ]);
# [ { a => undef, b => 7 } ]
Errors
Dies on: undefined data; an odd trailing argument list; an unknown argument; a
missing value; combining cols with a dict value; or a scalar-fill cols
naming a column that does not exist.
filter
Return a new data frame containing only the rows of $df that match a predicate. The original $df is never modified.
my $adults = filter($df, col('age') >= 18);
filter accepts a predicate in one of two forms:
- a
col()expression — a small, composable comparison built with overloaded operators, and - a code reference — for anything the operators can't express (multiple columns, regexes, matching on the row name, arbitrary logic), in the same spirit as the
filteroption ofread_table.
Both filter and col are exported by default.
Arguments
| Position | Name | Description |
| --- | --- | --- |
| 1 | $df | The data frame: an array of hashes (AoH, the default read_table output), a hash of arrays (HoA), or a hash of hashes (HoH, e.g. read_table with 'output_type' => 'hoh'). |
| 2 | predicate | A col() comparison object or a CODE reference. A coderef receives the row as $_ / $_[0] and the row identifier as $_[1] (see below). |
| 3 + | 'output_type' => 'aoh'\|'hoa' | Optional. The shape of the returned frame. Omit it to keep the input's own shape. 'out' is an accepted alias (the dotted 'output.type' is refused as an unknown argument), and a bare filter($df, $pred, 'aoh') also works. |
The col() form
col('name') is a deferred reference to a column. It carries no data — only the column name — so it can be compared with a literal to build a predicate that filter evaluates once per row.
filter($df, col('age') >= 18);  # keep rows where age >= 18
filter($df, col('sex') eq 'f'); # keep rows where sex is 'f'
filter($df, 18 <= col('age'));  # operands may be in either order
| Kind | Operators | Comparison |
| --- | --- | --- |
| Numeric | > < >= <= == != | numeric (cell and value compared as numbers) |
| String | gt lt ge le eq ne | string (cell and value compared as strings) |
Predicates compose with bitwise & (and), | (or), and ! (not):
filter($df, (col('age') > 18) & (col('sex') eq 'f'));   # and
filter($df, (col('grp') eq 'a') | (col('grp') eq 'c')); # or
filter($df, !(col('x') > 100));                         # not
Comparison operators bind more tightly than & and |, so (col('a') > 4) & (col('b') < 2) is parsed correctly, but the parentheses are recommended for readability.
A col() expression is also the quick way to say it: filter compiles the whole expression once and tests every row in C, without building a row hash or calling into Perl at all, which on a large frame is several times faster than the equivalent sub. What col() cannot express — a ->match regex, an operand that is an object — is evaluated the same way a sub is, one call per row.
Note: col('age') > 32 works because col('age') is an object whose > is overloaded. A bare string cannot do this — 'age' > 32 is computed by Perl to a plain boolean (the string numifies to 0) before filter is ever called, so the column name is lost. Always wrap the column in col(...).
col() addresses columns only — it has no handle on a HoH's row name (the outer key). It also cannot express a regex match: there is no =~ operator to overload, so col('name') =~ /re/ runs the match immediately on the stringified object and never reaches filter. For either case, use the code-reference form below.
The code-reference form
For logic the operators can't express, pass a sub. It is called once per row and is given:
- the row as a hash reference, available both as
$_and as the first argument$_[0], and - the row identifier as the second argument,
$_[1]— the outer key (the row name) for a HoH, or the 0-based row index for an AoH or HoA.
Return a true value to keep the row.
filter($df, sub { $_->{x} > 4 && $_->{grp} eq 'a' });
filter($df, sub { $_->{name} =~ /^A/ });
filter($df, sub { $_->{age} % 2 == 0 });            # things col() has no operator for
filter($df, sub { $_[0]{score} > $_[0]{threshold} });
For a HoA there are no row hashes to hand over, so the sub is given a { column => value, ... } hash built for it, and the same $_->{column} syntax works regardless of the input shape. That hash is reused from row to row for as long as the sub only reads it; keeping the row (or a reference to one of its cells), or adding a key to it, makes filter start a fresh one, so a row you hold on to is always yours alone. A col() predicate needs no row hash at all.
Filtering on the row name ($_[1])
In a HoH the row name is the outer key, not a field inside each row hash — so $_->{row_name} is undef. Match on $_[1] instead:
# HoH keyed by structure id; keep the rows named in @ids
my $grps = join '|', @ids;
my $keep = filter($score, sub { $_[1] =~ m/^(?:$grps)$/ });

# combine the row name with an ordinary column test
filter($score, sub { $_[1] =~ /^1/ && $_->{anomaly_rank} < 100 });
For an AoH or HoA, $_[1] is the 0-based row index:
filter($aoh, sub { $_[1] % 2 == 0 });   # keep even-indexed rows
filter($hoa, sub { $_[1] < 10 });        # keep the first ten rows
Choosing the output shape
By default filter returns a frame of the same shape as the input (AoH → AoH, HoA → HoA, HoH → HoH). Pass output_type to convert while filtering:
my $aoh = read_table('patients.csv');                          # array of hashes
my $hoa = filter($aoh, col('Age') >= 18, 'output_type' => 'hoa');
# $hoa->{Age}, $hoa->{Sex}, ... are all the same length and row-aligned
The two selectable output types are 'aoh' and 'hoa'. 'hoh' is not selectable, because producing a hash of hashes would require choosing which column becomes the row key; an HoH input keeps its keys only when the output shape is left at the default (HoH → HoH).
Examples
use Stats::LikeR;
my $df = read_table('patients.csv');                 # array of hashes

my $adults = filter($df, col('Age') >= 18);          # numeric threshold
my $target = filter($df, (col('Age') >= 18) & (col('Sex') eq 'f'));   # combine
my $flagged = filter($df, sub { $_->{ALT} > 40 || $_->{AST} > 40 });  # coderef

# hash of arrays in -> hash of arrays out (columns filtered in parallel)
my $hoa = read_table('patients.csv', 'output_type' => 'hoa');
my $sub = filter($hoa, col('Age') > 32);

# hash of hashes in -> the same row keys, fewer of them
my $hoh = read_table('patients.csv', 'output_type' => 'hoh');
my $keep = filter($hoh, col('Age') > 32);

# hash of hashes: filter on the row name (the outer key) via $_[1]
my $grps    = join '|', qw(1cka 1d4t);
my $by_name = filter($hoh, sub { $_[1] =~ m/^(?:$grps)$/ });

# convert shape while filtering
my $as_hoa = filter($df, col('Age') > 32, 'output_type' => 'hoa');
Behavior and notes
- The input is never modified.
filterbuilds and returns a new frame;$dfis left untouched. - The predicate receives the row identifier as
$_[1]. For a HoH it is the outer key (the row name); for an AoH or HoA it is the 0-based row index. In a HoH the row name lives in the key, not inside each row hash, so$_->{row_name}isundef— filter on$_[1]instead.col()expressions see only columns, never the row key. - A missing or
undefcell never matches acol()comparison.col('x') > 0silently drops any row whosexis absent orundef; for numeric operators a non-numeric cell is likewise dropped. With a coderef,undefis whatever your sub makes of it. - Rows are shared, not deep-copied, wherever possible. When an AoH or HoH row is kept (output left as AoH/HoH, or converted to
aoh), the returned frame references the same inner row hashes as the input. Mutating such a row in the result would also change it in the original. HoA inputs and anyhoaoutput build fresh arrays and fresh cell values. - Keep-all / keep-none are well defined. A predicate true for every row returns the whole frame in the chosen shape; true for none returns an empty frame:
[]foraoh, a hash of empty (but present) columns forhoa, and{}forhoh. - Supported shapes are AoH, HoA, and HoH. A non-reference, an AoH element that is not a hash reference, a HoA column that is not an array reference, or a HoH row that is not a hash reference all raise a descriptive error; a bare
col('x')with no comparison is also an error. An empty hash{}is treated as an empty frame. - Perl 5.10 compatible. The
col()/operator layer is pure Perl (operator overloading building a per-row closure); filtering and any reshaping run in XS.
See also
read_table (whose filter option applies the same coderef convention while reading a file), col2col.
fisher_test
array reference entry
my $array_data = [
	[10, 2],
	[3, 15]
];
my $res1 = fisher_test($array_data);
which returns a hash reference:
{
alternative   "two.sided",
conf_int      [
    [0] 2.75343836564204,
    [1] 300.682787419401
],
conf_level    0.95,
estimate      {
    "odds ratio"   21.3053312750168
},
method        "Fisher's Exact Test for Count Data",
p_value       0.000536724119143435
}
hash reference entry
$ft = fisher_test( {
    Guess => {
        Milk => 3, Tea => 1
    },
    Truth => {
        Milk => 1, Tea => 3
    }
});
larger (R x C) tables
Any table of at least 2x2 counts is accepted, as either a 2D array reference or a 2D hash reference:
my $res = fisher_test([
    [5, 3, 2],
    [1, 4, 6],
    [7, 2, 1],
]);
For tables larger than 2x2 the p-value is computed by exact enumeration of
every contingency table sharing the observed row and column margins (the
multivariate hypergeometric distribution), and matches R's fisher.test to
full precision. Only the two-sided test is defined in this case, so
alternative is ignored and the returned hash reference omits conf_int and
estimate (the conditional-MLE odds ratio and its confidence interval are
reported for 2x2 tables only):
{
alternative   "two.sided",
conf_level    0.95,
method        "Fisher's Exact Test for Count Data",
p_value       0.0540892411303451
}
As with the 2x2 case, a hash-of-hashes input orders rows by their sorted keys and columns by the sorted keys of the first row, so the result is deterministic; every row must expose the same set of column keys, and every row of an array input must have the same number of columns.
Enumeration is exact but finite: a table whose margins put more completions in the way than can be walked is refused outright,
fisher_test: 5x7 table is too large for exact enumeration
rather than answered with an approximation. Subtrees that lie wholly inside or
wholly outside the tail are summed in closed form or dropped without being
walked, which puts most tables of practical size well inside the limit --
fisher_test computes the 6x6 table of R's PR#18336, which R's own fisher.test
declines with hash key 5e+09 > INT_MAX -- but R's network algorithm (FEXACT)
still reaches tables this one cannot, such as the 5x7 6th example of Mehta &
Patel. For those, use chisq_test, or R.
friedman_test
The Friedman rank-sum test, the non-parametric analog of a repeated-measures
ANOVA for an unreplicated complete block design (e.g. the same subjects measured
under several conditions, or several raters scoring the same items). It is a
faithful port of R's stats::friedman.test, including the tie correction, and
was validated numerically against R.
Input is a matrix (array of array refs) with one block/subject per row and
one treatment/condition per column. Blocks (rows) containing any missing or
non-numeric value are dropped, mirroring R's complete.cases.
#             cond1 cond2 cond3
my $r = friedman_test([
    [7,  9,  8],   # subject 1
    [6,  6,  7],   # subject 2
    [9, 10,  9],   # subject 3
    [8,  8,  6],   # subject 4
]);
printf "chi2=%.3f  df=%d  p=%.4g\n", $r->{statistic}, $r->{parameter}, $r->{'p_value'};
A significant result says the conditions differ overall; follow up with pairwise comparisons (for example dunn_test on the paired differences, or Wilcoxon signed-rank tests with a multiple-comparison adjustment).
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| statistic | Double | Friedman chi-squared statistic (tie-corrected). | 4.0952 |
| parameter | Integer | Degrees of freedom, k - 1 (number of treatments minus one). | 2 |
| p_value | Double | The p-value from the chi-squared approximation. | 0.129 |
| n | Integer | Number of complete blocks actually used. | 7 |
| method | String | "Friedman rank sum test". | |
get_union
my @all   = get_union(\@a, \@b, \@c); # every distinct value, any list
my $count = get_union(\@a, \@b, \@c); # how many distinct values
Takes one or more array references and returns every value that appears in at
least one of them. Duplicates collapse and the result keeps first-appearance
order. In scalar context it returns the count. Values are compared by their
string form (like Perl hash keys), so 1, "1" and 1.0 are one element,
while a UTF-8 flagged string stays distinct from the same bytes without the
flag. A non-array-ref argument or an undef element is fatal. Mirrors
List::Compare's get_union.
my @a = (1, 2, 3, 3);
my @b = (3, 4);
my @u = get_union(\@a, \@b);            # (1, 2, 3, 4)
glm
takes a hash of an array as input
my %tooth_growth = (
	dose => [qw(0.5 0.5 0.5 0.5 0.5 0.5 0.5 0.5 0.5 0.5 1.0 1.0 1.0 1.0 1.0 1.0 1.0 1.0 1.0
1.0 2.0 2.0 2.0 2.0 2.0 2.0 2.0 2.0 2.0 2.0 0.5 0.5 0.5 0.5 0.5 0.5 0.5 0.5
0.5 0.5 1.0 1.0 1.0 1.0 1.0 1.0 1.0 1.0 1.0 1.0 2.0 2.0 2.0 2.0 2.0 2.0 2.0
2.0 2.0 2.0)],
	len  => [qw(4.2 11.5  7.3  5.8  6.4 10.0 11.2 11.2  5.2  7.0 16.5 16.5 15.2 17.3 22.5
17.3 13.6 14.5 18.8 15.5 23.6 18.5 33.9 25.5 26.4 32.5 26.7 21.5 23.3 29.5
15.2 21.5 17.6  9.7 14.5 10.0  8.2  9.4 16.5  9.7 19.7 23.3 23.6 26.4 20.0
25.2 25.8 21.2 14.5 27.3 25.5 26.4 22.4 24.5 24.8 30.9 26.4 27.3 29.4 23.0)],
	supp => [qw(VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC VC
VC VC VC VC VC OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ
OJ OJ OJ OJ OJ OJ OJ OJ OJ OJ)]
);

my $glm_teeth = glm(
	data    => \%tooth_growth,
	formula => 'len ~ dose + supp',
	family  => 'gaussian'
);
In addition to the gaussian default, it fully supports logistic regression using the binomial family parameter via Iteratively Reweighted Least Squares (IRLS):
my $glm_bin = glm(formula => 'am ~ wt + hp', data => \%mtcars, family => 'binomial');
Count outcomes are handled by the poisson family (log link, for rate ratios) and the negbin (negative-binomial) family, which accommodates over-dispersion. As in R's MASS::glm.nb, the negative-binomial dispersion theta is estimated by maximum likelihood, alternating with the IRLS fit, unless you supply a fixed value:
my $pois = glm(formula => 'cases ~ age + sex', data => \%d, family => 'poisson');
my $nb   = glm(formula => 'cases ~ age + sex', data => \%d, family => 'negbin');
my $nb2  = glm(formula => 'cases ~ age + sex', data => \%d, family => 'negbin', theta => 1.7);
For every non-gaussian family, glm also returns the exponentiated coefficients with their Wald confidence intervals (confint.default): odds ratios for binomial, and rate / incidence-rate ratios for poisson and negbin. The interval width is set by the conf_level argument (default 0.95). Validated numerically against R's glm, MASS::glm.nb, and confint.default.
my $nb = glm(formula => 'cases ~ age + sex', data => \%d, family => 'negbin');
printf "IRR(age) = %.2f (%.2f–%.2f)\n",
    $nb->{exp}{age}{estimate}, $nb->{exp}{age}{'conf_low'}, $nb->{exp}{age}{'conf_high'};
For the families that report a Wald z (everything but gaussian),
Pr(>|z|) is computed as 2 * pnorm(-|z|) rather than
2 * (1 - pnorm(|z|)), so a strong effect reports its actual p-value instead
of a flat 0; see F and z tail p-values. The
gaussian family reports Pr(>|t|) from a direct two-tail probability and was
never affected. Note that the z itself comes from this module's IRLS fit and
can differ from R's in the 6th to 8th significant digit, which a p-value far
out in the tail amplifies — at |z| = 37 a 1.5e-5 difference in z moves the
p-value by about 2%.
Offsets, prior weights, robust covariance and absorbed factors
An offset is a term whose coefficient is fixed at 1 rather than estimated,
which is how a count model is put on a per-person-time scale. Write it into the
formula, as R does, or pass it as offset (a column name, an expression over
columns, or an array ref with one value per row); the two forms add together.
The negative-binomial theta search sees the offset too, as MASS::glm.nb's
does, and the null deviance is that of an intercept-plus-offset fit:
my $rate = glm(formula => 'admits ~ hours + age + offset(log(persontime))',
               data => \%d, family => 'poisson');
my $same = glm(formula => 'admits ~ hours + age', offset => 'log(persontime)',
               data => \%d, family => 'poisson');
Prior weights (weights, a column name or an array ref) are R's
glm(weights = ). A binomial fit whose weights make a non-integer number of
successes warns non-integer #successes in a binomial glm!, as R does. A row
with weight 0 is kept out of the fit and out of nobs.
vcov => 'HC0' (through 'HC3') replaces the model-based covariance by a
heteroskedasticity-consistent sandwich, sandwich::vcovHC(), and cluster
by a cluster-robust one, sandwich::vcovCL(). Naming a cluster alone implies
HC0, which is vcovCL()'s own default for a glm; HC1 adds the
(n - 1)/(n - k) factor. cluster => 'firm + year' clusters two ways (up to
four) by inclusion-exclusion, as vcovCL(cluster = ~ firm + year) does. The
summary standard errors, z, p-values and both kinds of confidence interval
are then all computed from the robust covariance, as lmtest::coeftest()
would. A poisson fit on a 0/1 outcome with vcov => 'HC0' is the
"modified Poisson" risk-ratio regression (Zou 2004, Am J Epidemiol 159:702):
my $rr = glm(formula => 'readmit ~ hours + age', data => \%d,
             family => 'poisson', vcov => 'HC0', cluster => 'child_id');
printf "RR = %.3f (%.3f-%.3f)\n", @{ $rr->{exp}{hours} }{qw(estimate conf_low conf_high)};
A factor with thousands of levels (a within-subject comparison) can be
absorbed instead of expanded into dummy columns: put it after a | in the
formula, as fixest does, or name it in absorb. The fit then demeans within
groups (weighted, by alternating projections for more than one factor) and
reports only the remaining coefficients, which equal those of the
full-dummy fit. As fixest::feglm() does, a group whose outcome is constant at
a boundary (all zeros for poisson/negbin, all 0 or all 1 for binomial)
carries no information and is dropped; fe_removed counts the rows that goes
with. HC2/HC3 are not available with absorbed factors.
my $fe = glm(formula => 'visits ~ hours | child_id + year', data => \%d,
             family => 'poisson', cluster => 'child_id');
maxit (default 25) and epsilon (default 1e-8) are glm.control()'s.
A control-function IV estimate for a count outcome is two calls: fit the
first stage with lm, add its residuals to the data, and include them
as a regressor in the poisson/negbin glm. The coefficient of the
residual is a test of exogeneity, but the second-stage standard errors do not
account for the first stage having been estimated; bootstrap the pair of fits
for those. For a continuous outcome use ivreg, whose standard
errors are right as they stand.
Input Parameters
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| formula | String | None (Required) | A symbolic description of the model to be fitted. Parsed by the same code as lm's, so it takes the same operators: +, :, *, ^, . for every remaining column, and -1 / +0 to remove the intercept. It may also hold offset() terms, and factors to absorb after a \|. | 'am ~ wt + hp', 'y ~ x - 1', 'y ~ .' |
| data | HashRef or ArrayRef | None (Required) | The dataset containing the variables used in the formula. Accepts a Hash of Arrays (HoA), a Hash of Hashes (HoH) or an Array of Hashes (AoH). Rows are named as described under lm. | \%mtcars, [{x => 1, y => 2}, ...] |
| family | String | 'gaussian' | The error distribution / link function: 'gaussian' (identity link), 'binomial' (logit link), 'poisson' (log link) or 'negbin' (negative binomial, log link). | 'poisson' |
| theta | Number | estimated by ML | Negative-binomial dispersion. When omitted (with family => 'negbin') it is estimated by maximum likelihood as in MASS::glm.nb; supply a value to hold it fixed. | 1.7 |
| conf_level | Number | 0.95 | Confidence level for the Wald coefficient / exponentiated-coefficient intervals. | 0.90 |
| offset | String or ArrayRef | none | A column, an expression over columns such as 'log(t)', or one value per row, added to the linear predictor with coefficient 1. Adds to any offset() terms in the formula. | 'log(persontime)' |
| weights | String or ArrayRef | none | Prior weights, R's glm(weights = ): a column name, or one value per row. Must be non-negative. | 'w' |
| vcov | String | 'model' | 'model', or a sandwich: 'HC0', 'HC1', 'HC2' or 'HC3' (sandwich::vcovHC). Also accepted as vcov_type. | 'HC0' |
| cluster | String or ArrayRef | none | Cluster variable(s) for sandwich::vcovCL: a column name, 'a + b' for multiway clustering, or one label per row. Implies vcov => 'HC0' unless 'HC1' is given. | 'child_id' |
| absorb | String or ArrayRef | none | Factor(s) to absorb as fixed effects rather than expand, like the formula's \| f1 + f2 part. | 'child_id' |
| maxit | Integer | 25 | IRLS iteration limit, as glm.control(maxit = ). | 50 |
| epsilon | Number | 1e-8 | IRLS convergence tolerance on the relative deviance change, as glm.control(epsilon = ). | 1e-10 |
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| aic | Double | Akaike's Information Criterion for the fitted model (lower is better). | 123.45 |
| boundary | Integer (Boolean) | 1 if the fitted values computationally reached the 0 or 1 boundary (specific to the binomial family), 0 otherwise. | 0 |
| coefficients | HashRef | A hash mapping the expanded model term names to their estimated coefficient values. | {'Intercept' => 1.5, 'wt' => -0.5} |
| converged | Integer (Boolean) | 1 if the Iteratively Reweighted Least Squares (IRLS) algorithm converged within the maximum iterations, 0 otherwise. | 1 |
| deviance | Double | The residual deviance of the fitted model. | 15.2 |
| deviance_resid | HashRef | A hash mapping data row names to their computed deviance residuals. | {'Mazda RX4' => 0.12} |
| df_null | Integer | The residual degrees of freedom for the null model. | 31 |
| df_residual | Integer | The residual degrees of freedom for the fitted model. | 30 |
| family | String | The statistical family used to fit the model. | "gaussian" |
| fitted_values | HashRef | A hash mapping data row names to the fitted mean values (the model's predictions on the scale of the response). | {'Mazda RX4' => 0.85} |
| iter | Integer | The number of IRLS iterations performed before convergence or hitting the iteration limit. | 4 |
| null_deviance | Double | The deviance for the null model (a baseline model containing only an intercept, or an offset of 0 if the intercept is removed). | 43.5 |
| rank | Integer | The numeric rank of the fitted linear model (the number of estimated, non-aliased parameters). | 2 |
| summary | HashRef | A nested hash mapping each term to its detailed summary statistics, including Estimate, Std. Error, t value / z value, Pr(> t ) / Pr(> z ), and the Wald CI_lower / CI_upper (link scale). Aliased parameters return "NaN". | {'wt' => {'Estimate' => -0.5, 'Std. Error' => 0.1, ...}} |
| terms | ArrayRef | An ordered list of the expanded term names included in the model matrix. | ['Intercept', 'wt', 'hp'] |
| conf_int | HashRef | Wald confidence interval for each coefficient on the link scale, as [lower, upper]. | {'wt' => [-0.9, -0.1]} |
| conf_level | Double | The confidence level used for conf_int and exp. | 0.95 |
| exp | HashRef | Non-gaussian families only: exponentiated coefficient (odds ratio for binomial; rate / incidence-rate ratio for poisson / negbin) with its confidence interval, as {estimate, 'conf_low', 'conf_high'}. | {'wt' => {estimate => 0.6, 'conf_low' => 0.4, 'conf_high' => 0.9}} |
| theta | Double | negbin family only: the negative-binomial dispersion parameter (ML estimate, or the fixed value supplied). | 1.73 |
| loglik | Double | The log-likelihood, as R's logLik(). | -120.3 |
| dispersion | Double | The dispersion the standard errors use: estimated (Pearson) for gaussian, 1 for the other families. | 1 |
| nobs | Integer | Rows in the fit (non-missing, non-zero weight, and not dropped with an absorbed group). | 98 |
| vcov | HashRef | The coefficient covariance, model-based or robust as vcov_type says, as a hash of hashes by term. | {'wt' => {'wt' => 0.01, ...}} |
| vcov_type | String | 'model', 'HC0', 'HC1', 'HC2' or 'HC3'. | 'HC0' |
| n_clusters | Integer or ArrayRef | With cluster: the number of clusters, or one count per variable when clustering several ways. | 120 |
| absorb | HashRef | With absorbed factors: each factor's number of groups in the fit. | {'child_id' => 812} |
| fe_removed | Integer | With absorbed factors: rows dropped because their group's outcome was constant at a boundary. | 14 |
| offset_terms | ArrayRef | With an offset: the expressions it is made of, which predict re-evaluates on new data. | ['log(persontime)'] |
| twologlik | Double | negbin only: twice the log-likelihood, as MASS::glm.nb. | -240.6 |
| SE_theta | Double | negbin with theta estimated: its standard error. | 0.41 |
group_by
group_by($data, $value_column, $group_column, @filters)
Split the values of one column by the levels of another, as R's split(x, f)
does. The column of values comes first and the grouping column second --
the reverse of dplyr's group_by(df, g) or pandas' df.groupby('g'), which
take only the grouping column. group_by($mtcars, 'mpg', 'cyl') is "mpg,
split by cyl", and returns a hash of arrays keyed by the levels of cyl:
{
    4   [ 22.8, 24.4, 22.8, ... ],   # the 11 four-cylinder cars' mpg
    6   [ 21,   21,   21.4, ... ],   # 7
    8   [ 18.7, 14.3, 16.4, ... ]    # 14
}
That is the shape aov stacks when it is given no formula, so aov($gb) runs
a one-way ANOVA of the values across the groups.
The data may be an array of hashes, a hash of hashes, or a hash of arrays:
my $aoh_data = [
    { 'Gender' => 'Male',   'Testosterone, total (nmol/L)' => 20.5 },
    { 'Gender' => 'Female', 'Testosterone, total (nmol/L)' => 1.8 },
    { 'Gender' => 'Male',   'Testosterone, total (nmol/L)' => 18.2 },
    { 'Gender' => 'Female' } # Intentional missing target value
];

my $hoh_data = {
    'Patient_A' => { 'Gender' => 'Male',   'Testosterone, total (nmol/L)' => 20.5 },
    'Patient_B' => { 'Gender' => 'Female', 'Testosterone, total (nmol/L)' => 1.8 },
    'Patient_C' => { 'Gender' => 'Male',   'Testosterone, total (nmol/L)' => 18.2 },
    'Patient_D' => { 'Gender' => 'Female' }, # Intentional missing target value
    'Patient_E' => { 'Gender' => 'Female', 'Testosterone, total (nmol/L)' => undef } # Explicit undef
};

my $hoa_data = {
    'Gender'                       => ['Male', 'Female', 'Male', 'Female'],
    'Testosterone, total (nmol/L)' => [22.1,   2.5,      19.4,   undef   ]
};
Each is called the same way:
group_by($aoh_data, 'Testosterone, total (nmol/L)', 'Gender');
and each returns a hash of arrays. A row whose value is missing or undef is
left out, so the second Female row contributes nothing. $aoh_data gives
{
    Female   [
        [0] 1.8
    ],
    Male     [
        [0] 20.5,
        [1] 18.2
    ]
}
and $hoa_data gives
{
    Female   [
        [0] 2.5
    ],
    Male     [
        [0] 22.1,
        [1] 19.4
    ]
}
The values are not sorted. From an array of hashes or a hash of arrays they
come in row order; from a hash of hashes they come in Perl's hash order, which
differs from run to run, so $hoh_data gives Male as either [20.5, 18.2]
or [18.2, 20.5]. Sort them, or use an array of hashes, if the order matters.
A column that is present in some rows but missing in others is fine (those rows
are simply skipped), but naming a target, group, or filter column that is absent
from the data entirely is fatal: group_by dies with
group_by: "<column>" is not present in the dataset.
Filtering
Data can be further broken down with filter/subs like in read_table:
my $testosterone = group_by($d, # group testosterone by "Gender"
    'Testosterone, total (nmol/L)',
    'Gender',
    { 'Race/Hispanic origin w/ NH Asian' => sub { $_ eq $n } },# filter
    { 'Testosterone, total (nmol/L)' => sub { $_ ne 'NA' } } # filter
);
where each filter filters on the columns, e.g. second hash keys.
h
Print a function's documentation and return. This is the module's ?function:
ask for a name, get the section of the manual that describes it.
h('quantile');    # by name
h(*quantile);     # by name, unquoted
h(\&quantile);    # by reference
h();              # the general help, and every documented function

perl -MStats::LikeR -e 'h(*write_table)'   # straight from the shell
Arguments
| Form | Meaning |
| --- | --- |
| h('name') | A string. A package prefix is ignored, so h('Stats::LikeR::agg') works too. |
| h(*name) | A typeglob. The closest thing to an unquoted name that Perl will allow here. |
| h(\&name) | A code reference to one of this module's functions. Dies if the reference is not one. |
| h() | No argument: prints Getting help and lists every documented function. |
h(bedroc), with no quotes and no sigil, cannot be made to work: every function
here is exported, so Perl parses the bareword as a call to bedroc() before h
is ever reached.
Return value
The name whose documentation was printed, so h is usable in a pipeline:
my @shown = map { h($_) } qw(auc auroc roc);
h does not die, and it is the only route to a function's documentation:
no function reads its own arguments for a help flag, so a column or file really
named 'h' is never mistaken for a question. See
Getting help.
Where the text comes from
h renders the module's own POD at run time. That POD is generated from
README.md, so h and this document can never disagree. A function with no
section of its own — an internal helper, or ptukey / qtukey — prints the
list of functions that do have one.
Output is wrapped to $ENV{COLUMNS} when that is set (clamped to 40-100
columns), and to 80 otherwise. Parameter tables are rendered as aligned plain
text.
h2aoh
Unfold a plain hash into a two-column array-of-hashes, one row per pair.
my $aoh = h2aoh(\%h);
my $aoh = h2aoh(\%h, var_name => 'gene', value_name => 'n');
A flat hash is a two-column table that has been folded shut: every pair is a
row, the key in one cell and the value in the other. h2aoh unfolds it, which
turns a result that no frame function will accept — value_counts hands one
back — into a data frame that all of them will:
my $counts = value_counts($titanic, 'Pclass');   # { 1 => 216, 2 => 184, 3 => 491 }
my $tbl    = h2aoh($counts, var_name => 'Pclass', value_name => 'n',
                   sort => 'value');
view($tbl);
# AoH: 3 rows x 2 cols   (showing 3)
#    Pclass    n
# 0       3  491
# 1       1  216
# 2       2  184
R spells this tibble::enframe(); base R gets close with
stack() or data.frame(name = names(x), value = unname(x)). In pandas it is
pd.Series(d).rename_axis('k').reset_index(name = 'v'), or the shorter
pd.DataFrame(d.items(), columns = ['k', 'v']).
Arguments
$h — a hash ref whose values are plain scalars. Required.
Everything after it is name => value pairs:
| Option | Default | Meaning |
| --- | --- | --- |
| var_name | variable | Name of the column that receives the hash keys. |
| value_name | value | Name of the column that receives the hash values. |
| sort | key | Row order — see below. |
var_name and value_name must differ. They are the same two option names
melt uses, because they name the same two columns.
Row order
Hash iteration order is not reproducible between runs, so the rows are sorted by default rather than left to chance.
| sort | Order |
| --- | --- |
| key | By key. Numerically when every key looks like a number, alphabetically otherwise — the rule agg uses for its group keys. This is the default. |
| value | By value: largest first when every defined value is a number, which is the order value_counts output usually wants; alphabetically ascending when they are not. undef values sort last, and ties break on the key. |
| none | Whatever order the hash iterates in. Cheapest, and the right choice when you are about to sort the result yourself with csort. |
Returns
An array ref of two-key hash refs, one per pair:
h2aoh({ a => 1, b => 2 });
# [ { variable => 'a', value => 1 }, { variable => 'b', value => 2 } ]
An empty hash gives back []. undef values are carried through as undef.
Errors
h2aoh dies when the argument is undefined or not a hash ref, when the options
are not name => value pairs, when an option is unknown, when var_name
equals value_name, or when sort is not one of the three allowed words.
It also dies when any value is a reference, naming the key and pointing at
the converter that was probably meant: a hash of array refs is
hoa2aoh's job, and a hash of hash refs is
hoh2hoa's. Stringifying ARRAY(0x…) into a cell would be the
only other option, and it is never what anyone wanted.
See also
aoh2h is the reverse. melt does the same folding-out for
a frame that already has more than two columns.
hoa2aoh
Turn a hash-of-arrays into an array-of-hashes.
Usage
my $aoh = hoa2aoh($hoa);
-
$hoa— a hashref whose values are arrayrefs, one per column:{ id => [1, 2, 3], name => ['a', 'b', 'c'] }
-
returns — an arrayref of row hashrefs:
[ { id => 1, name => 'a' }, { id => 2, name => 'b' }, { id => 3, name => 'c' } ]
It builds a brand-new structure and copies every cell, so the result is completely independent of the input — changing one never affects the other.
Example
my $hoa = { mpg => [21, 22.8, 18.1], cyl => [6, 4, 6] };
my $aoh = hoa2aoh($hoa);
$aoh->[1]{mpg};        # 22.8
$hoa->{mpg}[1];        # still 22.8 — unaffected by edits to $aoh
Good to know
- Row count is the length of the longest column. If columns have different
lengths, the short ones are padded with
undefin the missing rows. undefcells are kept asundef.- An empty hash, or one whose columns are all empty, gives back
[]. - It dies if the argument isn't a hashref, or if any column value isn't an arrayref (the message names the offending column).
See also
hoa2aoh is the reverse of aoh2hoa
hoa2hoh( %hoa, $key )
Converts a hash-of-arrays (column-major) into a hash-of-hashes keyed by the
$key column, i.e. { $rowname => { col => value, ... } }. Analogous to
hoa2aoh, but rows are indexed by their $key value instead of positionally.
my %hoa = (
    id => [ qw(a b c) ],
    x  => [ 1, 2, 3 ],
    y  => [ 4, 5, 6 ],
);
my $hoh = hoa2hoh( \%hoa, 'id' );
# { a => { id => 'a', x => 1, y => 4 }, b => {...}, c => {...} }
The $key column is retained in each inner row. Columns are copied by value.
Shorter columns are padded with undef, matching hoa2aoh.
Dies if: the first argument is not a hashref of arrayrefs; $key is undef or
names a missing/non-array column; the $key column holds an undefined value
for any row; or two rows share the same $key value.
hoh2hoa
Convert a hash of hashes (row-major: outer key = row, inner key = column) into a hash of arrays (column-major: key = column, value = that column's cells down the rows).
use Stats::LikeR;

my %hoh = (
    'r1' => { 'a' => 1, 'b' => 2 },
    'r2' => { 'a' => 3, 'b' => 4 },
);

my $hoa = hoh2hoa(\%hoh);
which returns
{
  a => [1, 3],
  b => [2, 4],
}
Behavior
- Columns are the union of every inner key, so a key that appears in only some rows still becomes a column.
- Rows are emitted in sorted outer-key (row-name) order, and that one order is used for every column, so the arrays stay aligned and the result is reproducible regardless of hash ordering.
- Gaps — a missing inner key, or a cell whose value is
undef— are filled with the fill value (seeundef_valbelow). Every column therefore has exactly one entry per row. - Values are copied into the result; the original structure is left untouched.
- An empty hash of hashes returns an empty hash of arrays (it is not an error).
Options
Options are passed as trailing name => value pairs.
| Option | Default | Meaning |
| --- | --- | --- |
| undef_val | undef | Value used to fill a missing key or an undef cell. Any defined scalar works, including 0 and ''. Passing undef keeps the default. |
| row_names | (none) | If set to a string, an extra column of that name is added holding the sorted row labels, aligned with the data. Dies if the name collides with an existing column. |
# Ragged input with an explicit fill string:
my %ragged = (
    'r1' => { 'a' => 1, 'b' => 2 },
    'r2' => { 'a' => 3, 'c' => 9 },
);
my $hoa = hoh2hoa(\%ragged, 'undef_val' => 'NA');
# {
#   a => [1,    3   ],
#   b => [2,    'NA'],
#   c => ['NA', 9   ],
# }

# Keep the row labels as a column:
my $with_ids = hoh2hoa(\%ragged, 'row_names' => 'id');
# {
#   id => ['r1', 'r2'],
#   a  => [1,    3   ],
#   b  => [2,    undef],
#   c  => [undef, 9  ],
# }
Errors
hoh2hoa dies (via croak) when:
- the argument is not a hash reference,
- any value in the hash is not itself a hash reference,
- an unknown option is given, or the options are not
name => valuepairs, row_namesis not a plain string, or it names an already-present column.
hist
Computes the histogram of the given data values. It returns the bin counts, computed breaks, midpoints, and density.
my $res = hist([1, 2, 2, 3, 3, 3, 4, 4, 5], breaks => 4);
breaks is a suggested number of intervals, not a count to be obeyed — the
breakpoints are R's pretty() over the range of the data, so they fall on
round numbers and the axis is rounded outwards past the extremes. Ask for 5
bins over c(1,2,2,3,4,7,9,10,11,15) and you get eight, at 0, 2, 4 … 16, which
is what R's hist() gives for the same request. When breaks is omitted the
suggestion is R's nclass.Sturges, ⌈log₂ n + 1⌉.
Counts are of right-closed intervals with the lowest included — (a, b],
except the first, which is [a₀, b₁] — carrying R's 1e-7 fuzz, so a value that
lands a rounding error above a breakpoint still counts in the bin below it.
density is counts / (n × width) over the unfuzzed breaks. Pinned against R
across thirteen datasets and eight breaks settings in t/hist.R.t.
hosmer_lemeshow
The Hosmer-Lemeshow goodness-of-fit test for a logistic-regression model. Given
the observed 0/1 outcomes and the model's predicted probabilities, it bins the
observations into g risk groups (deciles by default) and compares observed and
expected event counts. A large p-value indicates the model fits adequately. The
grouping and statistic follow R's ResourceSelection::hoslem.test, against which
it was validated numerically.
# $fit is a binomial glm(); align observed outcomes with fitted_values
my @obs  = map { $data{$_}{outcome} } @ids;
my @prob = map { $fit->{'fitted_values'}{$_} } @ids;

my $hl = hosmer_lemeshow(\@obs, \@prob, g => 10);
printf "HL chi2=%.2f df=%d p=%.3f\n", $hl->{statistic}, $hl->{parameter}, $hl->{'p_value'};
Input Parameters
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| observed | ArrayRef | None (Required) | Observed binary outcomes (0/1). | \@obs |
| predicted | ArrayRef | None (Required) | Model-predicted probabilities (same length). | \@prob |
| g | Integer | 10 | Number of risk groups (quantile bins). | 10 |
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| statistic | Double | Hosmer-Lemeshow chi-squared statistic. | 4.3456 |
| parameter | Integer | Degrees of freedom, g - 2. | 8 |
| p_value | Double | Goodness-of-fit p-value (large = good fit). | 0.825 |
| groups | Integer | Number of non-empty groups used. | 10 |
| table | ArrayRef | Per-group {n, observed, expected} event summaries. | |
hurdle
A two-part count model, pscl::hurdle() (also countreg::hurdle()): a binary
model for whether the count is zero, and a zero-truncated count
model for how large it is given that it is positive. The typical use is an
outcome such as inpatient days, where "any stay" and "how long" have different
explanations.
use Stats::LikeR 'hurdle';

my $h = hurdle(formula => 'days ~ hours + age | hours', data => \%d,
               dist => 'negbin');
print $h->{coefficients}{count}{hours};    # log rate ratio, given a stay
print $h->{coefficients}{zero}{hours};     # log odds of any stay
The regressors after | are the zero part's; without a bar both parts use the
same ones. The likelihood separates into the two parts, so they are fitted
separately, as both packages do by default.
| Option | Default | Description |
| --- | --- | --- |
| formula | (required) | 'y ~ count regressors' or 'y ~ count regressors \| zero regressors'; offset() terms are allowed in either part. |
| data | (required) | HoA, AoH or HoH. |
| dist | 'poisson' | The count part: 'poisson', 'negbin' or 'geometric'. |
| zero_dist | 'binomial' | The zero part: 'binomial' (a logit), or a count distribution censored at 1, 'poisson', 'negbin' or 'geometric'. |
| link | 'logit' | The binomial zero part's link; only 'logit' is implemented. |
| offset | none | A column, an expression or an array ref, added to the count part only, as pscl's offset = is; an offset() term in the zero part's formula offsets that part. |
| weights | none | Case weights. |
| conf_level | 0.95 | Level of the Wald intervals in summary. |
The result holds coefficients, summary (with Estimate, Std. Error,
z value, Pr(>|z|), CI_lower, CI_upper), vcov and terms, each split
into count and zero halves; loglik and its two parts loglik_count and
loglik_zero, aic, df_residual, nobs, converged, iter and
iter_zero; theta and SE_logtheta for a negbin count part, and
theta_zero/SE_logtheta_zero for a negbin zero part; and fitted_values,
the fitted mean P(y > 0) mu / (1 - f(0)). Validated against pscl and
countreg on their documented examples, with a third opinion from mpmath.
interpolate
Fill NA (undef) cells along the row axis, like pandas.DataFrame.interpolate.
It is the numeric sibling of ffill/bfill: rather than only propagating a
neighbour's value into a gap, it can fit a curve (line, spline, polynomial…)
through the surrounding numeric values and read the gap off that curve. Every
one of pandas' interpolation methods is supported and matched to pandas /
scipy within 1e-6 (see Method accuracy below).
interpolate($df,
    method          => 'cubic',      # any method below (default: 'linear')
    cols            => [ 'v' ],      # restrict to these columns (default: every column)
    order           => 3,            # degree, required by 'polynomial' / 'spline'
    x               => 't',          # abscissae: column name/index or arrayref
    limit           => 2,            # max cells filled per NA run (default: unlimited)
    limit_direction => 'forward',    # 'forward' (default), 'backward', or 'both'
    limit_area      => 'inside',     # 'inside', 'outside', or omit for both
);
Column identifiers are names for AoH/HoA/HoH and 0-based positions for AoA. The
row axis is positional for AoA/AoH/HoA and string-sorted key order for HoH — the
same shape and ordering rules as ffill/bfill. Returns a NEW frame; the input
is never modified.
Methods
| method | What it does |
|---|---|
| linear (default) | straight line between the nearest anchors, rows equally spaced |
| index, values, time | straight line, but spaced by the x coordinates |
| slinear | piecewise linear, interior gaps only |
| nearest | value of the nearer anchor, interior only |
| zero | value of the left anchor (zero-order hold), interior only |
| pad / ffill | hold the last value forward |
| bfill / backfill | hold the next value backward |
| quadratic, cubic | degree-2 / degree-3 interpolating B-spline (scipy interp1d) |
| cubicspline | not-a-knot cubic spline (scipy CubicSpline) |
| pchip | monotone piecewise cubic Hermite (Fritsch–Carlson) |
| akima | Akima piecewise cubic |
| barycentric, krogh | single global polynomial through all anchors |
| polynomial | degree-order interpolating spline (order required) |
| spline | interpolating spline of degree order (order required) |
How gaps and edges are filled
Interpolation follows pandas exactly: every gap is filled from the method, then
cells that limit / limit_direction / limit_area forbid are blanked back to
NA. Only numeric cells anchor a fill; a defined non-numeric cell is preserved
(and, for the piecewise-local methods, blocks interpolation across it).
Interior gaps (anchors on both sides) are always filled. Leading/trailing gaps (an edge with anchors on one side only) behave by method family:
linearand the hold methods (pad/bfill) fill the edge with the held constant, subject tolimit_direction.barycentric,krogh,cubicspline,pchipextrapolate the edge from the fitted curve, again subject tolimit_direction.- the
interp1dfamily (nearest,zero,slinear,quadratic,cubic,polynomial),akima, andsplineare interior-only — they leave leading/trailing gaps as NA, matching scipy.
limit_direction chooses which edge is filled (forward → trailing, backward
→ leading, both → both) and, with limit, which cells a run's cap reaches.
limit_area restricts filling to 'inside' (interior) or 'outside'
(edges only). Interpolated cells are floats; filling stays within each column's
existing length (ragged HoA columns and short AoA rows are not extended).
The x argument
By default rows are equally spaced (0, 1, 2, …). Pass x to interpolate
against real abscissae — either an arrayref (one coordinate per row) or a column
name/index whose numeric values are the coordinates. x must be strictly
increasing and is used by every method except plain linear semantics (use
index/values for a line on unequal spacing).
# linear fit on unequal spacing
interpolate({ v => [ 0, undef, undef, 10 ] }, method => 'index', x => [ 0, 1, 3, 4 ]);
# { v => [ 0, 2.5, 7.5, 10 ] }

# interpolate v against a time column t
interpolate($df, cols => [ 'v' ], x => 't', method => 'index');
Examples
# linear: interior interpolated, trailing held (forward default), leading NA
interpolate({ v => [ undef, 1, undef, undef, 4, undef ] });
# { v => [ undef, 1, 2, 3, 4, 4 ] }

# cubic spline through four anchors that lie on x^2, so the fit is exact
interpolate({ v => [ 0, undef, undef, 9, 16, 25 ] }, method => 'cubic', limit_direction => 'both');
# { v => [ 0, 1, 4, 9, 16, 25 ] }

# monotone pchip vs. a global polynomial on the same gaps
interpolate({ v => [ 2, undef, 3, undef, undef, 2, 5, undef, 0 ] }, method => 'pchip', limit_direction => 'both');
Method accuracy
linear, index/values/time, slinear, nearest, zero, pad/ffill,
bfill/backfill, quadratic, cubic, cubicspline, pchip, akima,
barycentric, krogh, and polynomial reproduce pandas/scipy to machine
precision (the test suite compares against pandas 2.2.3 / scipy 1.15.2).
Two deliberate departures from pandas:
splineis the interpolating spline of degreeorder(equivalent to pandas'splinewiths=0), because pandas' defaultsplineis a FITPACK smoothing spline that is not reproducible without FITPACK. It does not extrapolate edges.polynomial/splinesupportorder1, 2, or 3.- A defined non-numeric cell is treated as a barrier by the piecewise-local methods; pandas has no equivalent (its columns are all-numeric).
Performance: the per-column numeric core (every method, the linear solve and
the preserve mask) runs in XS. Versus the former pure-Perl kernels this is
roughly 5× faster for linear on a large column, ~11× for pchip, and ~50×
for the spline methods whose dense solve dominates. The fit-based methods
still use a dense solve, so they target modest per-column anchor counts.
Errors
Dies on: undefined data; an odd trailing argument list; an unknown argument or
method; polynomial/spline without an integer order in 1–3; a cols or x
column that does not exist; too few anchors for the chosen method; an x that is
not strictly increasing or whose length does not match; a limit that is not a
positive integer; or an invalid limit_direction/limit_area.
intersection
Returns the set intersection (∩) of a list of array references: the values that appear in every array ref given.
use Stats::LikeR;

my @i = intersection([1, 2, 3], [2, 3, 4]);          # (2, 3)
my @t = intersection([1, 2, 3, 4], [2, 3, 4], [3, 4]); # (3, 4)
my $n = intersection([1, 2, 3], [2, 3, 4]);          # 2
Every argument must be an array reference: each one is treated as a set.
Unlike mean and uniq, bare scalars are not accepted; passing a non-reference
(or a non-array reference) croaks.
The result is deduplicated and ordered by first appearance in the first
array ref. Duplicate values within any single ref are counted once, so
intersection([1, 2, 2, 3], [2, 3, 3, 4]) is (2, 3), not (2, 2, 3).
Values are compared by stringification — the same eq semantics used by
uniq. 1, 1.0, and "1" are treated as equal, while "3" and "3.0"
are distinct. The UTF-8 flag is part of the comparison key, so a UTF-8 string
and a byte-identical non-UTF-8 string are kept separate.
In list context intersection returns the shared values; in scalar context it
returns the cardinality (the number of shared values).
With a single array ref, the result is simply that ref's unique values. If any ref is empty, the intersection is empty.
intersection croaks on degenerate or ill-formed input, reporting the
offending position:
intersection();              # croaks: intersection needs >= 1 array ref
intersection([1, 2], 3);     # croaks: argument 1 is not an array ref
intersection([1, undef, 3]); # croaks: undefined value at array ref index 1 (argument 0)
This matches the undef-handling of mean and uniq and the rest of the
numeric reducers in Stats::LikeR.
is_equivalent
is_equivalent(\@a, \@b, ...) returns 1 if every list holds the same
set of distinct values, and 0 otherwise. Order and duplicates don't
count — only which values are present.
Think of each list as a bag, dump each bag into its own set, and ask: are all the sets identical?
is_equivalent([1,2,3], [3,2,1])     # 1  same values, different order
is_equivalent([1,1,2], [2,1])       # 1  duplicates ignored
is_equivalent([1,2,3], [1,2])       # 0  right is missing 3
is_equivalent([1,2],   [1,2,3])     # 0  right has an extra 4
is_equivalent([1,2], [2,1], [1,2])  # 1  works for any number of lists
It generalises List::Compare's is_LequivalentR() from two lists to N.
How it decides
Equivalence is transitive: if every list equals the first list, they all equal each other. So the check is simple — build the distinct-value set of the first list, then hold each other list up against it. A list matches when:
- it contains no value outside the first set, and
- it covers every value in the first set.
Fail either test for any list and the answer is 0.
Edge cases
is_equivalent([], [])        # 1  two empty sets are equal
is_equivalent([], [1])       # 0  empty vs non-empty
is_equivalent([1], [1], [1]) # 1
Values are compared as strings (like hash keys), so 1 and "1" are the
same, but 2 and "2.0" are not.
Rules
- Pass at least two array refs. Fewer croaks.
- Every argument must be an array ref; anything else croaks.
undefinside a list croaks — decide what a missing value means before calling, rather than letting it silently match.
ivreg
Instrumental-variables regression by two-stage least squares, ivreg::ivreg()
(and AER::ivreg()), with summary(fit, diagnostics = TRUE)'s tests. The
standard errors are the proper 2SLS ones, from the residuals of the structural
equation with the original regressors, not the naive ones that come from
running the two stages as separate lm fits.
use Stats::LikeR 'ivreg';

# regressors | instruments: exogenous regressors appear on both sides
my $iv = ivreg(formula => 'log(packs) ~ log(rprice) + log(rincome) | log(rincome) + tdiff + rtax',
               data => \%cig);
# or three parts: exogenous | endogenous | excluded instruments
my $iv3 = ivreg(formula => 'log(packs) ~ log(rincome) | log(rprice) | tdiff + rtax',
                data => \%cig, cluster => 'state');

my $d = $iv->{diagnostics};
printf "first-stage F = %.1f\n", $d->{weak}{'log(rprice)'}{statistic};
| Option | Default | Description |
| --- | --- | --- |
| formula | (required) | 'y ~ regressors \| instruments', or 'y ~ exogenous \| endogenous \| instruments'. Terms expand as for lm. |
| data | (required) | HoA, AoH or HoH. |
| weights | none | Weights, as ivreg(weights = ). |
| vcov | 'model' | 'model', 'HC0' or 'HC1'; the diagnostics use the same covariance, as when summary.ivreg is given vcov. = . |
| cluster | none | A cluster variable (column name or array ref) for sandwich::vcovCL; implies 'HC0'. |
| conf_level | 0.95 | Level of conf_int. |
The result holds coefficients, summary (per term Estimate,
Std. Error, t value, Pr(>|t|)), vcov, vcov_type, conf_int,
terms, endogenous and instruments (the terms each role was given),
fitted_values, residuals, sigma, rss, r_squared, adj_r_squared,
df_residual, rank, nobs, n_clusters with a cluster, and waldtest, the
F test of every coefficient but the intercept. diagnostics has
weak: per endogenous regressor, the first-stage F test of the excluded instruments (statistic,df1,df2,p_value);wu_hausman: the test of whether the endogenous regressors are in fact exogenous: an F test of the first-stage residuals added to the structural regression;sargan: with more instruments than endogenous regressors, the test of overidentifying restrictions (statistic,df,p_value).
Validated against ivreg's tests and documented examples, and against Stata
ivreg2 output that statsmodels pins. For a count outcome, see the
control-function note under glm.
kruskal_test
Essentially the test determines if all groups have the same median (same distribution) (an excellent review is at https://library.virginia.edu/data/articles/getting-started-with-the-kruskal-wallis-test)
Performs a Kruskal-Wallis rank sum test, see https://www.rdocumentation.org/packages/stats/versions/3.6.2/topics/kruskal.test
hash of array entry
I feel that this is better, and more easily read, than what you get in R:
my %x = (
'normal.subjects' => [2.9, 3.0, 2.5, 2.6, 3.2],
'obs. airway disease' => [3.8, 2.7, 4.0, 2.4],
'asbestosis' => [2.8, 3.4, 3.7, 2.2, 2.0]
);
$kt = kruskal_test(\%x);
R-like array entry
my @xk = (2.9, 3.0, 2.5, 2.6, 3.2); # normal subjects
my @yk = (3.8, 2.7, 4.0, 2.4);      # with obstructive airway disease
my @zk = (2.8, 3.4, 3.7, 2.2, 2.0); # with asbestosis
my @x = (@xk, @yk, @zk);
my @g = (
	(map {'Normal subjects'} 0..4),
	(map {'Subjects with obstructive airway disease'} 0..3),
	map {'Subjects with asbestosis'} 0..4
);
my $kt = kruskal_test(\@x, \@g);
missing values, and groups with no data
Non-numeric, undefined and NaN elements are silently dropped before the test
runs, matching R's complete.cases(x, g) — NaN is NA to R, so it goes too.
+Inf and -Inf are neither, and a rank test has no trouble with them, so
they are kept and ranked.
A group left with no usable observation is refused rather than guessed at, as
R's list interface does: kruskal_test croaks all groups must contain data.
That covers an empty array reference and one whose every element was dropped.
Counting such a group would inflate the degrees of freedom, and testing only
the groups that do have data under a df that counts one that does not is not
a test of anything. (SciPy takes the other side of this and returns NaN.)
A sample with no variation at all gives a tie correction of exactly zero, so
the statistic is 0/0: like R, statistic and p_value come back as NaN.
returned fields
statistic, parameter (the degrees of freedom) and method are R's htest
fields; the p-value is p_value (R's dotted p.value is not a key). On top of
those, group_stats holds size and mean sub-hashes keyed by your own group
labels, computed over the same observations the statistic used.
ks_test
The Kolmogorov–Smirnov test checks whether two samples are drawn from the same distribution (two-sample), or whether a single sample is drawn from a given reference distribution (one-sample). It works by comparing the empirical cumulative distribution functions (ECDFs) and measuring the largest gap between them.
Two-sample form — pass two array references:
$ks = ks_test(\@x, \@y);
$ks = ks_test(\@x, \@y, alternative => 'greater');
One-sample form — pass one array reference and the name of a reference CDF.
Currently only 'pnorm' is supported, i.e. the standard normal distribution
(mean 0, standard deviation 1):
$ks = ks_test(\@x, 'pnorm');
Arguments may be given positionally (as above) or by name:
$ks = ks_test(x => \@x, y => \@y, alternative => 'less', exact => 1);
Non-numeric, undefined and NaN elements are silently dropped before the test
runs, matching R's x[!is.na(x)].
alternative selects which gap between the ECDFs is measured:
'two.sided'(default) — the largest gap in either direction, D = sup |F_x − F_y|.'greater'— the largest gap where x's ECDF rises above the other, D⁺ = sup (F_x − F_y).'less'— the largest gap in the other direction, D⁻ = sup (F_y − F_x).
These follow R's ks.test convention: 'greater'/'less' describe which CDF
lies above the other, which (because a higher CDF means smaller values) is
the opposite of which sample tends to be larger.
exact controls how the p-value is computed. Omit it to let the test choose:
the exact distribution is used for small samples (two-sample when nx·ny
10000, one-sample when n < 100) and the asymptotic (Kolmogorov limiting)
approximation otherwise. Pass exact => 1 to force the exact computation or
exact => 0 to force the asymptotic one. Exact p-values cannot be computed
when the data contain ties; if ties are present on the exact path, the test
warns and falls back to the asymptotic p-value. (The exact one-sample test is
only available for the two-sided alternative; a one-sided one-sample request
also falls back to asymptotic.) In either fallback the returned method is
the asymptotic one, so it always names the p-value you actually got.
Return value
ks_test returns a hash reference with four keys:
statistic— the KS statistic for the chosenalternative: D, D⁺, or D⁻. It is the maximum distance between the two ECDFs (or, for the one-sample test, between the ECDF and the reference CDF), always in the range [0, 1]. Larger values mean the distributions are further apart.p_value— the probability, under the null hypothesis that the samples share a distribution, of observing a statistic at least this large. It is clamped to [0, 1]; a small value (e.g. < 0.05) is evidence against the null.method— a human-readable description of exactly what was run, handy for logging or reproducing a result. One of:"Two-sample Kolmogorov-Smirnov exact test","Two-sample Kolmogorov-Smirnov test (asymptotic)","One-sample Kolmogorov-Smirnov exact test", or"One-sample Kolmogorov-Smirnov test (asymptotic)".alternative— the alternative hypothesis that was applied ('two.sided','greater', or'less'), echoed back so the result is self-describing.
For example:
my $ks = ks_test(\@x, \@y);
if ($ks->{'p_value'} < 0.05) {
    printf "reject H0: D=%.4f, p=%.4g (%s)\n",
        $ks->{statistic}, $ks->{'p_value'}, $ks->{method};
}
kurtosis
Sample excess kurtosis — how much of the variance sits in the tails rather than
near the shoulders. The 3 of a normal distribution is already subtracted, so a
normal sample gives roughly 0, a heavy-tailed one a positive number, and a flat
or bimodal one a negative number. Add 3 if you want the plain fourth
standardized moment. Validated numerically against R.
kurtosis(2, 4, 4, 4, 5, 5, 7, 9); # 0.940625
Kurtosis is the fourth moment, so what it describes is the tails. Below, three
samples standardized to mean 0 and standard deviation 1 — a uniform sample,
which has no mass at all left for the extremes; a normal sample; and a scale
mixture of two normals, one observation in ten drawn with three times the spread
— each against the same N(0, 1) curve in grey, so that the only thing that
differs between the panels is shape. On a linear axis (the top row) the
heavy-tailed sample looks like little more than a sharper peak; the bottom row
is the same three estimates on a logarithmic density, where the tail that the
positive number is reporting is visible over three decades.
Arguments work as they do for sd and var: plain numbers, array references, or any mixture of the two, all flattened into one sample.
my @x = (2, 4, 4, 4, 5, 5, 7, 9);
kurtosis(@x);                  # a list
kurtosis(\@x);                 # an array reference
kurtosis([2, 4, 4], 4, [5, 5, 7, 9]);   # mixed; same sample
kurtosis(x => \@x);            # named, if you prefer it
type
There are three conventions in circulation for turning the moment ratio into a
sample statistic, and they disagree noticeably on small samples. type picks
one; the default is 2.
| type | Statistic | Also known as |
|--------|-----------|---------------|
| 1 | g2 | the plain moment ratio; R's moments::kurtosis minus 3 |
| 2 | G2 | the default; SAS, SPSS, Stata, Excel's KURT(), scipy.stats.kurtosis(bias => FALSE) |
| 3 | b2 | e1071::kurtosis's own default |
where, writing m2 and m4 for the second and fourth central moments (each
divided by n):
g2 = m4 / m2**2 - 3                                     # type 1
G2 = ((n + 1) * g2 + 6) * (n - 1) / ((n - 2) * (n - 3))  # type 2, the default
b2 = (g2 + 3) * (1 - 1 / n)**2 - 3                      # type 3

my @x = (1, 2, 3, 10);
kurtosis(\@x, type => 1);   # -0.7696   plain moment ratio
kurtosis(\@x);              #  3.228    G2, the default
kurtosis(\@x, type => 3);   # -1.7454   b2
type => 2 is the estimator that is unbiased for a normal sample, which is why
it is the default and why it is what every general-purpose statistics package
reports. It divides by n - 3, so it needs at least four values; the other two
need at least two.
my $shape = { skew => skew($lab), kurtosis => kurtosis($lab) };
Errors
kurtosis croaks, naming the offending position, on an undefined value:
kurtosis(1, undef, 3);
# kurtosis: undefined value at argument index 1

kurtosis([1, 2, undef]);
# kurtosis: undefined value at array ref index 2 (argument 0)
and on a sample too small for the chosen type, on a type outside 1 .. 3, or
on a constant sample, which has no shape to report:
kurtosis([7, 7, 7, 7]);
# kurtosis: zero variance (all 4 values are equal), so kurtosis is undefined
See also
skew for the third moment, sd and var for the second, shapiro_test to test normality rather than describe the departure from it.
ljoin
Consider a hash: $h{$row}{$col}, and another hash $i{$row}{$col2}.
ljoin will add information for $col in %i for each $row to %h, where $row exists in both %h and %i.
Similar to cbind in R.
For example,
{
"Jack Smith"   {
    age   30
}
}
and a second hash,
{
    "Jack Smith"   {
        dept   "Engineering"
    },
    "Jane Doe"     {
        age   25
    }
}
in this case, running ljoin(\%h, \%i) will modify %h to result:
{
"Jack Smith"   {
    age    30,
    dept   "Engineering"
}
}
lm
This is the linear models function.
$lm = lm(formula => 'mpg ~ wt + hp', data => $mtcars);
where $mtcars is a hash of hashes
lm also supports generating interaction terms directly within the formula using the * operator:
my $lm = lm(formula => 'mpg ~ wt * hp^2', data => \%mtcars);
Crossing is associative, so * chains to any depth: y ~ a * b * c expands to
every non-empty subset of the three (a, b, c, a:b, a:c, b:c,
a:b:c), ordered by degree as R's terms() orders them. Writing a:b directly
gives just that one product.
Either side of an interaction may be a string (categorical) column, in which
case it expands to indicator columns the same way a main effect does:
len ~ dose * supp yields dose, suppVC and dose:suppVC.
Whether a categorical column keeps all of its levels or drops the first as a
reference follows R's margin rule: the reference level is dropped when the term
with that column removed is itself in the model. A main effect's margin is the
intercept, so y ~ g drops g's first level — but y ~ g - 1 has no intercept
to measure against and so keeps every level, one column per group. Where two
categorical main effects both have no intercept, only the first can be coded in
full (y ~ a + b - 1 gives every level of a and drops b's reference),
because coding both in full would be rank deficient. A bare y ~ a:b with
neither main effect present codes both in full and spans the whole
cross-classification.
If your data contains missing numbers (NA or undef), lm handles listwise deletion dynamically to ensure mathematical integrity before fitting. A row whose categorical value is missing is dropped the same way.
Three details differ from R deliberately:
- Levels are sorted with
strcmp, i.e. by byte value, which is whatpatsy/pandasdoes. R sorts with the collation of the running locale, so a factor whose levels differ only in case takes a different reference level in the two: onc("b", "A", "a")R takesaandlmtakesA. Both parameterise the same fit — residual sum of squares, rank and fitted values agree — but the coefficient names and values differ. - A term crossed with itself keeps the product, so
wt:wtiswtsquared andy ~ wt*wtfitsy ~ wt + I(wt^2). R's formula algebra collapsesa:atoa, making the same formula meany ~ wtthere. - A categorical column with only one level contributes no column, so
y ~ x + gfitsy ~ x. R refuses the model outright ("contrasts can be applied only to factors with 2 or more levels").
the dot operator also works:
$lm = lm(formula => 'y ~ .', data => $dot_data);
lm and glm read their formula and their data through the same code, so
everything above holds for both, and a fit's terms are the terms the other
function would have produced from the same string.
Rows are labelled from a row_names, _row, rownames or .rownames column if
the data has one (a HoH labels rows with its outer keys, which needs no such
column), and 1-based integers otherwise. Those labels are the keys of
fitted_values and residuals, and the row names predict returns. A row-name
column is a label rather than a measurement, so y ~ . leaves it out of the
predictors.
The overall model F test is returned as fstatistic (an array ref of F,
numerator df, denominator df) and f_pvalue. f_pvalue is evaluated in the
upper tail of the F distribution rather than as 1 - pf(F, df1, df2), so a
strongly significant model reports its actual p-value instead of a flat 0;
see F and z tail p-values. The per-coefficient
Pr(>|t|) values were already computed as a direct two-tail probability and
are unaffected.
lmer
Linear mixed-effects regression, lme4::lmer(), fitted by REML (the default)
or maximum likelihood, with the Satterthwaite degrees of freedom and t tests
that lmerTest adds to its summary.
use Stats::LikeR 'lmer';

# a random intercept and a random slope for Days, correlated, per Subject
my $m = lmer(formula => 'Reaction ~ Days + (Days | Subject)', data => \%sleepstudy);
printf "Days: %.2f (SE %.2f, df %.1f)\n",
    @{ $m->{summary}{Days} }{'Estimate', 'Std. Error', 'df'};
printf "subject sd of the slope: %.2f\n", $m->{varcor}[0]{sd}{Days};
Random-effects terms are written as in lme4: (1 | g) a random intercept,
(x | g) a correlated intercept and slope, (0 + x | g) a slope alone, so that
(1 | g) + (0 + x | g) is the uncorrelated pair; several grouping factors,
crossed or nested, are allowed, and (1 | a/b) expands to (1 | a) + (1 | a:b).
The fixed part is expanded as for lm.
| Option | Default | Description |
| --- | --- | --- |
| formula | (required) | Fixed effects plus one or more ( terms \| group ) random-effects terms. |
| data | (required) | HoA, AoH or HoH. |
| REML | 1 | 0 for a maximum-likelihood fit (needed to compare fixed effects by likelihood ratio). |
| conf_level | 0.95 | Level of conf_int, from the Satterthwaite t. |
The result holds coefficients, summary (per term Estimate,
Std. Error, df, t value, Pr(>|t|)), vcov, conf_int, terms,
fitted_values (including the predicted random effects), sigma (residual
sd), theta (lme4's relative covariance factor, getME(fit, "theta")),
REML or deviance (the criterion minimised), loglik, AIC, BIC,
nobs, reml, converged and singular (a variance component on its
boundary, lme4's "singular fit"). varcor is VarCorr(): one entry per
random-effects term, in formula order, each with group, levels, names,
sd by name and the correlation matrix corr.
The criterion is lme4's profiled deviance, minimised by Nelder-Mead and
then polished by Newton steps, so the estimates are those of a tightly
converged lme4 fit; lme4's default optimiser stops about 1e-6 short in
theta, which moves the standard errors in their fifth digit. Validated against
lme4, lmerTest and statsmodels' mixed-model corpora.
logrank_test
The log-rank (Mantel–Cox) test: do the survival curves of two or more groups
differ? It needs no modelling assumptions. Same as R's survival::survdiff.
Give times, an event flag (1 = event, 0 = censored), and a group label per row:
use Stats::LikeR 'logrank_test';

my $r = logrank_test(\@time, \@status, \@group);
print $r->{'p_value'};
Result keys: statistic (chi-squared), parameter (df = groups − 1),
p_value, observed and expected events per group, and groups. See
survfit for the curves and coxph to adjust for
covariates.
Lonly
my @only_first = Lonly(\@a, \@b, \@c);
my $count      = Lonly(\@a, \@b, \@c);
Takes one or more array references and returns the values that appear in the
first reference and in no other reference; with a single reference it
returns that list's distinct values. Duplicates collapse, the result keeps
first-appearance order, and scalar context returns the count. Values are
compared by string form (see get_union). A non-array-ref argument or an
undef element is fatal. With exactly two references this is the left-only
set difference. Mirrors List::Compare's get_unique, which likewise
defaults to the first list.
my @a = (1, 2, 3);
my @b = (3, 4, 5);
my @c = (5, 6);
my @u = Lonly(\@a, \@b, \@c);           # (1, 2)  -- 3 is also in @b
matrix
my $mat1 = matrix(
	data => [1..6],
	nrow => 2
);
You can also pass byrow => 1 if you want the matrix populated row-wise instead of column-wise.
Parameters do not need to be named, so that matrix works more like R:
my $d = matrix(rnorm(32000), 1000, 32);
works as data, nrow, and ncol
max
max(1,2,3);
or
my @arr = 1..8;
max(@arr, 4, 5)
max will die if any undefined values are provided. A NaN anywhere in the input makes the answer NaN, as it does in R.
See Compared with List::Util under sum for the other ways it differs from List::Util's max.
mcnemar_test
McNemar's test for paired categorical data (e.g. before/after, matched
case-control, two raters), a faithful port of R's stats::mcnemar.test. It
assesses whether the off-diagonal disagreement in a square table is symmetric.
For a 2×2 table a Yates continuity correction is applied by default (toggle with
correct); exact => 1 instead performs the two-sided exact binomial test.
Larger k × k tables use the generalized chi-square (df = k(k-1)/2). Validated
numerically against R.
# counts as a square matrix: [[a, b], [c, d]]
my $r = mcnemar_test([[794, 86], [150, 570]]);
printf "chi2=%.2f df=%d p=%.4g\n", $r->{statistic}, $r->{parameter}, $r->{'p_value'};

# small samples: exact binomial test on the discordant pairs
my $e = mcnemar_test([[794, 86], [150, 570]], exact => 1);

# paired observation vectors are cross-tabulated automatically
my $v = mcnemar_test(\@before, \@after);
The first argument is either a square matrix (array of array refs) or, in the two-argument form, two equal-length vectors of paired observations that are cross-tabulated over their sorted union of levels.
Input Parameters
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| table / x | ArrayRef | None (Required) | A square k × k count matrix, or (two-arg form) the first vector of paired observations. | [[794,86],[150,570]] |
| y | ArrayRef | None | Second vector of paired observations (two-arg form only). | \@after |
| correct | Boolean | 1 | Apply the Yates continuity correction (2×2 only). | 0 |
| exact | Boolean | 0 | Use the two-sided exact binomial test (2×2 only). | 1 |
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| statistic | Double | McNemar's chi-squared (or, for exact, the discordant success count b). | 16.8178 |
| parameter | Integer | Degrees of freedom, k(k-1)/2 (absent for exact). | 1 |
| p_value | Double | The p-value. | 4.1e-05 |
| method | String | Description of the test performed. | "McNemar's Chi-squared test with continuity correction" |
mean
mean(1,2,3);
or
my @arr = 1..8;
mean(@arr, 4, 5)
or
mean([1,1], [2,2]) # 1.5
mean will die if any undefined values are provided
median
works like mean, taking array references and arrays:
median( $test_data[$i][0] )
median will die if any undefined values are provided
melt
Reshape a wide frame to long form, like pandas.DataFrame.melt. One or more
identifier columns (id_vars) are repeated down the output; every other
selected column (value_vars) is unpivoted into a variable/value pair.
melt($df,
    id_vars      => 'A' | [ 'A', 'B' ],   # kept, repeated (default: none)
    value_vars   => 'C' | [ 'C', 'D' ],   # unpivoted (default: all non-id cols)
    var_name     => 'variable',           # name of the column-name column
    value_name   => 'value',              # name of the value column
    'output_type' => 'aoh',               # aoa|aoh|hoa|hoh (default: input family)
);
Column identifiers are names for AoH/HoA/HoH frames and 0-based integer
positions for AoA. value_vars defaults to every column not in id_vars, in
colnames() order.
Output row order is column-major: all rows for value_vars[0], then all
rows for value_vars[1], and so on, preserving input row order within each
block. HoH output has no natural row axis, so labels are reset to a
0 .. N-1 range index.
Returns a NEW frame; the input is never modified.
Example
my $df = [ { A => 'a', B => 1, C => 2 },
           { A => 'b', B => 3, C => 4 } ];
melt($df, id_vars => 'A', value_vars => [ 'B', 'C' ]);
# [ { A => 'a', variable => 'B', value => 1 },
#   { A => 'b', variable => 'B', value => 3 },
#   { A => 'a', variable => 'C', value => 2 },
#   { A => 'b', variable => 'C', value => 4 } ]
NA cells (undef, or a missing hash key) melt through to value => undef.
Errors
Dies on: undefined data; an odd trailing argument list; an unknown argument; an
unknown output_type; a value_vars/id_vars column that does not exist;
var_name equal to value_name; or var_name/value_name colliding with an
id_vars column name.
merge
A full relational join of two data frames, in the spirit of R's merge and pandas' DataFrame.merge. Where ljoin only does an in-place left join of a hash-of-hashes keyed by row name, merge supports every common join type, single- or multi-column keys, keys with different names on each side, column-collision suffixes, and any mix of input/output shapes.
my $joined = merge($left, $right, how => 'inner', on => 'id');
$left and $right may each be an AoH (array of row hash references), a HoA (hash of column array references), or a HoH (hash of row hash references; the outer key is treated as a row and is not used as a join key). Both frames are read non-destructively.
Join types (how)
inner(default) — only rows whose keys match in both frames.left— every$leftrow, plus matching$rightcolumns (unmatched$rightcolumns becomeundef).right— every$rightrow; the mirror image ofleft.outer(aliasfull) — the union: all rows from both frames.cross— the Cartesian product of the two frames; takes no keys.
Choosing the keys
on => 'col'oron => ['c1', 'c2']— join on one or more columns present under the same name in both frames.byis an accepted synonym (R spelling).'left_on' => .., 'right_on' => ..— keys with different names on each side (each a name or an array reference of equal length).by_x/by_yare accepted synonyms; the dotted spellings (left.on,right.on,by.x,by.y) are refused as unknown arguments. The result carries a single key column under the left name.- If neither is given,
mergeperforms a natural join on the sorted intersection of the two frames' column names (it dies if that intersection is empty).
Keys are matched on the stringified cell value. A row whose key cell is undef (or absent) never matches, so such a row is dropped by an inner/right join and appears only as a left- or right-only row in a left/outer/right join. This is SQL's rule for NULL keys, and R's merge(..., incomparables = NA); note that it is not what either reference does by default — R's default (incomparables = NULL) and pandas both match a missing key to a missing key.
Colliding columns (suffixes)
A non-key column that appears in both frames would collide, so each copy is renamed by appending a suffix: .x to the left copy and .y to the right by default (R's convention). Override with suffixes => ['_left', '_right'].
Under left_on/right_on the same applies to a right-hand non-key column named after the left key, since the single output key column carries the left name: it is suffixed too, as R does with no.dups = TRUE. If the suffixes still leave two output columns sharing a name, merge dies rather than return a frame with a column missing.
Output shape
By default the result matches the shape of $left (a HoH left frame yields an AoH, since a joined frame has no single row-name key). Force it with 'output_type' => 'aoh' or 'output_type' => 'hoa'.
Example
my $emp  = [ { id => 1, name => 'Alice', dept => 10 },
             { id => 2, name => 'Bob',   dept => 20 },
             { id => 3, name => 'Carol', dept => 30 } ];
my $dept = [ { dept => 10, dname => 'Sales' },
             { dept => 20, dname => 'Engineering' } ];

my $left = merge($emp, $dept, how => 'left', on => 'dept');
#  [ { id => 1, name => 'Alice', dept => 10, dname => 'Sales' },
#    { id => 2, name => 'Bob',   dept => 20, dname => 'Engineering' },
#    { id => 3, name => 'Carol', dept => 30, dname => undef } ]
See also ljoin (in-place HoH left join), concat / rbind (stacking frames row-wise), and group_by.
min
min(1,2,3);
or
my @arr = 1..8;
min(@arr, 4, 5)
min will die if any undefined values are provided. A NaN anywhere in the input makes the answer NaN, as it does in R.
See Compared with List::Util under sum for the other ways it differs from List::Util's min.
mode
Takes either an array or an array reference, and returns an array of the most common scalars (numbers or strings)
@arr = mode([1,3,3,3]); # returns (3)

@arr = mode('a','a','c','c','z'); # returns ('a', 'c')
ncol
ncol($frame) returns how many columns a data frame has. Like nrow, it
works on all the Stats::LikeR frame shapes, so you don't have to remember which
one you're holding:
ncol([ [1,2,3], [4,5,6] ])         # 3   array of arrays  (AoA)
ncol([ {a=>1,b=>2}, {a=>3,b=>4} ]) # 2   array of hashes  (AoH)
ncol({ a=>[1,2], b=>[3,4] })       # 2   hash of arrays   (HoA)
ncol({ r1=>{...}, r2=>{...} })     # 2   hash of hashes   (HoH)
NB
A column is one field of each record. Where the fields live depends on the shape:
- Array of hashes (AoH) — each row is a hash; the columns are its keys, so the count is how many keys a row has.
- Array of arrays (AoA) — each row is a list; the columns are its slots, so the count is how long a row is.
- Hash of arrays (HoA) — the keys are the columns, so the count is the number of keys.
- Hash of hashes (HoH) — each value is a row hash; the columns are that hash's keys, so the count is how many keys a row has.
A plain flat list ([1,2,3]) is treated as a single column.
Edge cases
ncol([])                    # 0
ncol({})                    # 0
ncol({ a=>[], b=>[] })      # 2
Empty frames are 0 columns. Note the last one: a HoA still has its columns even when they hold no rows — the keys are the columns, rows or not.
What it refuses to do
ncol would rather stop than hand back a wrong number:
- Ragged frame — if the rows disagree on how many columns they have (AoH, AoA, or HoH), there is no single column count, so it dies instead of guessing.
- Junk input —
undef, a plain scalar, a SCALAR/CODE/GLOB ref, or a hash whose values aren't all arrays (HoA) or all hashes (HoH) dies with a message saying what it got.
Blessed frames are fine — it looks at the underlying array/hash, so your objects count just like plain refs.
nrow
nrow($frame) returns how many rows a data frame has. It works on all the
Stats::LikeR frame shapes, so you don't have to remember which one you're
holding:
nrow([ [1,2,3], [4,5,6] ])       # 2   array of arrays  (AoA)
nrow([ {a=>1}, {a=>2} ])         # 2   array of hashes  (AoH)
nrow({ a=>[1,2,3], b=>[4,5,6] }) # 3   hash of arrays   (HoA)
nrow({ r1=>{...}, r2=>{...} })   # 2   hash of hashes   (HoH)
NB
A row is one record. Where the records live depends on the shape:
- Array on the outside (AoH, AoA, or a plain list) — each top-level element is a row, so the count is just the array's length.
- Hash of hashes (HoH) — each key is a row, so the count is the number of keys.
- Hash of arrays (HoA) — the keys are columns, not rows; the row count is how long those columns are.
Edge cases
nrow([]) # 0
nrow({}) # 0
Empty frames are 0 rows, whatever the shape.
What it refuses to do
nrow would rather stop than hand back a wrong number:
- Ragged HoA — if the columns have different lengths there is no single row count, so it croaks instead of guessing.
- Junk input —
undef, a plain scalar, or a hash whose values aren't all arrays (HoA) or all hashes (HoH) croaks with a message saying what it got.
Blessed frames are fine — it looks at the underlying array/hash, so your objects count just like plain refs.
oneway_test
A one-way test for equality of group means that, unlike aov/ANOVA, does not
assume equal variances. By default it performs Welch's one-way test (the
same default as R's oneway.test), so the residual degrees of freedom are
usually fractional. Pass var_equal => 1 for the classic equal-variance form.
use Stats::LikeR qw(oneway_test);
Input
oneway_test accepts your data in one of three shapes. In every case each
group is a vector of at least two numeric observations.
| Shape | What it means | Group labels |
|-------|---------------|--------------|
| Hash of arrays { a => [...], b => [...] } | Each key is a group (R's stack() view of a named list) | the hash keys |
| Array of arrays [ [...], [...] ] | Each element is a group | "Index 0", "Index 1", … |
| Hash + formula { resp => [...], grp => [...] }, formula => 'resp ~ grp' | Long-format columns split by a factor column | the distinct values of the factor |
Options
| Option | Default | Meaning |
|--------|---------|---------|
| var_equal | 0 (false) | 0 → Welch's test (unequal variances). 1 → pooled-variance test. The dotted var.equal is refused as an unknown argument. |
| formula | none | 'response ~ factor'. Only valid with a hash input; an error with an array of arrays. |
Data validation
Every observation must be defined and numeric; an undef or non-numeric
cell makes the call die with the offending group and position. This matches
the rest of Stats::LikeR (mean, sum, cor, … all die on undef) and
prevents missing values from being silently treated as 0. All three input
shapes enforce this, formula included:
# dies: "formula: response observation 3 (group 'b') is undefined or non-numeric"
oneway_test({ y => [1, 2, 3, undef, 5, 6], lab => [qw(a a a b b b)] },
formula => 'y ~ lab');
Note that this differs from R, which drops incomplete cases via na.action
rather than complaining. If you want R's behaviour, filter the missing values
out yourself first (see dropna).
Each group needs at least two observations, and you need at least two groups.
Output
A hash reference with three top-level keys:
| Key | Value |
|-----|-------|
| factor name (Group, or the formula's factor, e.g. supp) | the between-groups row: Df, Sum Sq, Mean Sq, F value, Pr(>F) |
| Residuals | the within-groups row: Df, Sum Sq, Mean Sq (Df is fractional under Welch) |
| group_stats | { mean => { group => mean, … }, size => { group => n, … } } |
Examples
Hash of arrays (each key is a group)
my $res = oneway_test({
yield => [5.5, 5.4, 5.8, 4.5, 4.8, 4.2],
ctrl => [1, 1, 1, 0, 0, 0 ],
});
{
Group => {
Df => 1,
"Sum Sq" => 61.6533333333333,
"Mean Sq" => 61.6533333333333,
"F value" => 177.504798464491,
"Pr(>F)" => 1.31343255150313e-07,
},
Residuals => {
Df => 9.81767348326473, # fractional: Welch correction
"Sum Sq" => 3.47333333333333,
"Mean Sq" => 0.353783749200256,
},
group_stats => {
mean => { ctrl => 0.5, yield => 5.03333333333333 },
size => { ctrl => 6, yield => 6 },
},
}
Array of arrays (groups named by index)
my $res = oneway_test([
[5.5, 5.4, 5.8, 4.5, 4.8, 4.2],
[1, 1, 1, 0, 0, 0 ],
]);
Identical to the hash form, except group_stats is keyed by position:
group_stats => {
mean => { "Index 0" => 5.03333333333333, "Index 1" => 0.5 },
size => { "Index 0" => 6, "Index 1" => 6 },
}
Long format with a formula
When your data is in columns rather than pre-split groups, name the response and factor columns with a formula. The factor's values become the groups and the factor's name becomes the top-level key:
my $res = oneway_test(
{
len => [4.2, 11.5, 7.3, 16.5, 17.3, 13.6, 23.6, 18.5, 33.9],
supp => [qw(VC VC VC OJ OJ OJ HI HI HI)],
},
formula => 'len ~ supp',
);
# $res->{supp}, $res->{Residuals}, $res->{'group_stats'} ...
Classic equal-variance form
my $res = oneway_test(\%groups, var_equal => 1); # 'var.equal' is refused
Accuracy
oneway_test is cross-validated against R's stats::oneway.test (both
branches), R's anova(aov()) (the Sum Sq / Mean Sq columns),
statsmodels.stats.oneway.anova_oneway(use_var="unequal") and
scipy.stats.f_oneway. Across 37 data sets — R's chickwts, InsectSprays,
PlantGrowth, iris, ToothGrowth, mtcars, warpbreaks, sleep,
airquality, CO2, esoph, OrchardSprays, faithful and quakes, plus
numerical edge cases — the statistic, both degrees of freedom and the p-value
agree with R to within 1.3e-12 relative error. On 2000 randomised comparisons
against R — both branches, 2 to 8 groups, group sizes 2 to 40, deliberately
heteroscedastic (per-group standard deviations spanning four orders of
magnitude) and data scales spanning 1e-4 to 1e4 — the statistic and the degrees
of freedom agree to 1e-12 and the p-value to 8e-11, the worst of those being
a p-value of 2.4e-66.
Two places where the agreement takes some care:
- Tail p-values.
Pr(>F)is evaluated in the upper tail directly, using the beta symmetry1 - I_x(a, b) = I_{1-x}(b, a), rather than as1 - pf(F, df1, df2). The naive form has no resolution below the ulp of1.0, so it collapses every small p-value to a flat0and loses relative precision from about1e-9downward.faithfulsplit atwaiting > 70gives1.2099104551915e-76(Welch) and5.50783574504386e-103(pooled), matching R'spf(F, df1, df2, lower.tail = FALSE). - Sums of squares. These are accumulated with a two-pass mean-then-deviation
scheme, which is more accurate than R's QR-based
aovon badly scaled data: for two groups near1e8,Residuals/Sum Sqcomes out at exactly10whereanova(aov())reports10.0000000521067.
Degenerate variances
A group with zero variance gives it an infinite Welch weight
(w_i = n_i / 0), and the test degenerates. oneway_test reproduces what R
does rather than papering over it:
| Situation | Welch (default) | var_equal => 1 |
|-----------|-----------------|-------------------|
| One or more groups constant, others not | F, Residuals/Df, Residuals/Mean Sq and Pr(>F) are all NaN; the two Sum Sq entries stay finite | ordinary result (Residuals/Sum Sq is unaffected by the constant group) |
| Every group constant, means differ | NaN | F is Inf, Pr(>F) is 0 |
| Every observation identical | NaN | F and Pr(>F) are NaN (a genuine 0/0) |
# one constant group: Welch has nothing to work with, exactly as in R
my $r = oneway_test({ a => [5, 5, 5, 5], b => [1, 2, 3, 4] });
# $r->{Group}{'F value'}, $r->{Residuals}{Df}, $r->{Group}{'Pr(>F)'} are all NaN
Test for these with $x != $x (the standard NaN idiom) rather than assuming
a finite number came back.
Notes
- The default (Welch) does not require equal group sizes or equal variances;
the pooled form (
var_equal => 1) assumes equal variances. formulais only meaningful for a hash input. Passing it with an array of arrays is an error.- Group order in the output is not guaranteed for hash inputs (it follows hash iteration order); read results by name, not position.
- Avoid naming a factor
Residualsorgroup_statsin a formula, since those are reserved top-level keys in the result.
p_adjust
Corrects a family of p-values for multiple testing, like R's p.adjust. The
methods available are holm (the default), hochberg, hommel,
bonferroni, BH, BY, fdr (a synonym for BH) and none. Method names
are case-insensitive, and the full Benjamini-Hochberg /
Benjamini-Yekutieli spellings are accepted.
my @q = p_adjust(\@pvalues, $method); # array in, array out
my $q = p_adjust($df, $method, columns => ..); # a frame in, a frame out
Given a flat arrayref of p-values it returns the adjusted values as a list, in the order they were given. Given a data frame — AoA, AoH, HoA or HoH — it returns a new frame of the same kind, with the same rows, columns and row labels, holding the adjusted values in the places the raw ones came from. The input frame is never modified.
Every p-value in the frame is corrected as one family, whichever shape it arrived in, so the family size is the number of p-value cells and not the number of rows or columns.
my $df = [ { gene => 'BRCA1', p_value => 0.010 },
{ gene => 'TP53', p_value => 0.040 },
{ gene => 'EGFR', p_value => 0.030 },
{ gene => 'KRAS', p_value => 0.200 } ];
my $q = p_adjust($df, 'BH', columns => 'p_value');
# [ { gene => 'BRCA1', p_value => 0.04 },
# { gene => 'TP53', p_value => 0.0533333 },
# { gene => 'EGFR', p_value => 0.0533333 },
# { gene => 'KRAS', p_value => 0.20 } ]
columns
columns (also spelled column, cols or col) names the columns that hold
p-values; everything else is copied through untouched. It takes one name or an
arrayref of names, which are column names for AoH, HoA and HoH and 0-based
positions for AoA.
p_adjust($aoh, 'BH', columns => 'p_value');
p_adjust($hoh, 'BH', columns => [ 'p_raw', 'p_trend' ]);
p_adjust($aoa, 'BH', columns => 1); # the second column
p_adjust($hoa, columns => 'p_value'); # method defaults to holm
Note the shape each name refers to: in a HoA a column is an outer key, while in a HoH the outer keys are row labels and the names are the inner keys.
Without columns, every cell in the frame is taken to be a p-value. That is
what you want for a frame that is nothing but p-values, and an error for one
with a label column in it — a cell that is neither a number nor undef dies
with a message pointing at columns. A name that matches no column in the
frame also dies, rather than quietly correcting nothing.
columns applies only to frames; passing it with a flat list of p-values is an
error.
Method may be positional or named
The method still reads positionally, as it always has, and may also be given as
a method => ... pair. These three are the same call:
p_adjust($df, 'BH', columns => 'p_value');
p_adjust($df, method => 'BH', columns => 'p_value');
p_adjust($df, 'BH'); # if every column holds p-values
Ordering and other details
- An
undefcell counts toward the family as a p-value of 1, which is how the flat form has always treated it, and comes back adjusted rather than asundef. - Within a frame the family is enumerated in a fixed order — rows in order and then columns by name for an AoA, AoH or HoH; columns by name and then rows for a HoA; row labels in sorted order for a HoH — so tied p-values break the same way on every run instead of following hash iteration order.
- An empty arrayref returns an empty list; an empty frame returns an empty frame of the same kind.
pivot_table
Aggregate a long frame into a wide one, like pandas.pivot_table. Rows are
grouped by an index key, spread across columns generated from a columns
key, and reduced with aggfunc.
pivot_table($df,
index => 'city' | [ 'city', 'q' ], # row key (default: none -> one row)
columns => 'year' | [ 'a', 'b' ], # REQUIRED, generates output columns
values => 'temp' | [ 't', 'h' ], # aggregated (default: all remaining cols)
aggfunc => 'mean' | [ 'sum', ... ] | sub { ... },
skipna => 1, # 0 -> any NA in a bucket poisons a numeric reducer
fill_value => 0, # substitute for NA result cells (default: leave undef)
sort => 1, # 0 -> keep first-seen row/column order
sep => '.', # joins pieces of generated column names
'output_type' => 'aoh', # aoa|aoh|hoa|hoh (default: input family)
);
columns is required. values defaults to every column that is neither
index nor columns. Column identifiers are names for AoH/HoA/HoH and
0-based positions for AoA.
aggfunc accepts the same vocabulary as agg() — mean median sum sd var min max count n nunique first last mode — or a coderef (called as
$code->(\@cells) with every cell in the bucket, including undef), or an
arrayref of any of these. With skipna => 1 (default) undef cells are dropped
before a numeric reduction; skipna => 0 makes a numeric reducer return NA if
its bucket contains any NA.
Rows whose columns-tuple contains NA are skipped (an unnameable column).
With no index, all rows collapse to a single all row.
Generated column names
A single value column reduced by a single function names each output column
after the columns-tuple value alone (flat, pandas-like). Multiple functions
and/or multiple value columns prefix the function and/or value, joined by
sep, in aggfunc-major order (function, then value, then columns-tuple).
A collision between two generated names dies — pass a different sep or
rename inputs.
Example
my $df = [ { city => 'NY', year => 2020, temp => 10 },
{ city => 'NY', year => 2020, temp => 20 },
{ city => 'NY', year => 2021, temp => 30 },
{ city => 'LA', year => 2020, temp => 40 } ];
pivot_table($df, index => 'city', columns => 'year', values => 'temp');
# [ { city => 'LA', 2020 => 40, 2021 => undef },
# { city => 'NY', 2020 => 15, 2021 => 30 } ]
pivot_table($df, index => 'city', columns => 'year', values => 'temp',
aggfunc => [ 'count', 'sum' ]);
# names: count.2020 count.2021 sum.2020 sum.2021
Rows and columns are sorted by default, the same way agg sorts its groups:
each key column numerically when every value in it is numeric, else as strings,
with undef last and NaN after every number; sort => 0 keeps first-seen
order. HoH output labels come from the
index values ('all' with no index) and are uniquified with a numeric
suffix if two joined labels collide. Returns a NEW frame; the input is never
modified.
Errors
Dies on: undefined data; an odd trailing argument list; an unknown argument; a
missing columns; an index/columns/values column that does not exist; an
unknown aggfunc string; an empty aggfunc list; an unknown output_type; or
a generated duplicate column name.
power_t_test
$test_data = power_t_test(
n => 30, delta => 0.5,
sd => 1.0, sig_level => 0.05
);
It also allows configuring the test type (type => 'one.sample', 'two.sample', 'paired') and alternative hypothesis (alternative => 'one.sided'). You can also pass strict => 1 to strictly evaluate both tails of the distribution.
Exactly one of n, delta, sd, power and sig_level must be undef: that
is the quantity solved for. sd and sig_level have defaults, so solving for
either means passing it explicitly as undef; power has no default, so
omitting it entirely is how you ask for the power.
| Parameter | Type | Default | Description |
| :--- | :--- | :--- | :--- |
| n | Float | undef | Number of observations (per group for two-sample, pairs for paired). Must be at least 2. |
| delta | Float | undef | True difference in means. Used as abs(delta) when the test is two-sided. |
| sd | Float | 1.0 | Standard deviation. |
| sig_level | Float | 0.05 | Significance level (Type I error probability), in [0, 1]. R's dotted sig.level is refused as an unknown argument. |
| power | Float | undef | Power of test (1 minus Type II error probability), in [0, 1]. |
| type | String | "two.sample" | Type of t-test: "two.sample", "one.sample", or "paired". |
| alternative | String | "two.sided" | One- or two-sided test: "two.sided", "one.sided", "greater", or "less". |
| strict | Boolean | 0 (False) | Use strict interpretation of two-sided power calculations. |
| tol | Float | 1e-12 | Relative tolerance on the root when solving for n, delta, sd or sig_level. |
The result is a hashref carrying n, delta, sd, sig_level, power,
alternative, method, and -- for two.sample and paired -- note, the
fields R's power.t.test returns, with sig.level spelled sig_level.
Accuracy
The power itself is computed from a noncentral t CDF and agrees with R's
power.t.test and with scipy.stats.nct.sf to about 1e-13 relative.
The four inverse problems are solved by regula falsi with the Illinois
correction, driven to the relative tol above rather than to the width of the
bracket. R solves them with uniroot at a default tolerance of
.Machine$double.eps^0.25 (1.22e-4) measured on the bracket width, which
leaves R's own n, delta, sd and sig.level good to four or five
significant figures; power_t_test matches high-precision
scipy.optimize.brentq roots to about 1e-13 instead. Expect agreement with R
to R's precision, not to this one.
Over 1200 random cases spanning all five solved-for parameters, n from 2 to
5000, delta from 0.01 to 5, sd from 0.05 to 20 and sig_level from 0.001 to
0.2, 1078 of the 1080 that all three implementations answer land within 1e-8
relative of the high-precision scipy value; R lands 379 of them there, and is
past 1e-3 on 56. Neither of the two remaining is a case where R does better:
one solves a sig_level of 5.9e-10 to 1.3e-5 relative (7.7e-15 absolute)
where R returns its bracket endpoint and is 83% out, and the other is 3.4e-8
where R is out by a factor of 300.
The one place R is still ahead is df past about 1e7 -- 500,000 or more
observations per group -- where it holds 1e-14 against this 1e-8. What is
left there is not the noncentral t CDF, which is exact to 3e-16 in that range,
but the critical value: qt_tail inverts incbeta at x = 1 - 5e-8 with
a = 4e7, right at the edge of where its continued fraction converges. That
routine is shared with t_test, cor_test, var_test and the rest, so it is
left alone here rather than retuned for this one caller. The drift is 1.3e-11
at n = 1e6, 1.0e-8 at 4e7 and 1.5e-7 at 1e8.
Errors
Dies on: an odd trailing argument list; an unknown argument; anything other than
exactly one of n, delta, sd, power and sig_level left undef; a
sig_level or power outside [0, 1]; an n below 2 (there is no variance to
estimate below two observations); a negative sd; an unrecognised type or
alternative; solving for sd when delta is 0, or for delta when sd is
not positive; and a target that the requested parameter cannot reach at all --
for instance a power below sig_level / tside, which no sd attains, or one
that would need a sig_level above 1. R answers those last cases with a bracket
endpoint (a sig.level of 1.07, an n of 1.4) or with uniroot's own "no sign
change found"; power_t_test names the range it searched and the target it could
not reach.
pnorm
The normal cumulative distribution function: the probability that a normal random variable is <= x. Ports R's pnorm.
That is, take the integral from negative infinity to the point that you want.
my $p = pnorm(1.96); # 0.9750021 (standard normal, P(X <= 1.96))
x may be a single number or an array reference; an array reference returns an array reference of the same length.
my $ps = pnorm([-1.96, 0, 1.96]); # [0.0249979, 0.5, 0.9750021]
Arguments
| Position | Name | Default | Description |
| --- | --- | --- | --- |
| 1 | x | — | A number, or an array reference of numbers. |
| 2 + | mean | 0 | Mean of the distribution. |
| | sd | 1 | Standard deviation. |
| | lower | 1 (true) | 1 = lower tail P(X <= x); 0 = upper tail P(X > x). 'lower_tail' is an accepted alias; R's dotted 'lower.tail' is refused. |
| | log | 0 (false) | If true, return the log of the probability. 'log_p' is an accepted alias; R's dotted 'log.p' is refused. |
Examples
pnorm(1.96); # lower tail: 0.9750021
pnorm(1.96, lower => 0); # upper tail: 0.0249979
pnorm(1.96, log => 1); # log lower tail: -0.02531565
pnorm(2, mean => 1, sd => 0.5); # standardizes to z = 2: 0.9772499
Use log => 1 for tails that would otherwise underflow to 0:
pnorm(-40); # 0 (underflows)
pnorm(-40, log => 1); # -804.6084
Notes
sd => 0gives a step at the mean:x < meanreturns0, otherwise1.sd < 0returnsNaNand warns.- A
NaNinput (or anundefelement of an array reference) yieldsNaN. +Infreturns1,-Infreturns0.
prcomp
Principal Component Analysis
Options
| Option | Type | Default | Description |
| :--- | :--- | :--- | :--- |
| center | Boolean | 1 (True) | If true, the variables are shifted to be zero-centered before the analysis takes place. |
| scale | Boolean | 0 (False) | If true, the variables are scaled to have unit variance before the analysis takes place. Note: If a column has zero variance, the function will croak to prevent division by zero. |
| retx | Boolean | 1 (True) | If true, the rotated data (the original data multiplied by the rotation matrix) is returned under the key x. |
| tol | Number | undef | A value indicating the magnitude below which components should be omitted. Components are omitted if their standard deviation is less than or equal to tol times the standard deviation of the first component. |
| rank | Integer | undef | Optionally specify a strict limit on the number of principal components to return. The function will return min(rank, rows, columns) components. |
Results
Returned Data Structure
The prcomp function returns a HashRef containing the following keys representing the results of the Principal Component Analysis:
| Key | Type | Description |
| :--- | :--- | :--- |
| sdev | ArrayRef[Number] | The standard deviations of the principal components. Mathematically, these are the square roots of the eigenvalues of the covariance matrix. |
| rotation | ArrayRef[ArrayRef] | A 2D array representing the matrix of variable loadings (the eigenvectors). Each inner array represents a row, and the columns correspond to the principal components. |
| x | ArrayRef[ArrayRef] | A 2D array containing the rotated data (often referred to as PCA scores). This is the original data projected onto the principal components. Note: Only present if the retx option is true. |
| center | ArrayRef[Number] or 0 | The centering values used (typically the column means). Returns false (0) if centering was disabled. |
| scale | ArrayRef[Number] or 0 | The scaling values used (typically the column standard deviations). Returns false (0) if scaling was disabled. |
| varnames | ArrayRef[String] | The sorted names of the original variables. Note: Only present if the input data carried column names, i.e. an Array of Hashes (AoH), a Hash of Arrays (HoA), or a Hash of Hashes (HoH). |
prcomp accepts an Array of Arrays (AoA), an Array of Hashes (AoH), a Hash of
Arrays (HoA), or a Hash of Hashes (HoH). For the named-column shapes the columns
are ordered alphabetically by name, and that order is reported in varnames.
Rows that hold a non-numeric, undefined, non-finite, or absent value in any
column are dropped listwise.
Using array of arrays
my $aoa = [
[2, 4],
[4, 2],
[6, 6]
];
my $pca = prcomp($aoa);
which returns
{
center [
[0] 4,
[1] 4
],
rotation [
[0] [
[0] 0.707106781186547,
[1] 0.707106781186548
],
[1] [
[0] 0.707106781186548,
[1] -0.707106781186547
]
],
scale 0,
sdev [
[0] 2.44948974278318,
[1] 1.4142135623731
],
x [
[0] [
[0] -1.41421356237309,
[1] -1.4142135623731
],
[1] [
[0] -1.4142135623731,
[1] 1.41421356237309
],
[2] [
[0] 2.82842712474619,
[1] 2.22044604925031e-16
]
]
}
Array of Hashes
Each element of the array is one observation, keyed by column name. The columns
are taken from the first row hash and sorted alphabetically, so the following is
the same matrix as the AoA above and returns the same sdev, rotation, and
x — plus varnames => ['A', 'B']:
my $aoh = [
{ B => 4, A => 2 },
{ B => 2, A => 4 },
{ B => 6, A => 6 }
];
my $pca = prcomp($aoh);
Unlike a Hash of Hashes, an AoH preserves row order, so the rows of x line up
with the rows of the input.
Hash of Arrays
my $hoa = { B => [4, 2, 6], A => [2, 4, 6] };
my $pca = prcomp($hoa);
predict
R-style prediction for the fitted objects returned by lm and glm. It rebuilds
each row's linear predictor from the model's coefficients and (for glm) applies
the inverse link.
Usage
my $fit = lm(formula => 'mpg ~ wt + hp', data => $train);
my $yhat = predict($fit, $newdata); # predictions on new rows
my $resp = predict($logit_fit, $newdata); # glm: response scale (default)
my $eta = predict($logit_fit, $newdata, type => 'link'); # linear predictor
my $fitted = predict($fit); # no newdata -> stored fitted_values
$model— a fittedlm/glmhashref.predictreads itscoefficients(and, forglm, itsfamily).$newdata— a HoA, AoH, or HoH of new observations. Omit it (or passundef) to get the model's ownfitted_valuesback.type—'response'(default) returns predictions on the response scale (the inverse link applied — logistic for binomial);'link'returns the linear predictor. Forlmand gaussianglmthe link is the identity, so the two are the same.
A glm fitted with an offset -- offset() in the formula or a named offset
column -- has the offset re-evaluated on each new row and added to the linear
predictor, so a rate model predicts counts at the new rows' exposure. An offset
given as an array ref has nothing to be re-evaluated from, and a model with
absorbed factors has no estimates of their effects to predict with; predict
croaks on either rather than quietly leaving them out. poisson and negbin
fits are put on the response scale with exp.
What it returns
A hashref keyed by row name → prediction, exactly like lm/glm key
fitted_values: a row_names column (or HoH key) if present, otherwise 1-based
integer labels.
my $m = lm(formula => 'y ~ x + I(x^2)', data => $train);
my $p = predict($m, { x => [1, 2, 3] });
# { 1 => ..., 2 => ..., 3 => ... }
How it works
For each new row the prediction is
eta = Intercept + Σ coef[term] · term(row)
where each term is evaluated with the same engine used to fit the model, so
interactions (x:z → product) and transforms (I(x^2) → power) behave
identically to fitting. Coefficients that the fit marked aliased (stored as NaN)
contribute nothing, just as they were excluded from the fitted values. For glm
with family => 'binomial' and type => 'response', eta is passed through the
logistic function 1 / (1 + exp(-eta)); otherwise eta is returned as is.
A consequence worth noting: predicting on the training data reproduces the
model's fitted_values for any model built from continuous terms, interactions,
or I() transforms.
Good to know
- A prediction comes back as NaN when a required term can't be evaluated in the new data (a missing column, or a value that makes the term undefined).
- Factors are a limitation. The fitted object stores only the dummy term
names (e.g.
genderM), not the underlying factor levels, sopredictcannot re-expand a raw categorical column in new data. Either pass pre-expanded 0/1 dummy columns whose names match the coefficient names, or extendlm/glmto retain the factor levels. - It dies on: a model that isn't a hashref or has no
coefficients; an invalidtype; ornewdatathat isn't a HoA/HoH hashref or AoH arrayref.
prop_test
Test of proportions, a faithful port of R's stats::prop.test. It compares an
observed count of successes against a target probability (one sample), tests two
proportions for equality (with a confidence interval for their difference), or
tests k > 2 proportions for equality via a Pearson chi-square. A Yates
continuity correction is applied for one or two groups (toggle with correct).
Validated numerically against R.
# one sample vs a target probability (default 0.5)
my $r = prop_test(83, 100); # 83 successes in 100 trials
printf "p-hat=%.2f 95%% CI %.3f–%.3f p=%.4g\n",
$r->{estimate}[0], $r->{'conf_int'}[0], $r->{'conf_int'}[1], $r->{'p_value'};
# two groups: difference in proportions + CI
my $two = prop_test([83, 90], [100, 100]);
# k > 2 groups: chi-square test of equality (no CI)
my $k = prop_test([83, 90, 75], [100, 100, 100]);
# one-sample against a specified probability, one-sided, no correction
my $g = prop_test(83, 100, p => 0.7, alternative => 'greater', correct => 0);
Pass successes and trials either as matching array references (one entry per group) or as two scalars for a single sample.
Input Parameters
| Parameter | Type | Default | Description | Example |
| --- | --- | --- | --- | --- |
| successes | ArrayRef or Number | None (Required) | Count of successes per group (positional arg 1). | [83, 90], 83 |
| trials | ArrayRef or Number | None (Required) | Count of trials per group (positional arg 2); same length as successes. | [100, 100], 100 |
| p | Number or ArrayRef | 0.5 (one sample) / pooled | Null probability. A single value or one per group; when omitted with ≥2 groups, equality of proportions is tested against the pooled rate. | 0.7, [0.5, 0.6] |
| alternative | String | 'two.sided' | 'two.sided', 'less', or 'greater'. Forced two-sided for k > 2 groups or two groups tested against a given p. | 'greater' |
| conf_level | Number | 0.95 | Confidence level for the interval (one or two groups). | 0.99 |
| correct | Boolean | 1 | Apply the Yates continuity correction (k ≤ 2 only). | 0 |
Output variables
| Variable | Type | Description | Example |
| --- | --- | --- | --- |
| statistic | Double | Pearson chi-square statistic (X-squared). | 1.5414 |
| parameter | Integer | Degrees of freedom. | 1 |
| p_value | Double | The p-value. | 0.2144 |
| estimate | ArrayRef | Sample proportion(s), one per group. | [0.83, 0.90] |
| conf_int | ArrayRef | For one group, a Wilson score interval for the proportion; for two groups, a Wald interval for the difference p1 - p2. Absent for k > 2. | [-0.174, 0.034] |
| alternative | String | The alternative hypothesis used. | 'two.sided' |
| conf_level | Double | The confidence level used. | 0.95 |
| method | String | Human-readable description of the test performed. | '2-sample test for equality of proportions with continuity correction' |
qcut
Equal-frequency binning of a numeric column, which is the analog of pandas
qcut. Equal-width binning slices the value range into intervals of the same
size, which dumps most of a skewed distribution into one bin; qcut instead
chooses cutpoints so each bin holds roughly the same number of observations.
This is the binning you usually want for ranked-list work: deciles, quartiles,
top-5% tranches.
Cutpoints are computed by linear interpolation between order statistics — the
numpy/pandas default, and the same rule quantile uses (R's
Type 7) — so the edges match pandas.qcut exactly. Bins are right-closed,
(a, b], with the lowest bin closed on both ends, [a, b], so the minimum
value is always included.
Signature
qcut($data, $q, %options)
$data— an array reference of numbers, in any order.qcutsorts an internal copy, so your array is left untouched and codes come back in the order the values were given. Every defined value must be numeric: a non-numeric string such as'N/A'is a fatalisn't numericerror rather than a silent zero, so clean orundefsuch cells first (seedropna,fillna). At least two distinct values are needed to form a bin.$q— either a positive integer (the number of equal-frequency bins) or an array reference of probabilities in[0, 1]giving explicit cut boundaries, e.g.[0, 0.5, 0.95, 1]. An explicit vector is sorted for you, and any probability outside[0, 1]is clamped into it rather than being an error.
undef entries are treated as missing (NA): they are skipped when computing
cutpoints and, when codes are requested, come back as undef in their original
positions.
Only the options listed below are read; a misspelled one is ignored rather than
refused, so code => 1 (no s) quietly hands back edges instead of codes.
For a usage reminder at the prompt, call h('qcut'); it prints this section to
STDOUT and returns. Every function is documented that way — see
Getting help.
What it returns
| Options given | Returns |
| --- | --- |
| none | The edge vector, as a flat list of $q + 1 numbers |
| codes => 1 | One array reference: the bin codes, parallel to $data |
| codes => 1, edges => 1 | Two references, ($codes, $edges) |
By default qcut returns the edge vector — the cheap, common query — so call it
in list context:
my @edges = qcut($data, 4); # ($e0, $e1, $e2, $e3, $e4)
In scalar context that flat list collapses to its element count, not to a
reference: my $e = qcut($data, 4) sets $e to 5. Assign to an array.
The per-element bin assignment (the expensive part) is opt-in. Ask for it with
codes => 1 and you get an array reference parallel to $data:
my $codes = qcut($data, 4, codes => 1);
Asking for codes turns the edge vector off, so
my ($codes, $edges) = qcut($data, 4, codes => 1) leaves $edges undefined.
Ask for both explicitly and they are computed in a single pass:
my ($codes, $edges) = qcut($data, 4, codes => 1, edges => 1);
Options
| Option | Meaning |
| --- | --- |
| edges => 1 | Include the edge vector. On by default, but turned off automatically when codes are requested, so pass it explicitly to get both. |
| edges => 0 | Suppress the edge vector. With no codes/labels there would be nothing left to return, which is a fatal error. |
| codes => 1 | Include the 0-based integer bin codes, one per element of $data. |
| labels => [...] | Map the bin codes onto your own labels (implies codes => 1). The list length must equal the number of bins actually produced. |
| labels => 'interval' | Label each element with its interval string, e.g. (3.25, 5.5] (also implies codes). |
| duplicates => 'raise' | Die when tied data makes adjacent cutpoints equal. The default, and what pandas does. |
| duplicates => 'drop' | Merge equal cutpoints into fewer bins instead of dying. |
How many bins, and how full
The bin count is always @$edges - 1, and codes run from 0 to
@$edges - 2. That equals $q (or @$probs - 1) unless
duplicates => 'drop' merged tied cutpoints, in which case it is fewer — which
is why a labels list has to match the bins you actually got, not the ones you
asked for.
Bin sizes are equal only when the data permits: the count has to divide
evenly and no repeated value may straddle a cutpoint. Ties are placed by the
right-closed rule, which is why [1 .. 10] into quartiles gives 3, 2, 2, 3
rather than 2.5 each — the same split pandas makes. Count the codes to see what
you got:
my $codes = qcut($data, 10, codes => 1);
my $sizes = value_counts($codes); # { 0 => n0, 1 => n1, ... }
If a probability vector omits 0 or 1, the end bins still stretch over the
whole range: a value below the first cutpoint lands in bin 0, one above the
last lands in the last bin. pandas returns NA for those, so include 0 and 1
unless the stretching is what you want.
Examples
Quartile edges (the default). The cutpoints match pandas exactly:
my @edges = qcut([1 .. 10], 4);
# @edges = (1, 3.25, 5.5, 7.75, 10)
Bin codes. They are 0-based, and unsorted input is fine — codes come back in input order:
my $codes = qcut([1 .. 10], 4, codes => 1);
# $codes = [0, 0, 0, 1, 1, 2, 2, 3, 3, 3]
my $c2 = qcut([5, 1, 9, 3, 7], 4, codes => 1);
# $c2 = [1, 0, 3, 0, 2]
Edges and codes together, computed in one pass:
my ($codes, $edges) = qcut([1 .. 10], 4, codes => 1, edges => 1);
Equal frequency on clean data — 100 values into 4 bins of 25:
my $codes = qcut([1 .. 100], 4, codes => 1);
# 25 elements in each of bins 0, 1, 2, 3
An explicit probability vector, for an asymmetric top-5% tranche:
my @edges = qcut([1 .. 100], [0, 0.5, 0.95, 1]);
my $codes = qcut([1 .. 100], [0, 0.5, 0.95, 1], codes => 1);
# bin 0: lower half (50), bin 1: next 45%, bin 2: top 5%
Named labels instead of integer codes (implies codes):
my $labels = qcut([1 .. 10], 4, labels => [qw/Q1 Q2 Q3 Q4/]);
# ['Q1','Q1','Q1','Q2','Q2','Q3','Q3','Q4','Q4','Q4']
Interval-string labels:
my $iv = qcut([1 .. 10], 4, labels => 'interval');
# $iv->[0] eq '[1, 3.25]'
# $iv->[-1] eq '(7.75, 10]'
Missing values are ignored for cutpoints, and (when codes are requested) pass straight through:
my $codes = qcut([1, 2, undef, 4, 5, 6, 7, 8, 9, 10], 4, codes => 1);
# $codes->[2] is undef; the rest are binned as usual
Tied data and duplicates. Heavy ties can make adjacent cutpoints equal; the
default raises, 'drop' merges the empty quantile bands:
my @tied = ((0) x 8, 1, 2, 3, 4);
qcut(\@tied, 4); # dies: bin edges are not unique
my @edges = qcut(\@tied, 4, duplicates => 'drop');
# @edges = (0, 1.25, 4) -- 2 bins, not 4, so labels => [qw/a b/] here
Binning a data-frame column, which is the usual reason to want codes.
vals hands qcut the column and assign puts the result
back as a new one:
my $df = { id => [1 .. 10], ldl => [90, 120, 150, 200, 80, 110, 175, 160, 95, 130] };
my $q = qcut(vals($df, 'ldl'), 4, labels => [qw/Q1 Q2 Q3 Q4/]);
assign($df, ldl_quartile => $q);
# $df->{ldl_quartile} = [qw/Q1 Q2 Q3 Q4 Q1 Q2 Q4 Q4 Q1 Q3/]
Get the documentation:
h('qcut'); # prints this section to STDOUT and returns
Errors
qcut dies when $data is not an array reference, when $q is neither a
positive integer nor an array reference, and when the options ask for nothing
(edges => 0 with no codes or labels). It dies with no non-missing values
when every element is undef, and need at least one data value when $data
is empty.
Cutpoints are the other source of failures. bin edges are not unique means
ties collapsed adjacent cutpoints under the default duplicates => 'raise':
either pass duplicates => 'drop' or ask for fewer bins. Even with 'drop',
data holding a single distinct value cannot be binned at all and dies with
too few distinct values to form bins. Finally, a labels arrayref whose
length differs from the bin count dies naming both numbers
(got 2 bins but 4 labels).
Differences from pandas
- Interval printing. pandas nudges its lowest edge 0.1% below the minimum
so every bin can be half-open, e.g.
(0.999, 3.25].qcutkeeps the exact minimum and closes the lowest bin on both ends,[1, 3.25]. Membership is the same; only the printed interval differs. - Out-of-range values. A partial probability vector makes the end bins stretch (above), where pandas yields NA.
- Out-of-range probabilities are clamped into
[0, 1]instead of raising. - Return type. There is no Categorical: you get edges, plain integer codes, your own labels, or interval strings.
See also
quantile computes the same cutpoints without assigning anything
to bins. chunk splits by position instead of value, which works on
non-numeric data. value_counts checks how full the bins came
out, rank is the alternative when you want the whole ordering rather
than bins, and assign / vals move a binned column into
and out of a data frame.
quantile
Calculates sample quantiles using R's continuous Type 7 interpolation.
my $quantile = quantile('x' => [1..99], probs => [0.05, 0.1, 0.25]);
If the probs parameter is omitted, it behaves identically to R by defaulting to the 0, 25, 50, 75, and 100 percentiles (c(0, .25, .5, .75, 1)). The returned hash keys match R's standardized naming convention (e.g., "25%", "33.3%").
A probability that lands a hair outside [0, 1] — the usual result of computing
one rather than writing it down — is clamped to the endpoint rather than
refused, within the same 100 * eps that R allows; anything further out is an
error. undef values in x are dropped.
rank
Rank values like R's rank(). Takes flat scalars and/or array refs (like min), with optional trailing ties_method / na_last options. Returns the list of ranks in input order.
my @r = rank(3, 1, 4, 1, 5); # 3, 1.5, 4, 1.5, 5
my @r = rank([3, 1, 4, 1, 5], 'ties_method' => 'min'); # 3, 1, 4, 1, 5
Ranks are 1-based; average may return half-ranks. undef and NaN are treated as NA.
ties_method
How tied values share ranks (default average):
| value | behavior | rank(3, 1, 4, 1, 5) |
| --------- | ------------------------------ | --------------------- |
| average | mean of the tied ranks | 3, 1.5, 4, 1.5, 5 |
| min | lowest rank in the group | 3, 1, 4, 1, 5 |
| max | highest rank in the group | 3, 2, 4, 2, 5 |
| first | ties keep input order | 3, 1, 4, 2, 5 |
| last | ties keep reverse input order | 3, 2, 4, 1, 5 |
| random | ties broken randomly (srand-aware) | varies |
na_last
How undef/NaN elements are placed (default true):
| value | behavior | rank(5, undef, 1, ...) |
| --------------- | -------------------------- | ------------------------ |
| true | NAs get the highest ranks | 2, 3, 1 |
| false | NAs get the lowest ranks | 3, 1, 2 |
| keep | NAs stay undef, in place | 2, undef, 1 |
| na (or undef) | NAs dropped (shorter list) | 2, 1 |
Ronly
my @only_last = Ronly(\@a, \@b, \@c);
my $count = Ronly(\@a, \@b, \@c);
The mirror of Lonly: takes one or more array references and returns the values
that appear in the last reference and in no other reference; with a
single reference it returns that list's distinct values. Duplicates collapse,
the result keeps the last list's first-appearance order, and scalar context
returns the count. Values are compared by string form (see get_union). A
non-array-ref argument or an undef element is fatal. With exactly two
references this is the right-only set difference, so Ronly(\@a, \@b) equals
Lonly(\@b, \@a); more generally Ronly(@refs) equals Lonly(reverse @refs).
my @a = (1, 2, 3, 4, 5);
my @b = (3, 4, 5, 6, 7);
my @c = (5, 6, 7, 8);
my @r = Ronly(\@a, \@b, \@c); # (8) -- 5,6,7 also appear in @a or @b
rbinom
Create a binomial distribution of numbers
my $binom = rbinom( n => $n, prob => 0.5, size => 9);
read_table
minimal example:
my $test_data = read_table('t/HepatitisCdata.csv');
options
| Option | Description | Example |
| -------- | ------- | ------- |
|comment | Comment marker, by default # (## for a VCF); lines beginning with it are skipped. It may be more than one character | comment => '%' |
|output_type| data type for output: array of hash (the default; hash of hash for a VCF), array of array, hash of array, or hash of hash | 'output_type' => 'aoh'|
|filter| Only take in rows matching a filter; see below for how a key picks its column | filter => { Sex => sub {$_ eq 'f'} }|
|row_names | hoh only: the column whose values key the rows (default: the first column). An error with any other output_type, where the column is read as an ordinary one | 'row_names' => 'id' |
|auto_row_names | read R's default write.table output, where the header is one field short of every data row because R writes no label for the row-names column: the leading field of each row becomes a row-names column. 1 names it row_name, a string names it whatever you pass. Off by default, so a genuinely ragged file is still an error | 'auto_row_names' => 1 |
|sep | field separator: a literal string, or a qr// regex (see below); synonym with delim| sep => "\t", sep => qr/\s+/ |
| delim| field separator: a literal string, or a qr// regex; synonym with sep| delim => "\t" |
| header | 1 (the default): the first line holds the column names. 0, or perl's false '': the first line is data, as R's header = FALSE and pandas' header=None | header => 0 |
| col_names | an array reference of column names. With header => 0 it names the columns, which are otherwise V1, V2, … as in R; with a header it replaces the header's names | 'col_names' => ['id', 'name'] |
| quote | '"' (the default): a double quote starts a quoted field. '': quotes are ordinary text, as R's quote = "" and pandas' quoting=csv.QUOTE_NONE | quote => '' |
| sheet| which worksheet to read from an .xlsx file: a sheet name, or a 1-based index when no sheet has that name (default: first sheet). An error for any other file | sheet => 'Sheet2' |
| na_strings | field texts that mean "missing"; a string or an array reference of strings, mapped to undef. Off by default | 'na_strings' => 'NA' |
| na_values | pandas' spelling of na_strings | na_values => ['NA', 'N/A'] |
| undef_val | write_table's spelling of na_strings, so a round trip can use one name on both halves | 'undef_val' => 'NA' |
| explode | VCF only. 1 (the default): split each sample column into one column per FORMAT key, and return a hoh keyed by CHROM:POS:REF:ALT; 0: the file's own columns. See VCF files | explode => 0 |
| colClasses | R's: store the columns you name as numbers rather than text, which takes about a third of the memory. A hash by column name, a list by position, or one class for every column. See numeric columns | colClasses => { age => 'integer', bmi => 'numeric' } |
output types can be AOH (aoh), AOA (aoa), HOA (hoa), HOH (hoh)
read_table($filename, 'output_type' => 'aoh');
read_table($filename, 'output_type' => 'aoa');
read_table($filename, 'output_type' => 'hoa');
An AoA's first row is the header, then one array per data row, every row in file column order. That is the shape write_table reads an AoA as, so the two round-trip. It is also the only output type that keeps every field when the header repeats a name, so it does not give the "later values win" warning. Nothing labels an AoA's rows, so row_names is an error with it; a row-names column is read as an ordinary column.
read_table('taxa.tsv', 'output_type' => 'aoa');
# [ ['taxid', 'genus', 'species'], ['10090', undef, 'Mus musculus'], ['9606', 'Homo', 'Homo sapiens'] ]
and, like Text::CSV_XS, filters can be applied in order to save RAM on big files:
$test_data = read_table(
't/HepatitisCdata.csv',
filter => {
Sex => sub {$_ eq 'f'} # where "Sex" is the column name, and "$_" is the value for that column
},
'output_type' => 'aoh'
);
A key of filter picks its column this way:
0is the whole row:$_is the array of the row's fields.- A column's name is that column. When the header repeats a name, it is the last column with it, the one whose value the row keeps.
- Any other number is a field, counting from 1, as in Text::CSV_XS. A name
is tried first, so a column called
2021is filtered on asfilter => { 2021 => ... }whatever its position. - Two keys for the same column, such as
1and its name, both run, in the order of their keys sorted as strings. A row is kept only if every filter returns true.
Each filter is also passed the row's fields and a hash of the row by name, as
$_[0] and $_[1], and a change it makes to $_ is written back into the
row. Inside a filter %_ is that same hash.
The filters are called from the parser itself, so a filtered read costs little
more than the filter calls: a 300,000-row, 5-column CSV read as an array of
hashes takes about 0.25 s with one filter and 0.13 s with none. Up to 0.3212
the same filtered read took 0.63 s.
the default delimiter is ,
Suffixes .csv, .tsv and .vcf are automatically detected from file names, but if specified, are overridden by delim and/or sep. sep is given priority. A .vcf also changes the default comment; see VCF files.
A UTF-8 byte-order mark at the start of a text file, which Excel's "CSV UTF-8"
export writes, is dropped rather than read as part of the first column's name,
as pandas' read_csv drops it.
A file is read as bytes and its fields come back as bytes; nothing is decoded.
Text you pass in to be compared with a field — a sep, a comment marker, an
na_strings token, a filter key, row_names or a sheet name — is
compared as UTF-8 bytes when perl holds it as characters, as it does under
use utf8 or for a string you have decoded. So 'na_strings' => '—' under
use utf8 matches an em dash in a UTF-8 file. A qr// separator holding such
characters matches each line as UTF-8 instead, and a line that is not valid
UTF-8 is then an error rather than misread. Lines always end at a newline whatever $/ is
set to, so a local $/; in the calling code does not change what is read.
Lines may end in LF or CRLF, and a file whose lines end in a bare CR, as
classic Mac OS wrote them, is read as R and pandas read it. The start of the
file is read 64 KB at a time, up to 1 MB, until a CR turns up; if no LF has by
then, the file is split on CR. In any other file a lone CR outside quotes is
dropped.
With 'output_type' => 'hoh' a file whose only column is the row name gives
one empty hash per row, as R's read.table gives a data frame of zero columns.
Rows that repeat an earlier row's name overwrite it, later values winning, and
read_table warns once for the file, with how many rows did it and the first
of them.
regular-expression separators
A string sep is always a literal: sep => '\s+' splits on the three
characters backslash, s and plus. Pass a qr// to split on a pattern instead:
my $d = read_table('aligned.txt', sep => qr/\s+/); # whitespace-aligned columns
my $d = read_table('messy.csv', sep => qr/\s*,\s*/); # commas, with blanks around them
my $d = read_table('mixed.txt', sep => qr/[;,]/); # either of two characters
Everything else reads as it does with a literal separator: quoted fields
(a separator inside quotes is text, "" is one quote, a quoted field may run
over lines), comments and commented-out headers, blank lines, a byte-order
mark, CRLF and CR line ends, filter, row_names, auto_row_names, na_strings and
all four output types. Details worth knowing:
qr/\s+/is whitespace-delimited, assep=r"\s+"is in pandas andsep = ""in R'sread.table: leading and trailing whitespace on a line make no field, so indented or right-padded columns read cleanly. This is decided by the pattern text alone, soqr/\s+/xqualifies andqr/[ \t]+/does not.- Any other pattern cuts as
splitdoes: a separator at the start of a line leaves an empty first field, and one at the end an empty last field, just as a literal separator would. - Capture groups in the pattern are not returned as fields, unlike with
split, and the pattern keeps its own flags (qr/x/i) and its own group numbers, so a backreference works:qr/(:)\1/splits on::. - A pattern that can match the empty string, such as
qr/\s*/, is refused, since it would cut between every character. - In a whitespace-delimited file, a comment line with as many words as the data has columns can be taken for a commented-out header, since that is how one is recognised; see commented-out headers below for when it is.
- A pattern under Unicode rules --
/u, whichuse v5.12or later puts on everyqr//, or one using\p{...}-- and one under/areads characters: a line that is valid UTF-8 is matched as UTF-8, soqr/\s+/usplits on a U+00A0 or U+2003 between fields and never inside a character such asà. A line that is not valid UTF-8 is matched as bytes. The fields are the file's bytes either way. A pattern under the default rules is matched as bytes, soqr/\xe2\x80\x94/finds an em dash's three bytes; write\hor\p{...}in such a pattern with/uto have it read characters. Plainqr/\s+/splits on ASCII blanks only, as R'ssep = ""and pandas'sep=r"\s+"do. - An
.xlsxfile ignoressepandquote, whether a string or a pattern. - The separators are found by perl's regex engine, called from the same C
parser a literal separator uses, so a regex read costs little more than a
literal one: on a 300,000 x 5 CSV,
qr/,/takes 0.17 s and','0.14 s. A string is still the faster choice for a fixed separator, and a pattern that has to backtrack, such asqr/\s*,\s*/(0.34 s), costs more.
files with no header, and files with stray quotes (header, col_names, quote)
header => 0 reads the first line as data. The columns are named by
col_names, or else V1, V2, … as R names them, counted from the first row:
my $d = read_table('pairs.csv', header => 0); # V1, V2, ...
my $d = read_table('pairs.csv', header => 0, 'col_names' => ['id', 'score']);
col_names with a header (the default) renames the header's columns instead;
if the two differ in length, read_table warns, as R does, and uses
col_names. With header => 0, a line starting with the comment marker is
always a comment, even #text with no space after the marker, as in R; with a
header, such a line can be a commented-out header, as described below.
quote => '' turns quoting off: a " is kept as ordinary text wherever it
appears. By default a " anywhere in a field opens a quoted field that runs to
the next ", possibly many lines later, so a file whose quotes are not CSV
quoting -- a name such as 'Beach rock 4+5"' -- would have every line up to the
next " read into one cell.
read_table cannot tell a stray " from CSV quoting by looking at the bytes,
and neither can R or pandas. It does say when the file looks like it has one,
and names the line where the quote opened:
- If the file ends inside a quoted field,
read_tablewarns and keeps what it read, as R'sscan()does. pandas raises an error here instead. - If a
"in the middle of a field, such as5'10", opens a quoted field that runs past the end of its line,read_tablewarns, once per file. R reads such a field the same way; pandas keeps a"in the middle of a field as text. - An
Alignment erroron a row that a quoted field ran across lines in says so. quote => ''warns when every field on the first line is wrapped in", as R'swrite.csv()writes them, because those quote marks would then stay in every name.
A quoted cell that starts at the beginning of its field and holds a line break is ordinary CSV, and is read without a warning.
Formats that never quote, such as NCBI's taxonomy dumps, want both options:
# NCBI fullnamelineage.dmp: "id\t|\tname\t|\tlineage\t|", no header
my $lineage = read_table('fullnamelineage.dmp',
sep => qr/\t\|\t?/, header => 0, quote => '',
'col_names' => [qw(tax_id tax_name lineage end)], # 'end' is the empty field after the last "\t|"
'output_type' => 'hoa');
On that 3,015,956-line, 900 MB file this takes 2.6 s. A literal
sep => "\t|\t" takes 1.6 s, but leaves each line's closing "\t|" on the
lineage.
compressed files (gzip, bzip2)
A gzip- or bzip2-compressed file is read as the text inside it; there is no option to set:
my $d = read_table('cohort.tsv.gz'); # tab-separated, from the .tsv
my $v = read_table('variants.tsv.bgz'); # bgzip / BGZF
my $b = read_table('export.csv.bz2');
- The bytes decide, not the name, as with R's
read.table: a compressed file without a.gzsuffix is still read, and a plain file named.gzis still text. The name does still pick the defaultsep, from the part before.gz,.bgzor.bz2, sox.tsv.gzis tab-separated. - It is streamed, inflated 64 KB at a time as the rows are read, so a large compressed file takes no more memory than the plain one would.
- Every member is read. bgzip (every
.vcf.gz),pbzip2, R'sgzfile(, "a")andcat a.gz b.gzall write files of several compressed members, and all of them come back whole. - Damage is an error, not a short read: a truncated file, a bad checksum, or anything but NUL padding after the last member dies naming the file.
- Both need only core modules (
Compress::Raw::ZlibandCompress::Raw::Bzip2). xz, LZMA, zstd and lzop files are recognised by their first bytes, as R recognises them, and refused with a message that names the format, rather than read as text..zipis not read either (an.xlsx, which is a zip archive, is). write_tablewrites.gzand.bz2files that read back through this.
VCF files
A file named .vcf, .vcf.gz or .vcf.bgz, in any case, is read as a VCF
with no options. Each sample's column is split ("exploded") into one column per
FORMAT key, and the records come back as a hash of hashes keyed by
CHROM:POS:REF:ALT:
my $variants = read_table('calls.vcf.gz');
# { '20:14370:G:A' => {
# CHROM => '20', POS => '14370', ID => 'rs6054257', REF => 'G', ALT => 'A',
# QUAL => '29.1', FILTER => '.', INFO => 'NS=3;DP=14;AF=0.5;HOMSEQ;DB',
# 'NA00001.GT' => '0|0', 'NA00001.GQ' => '48', 'NA00001.DP' => '1',
# 'NA00001.HQ' => '25,30', 'NA00001.CNL' => '10,20',
# 'NA00002.GT' => '1|0', ... },
# '20:17330:T:A' => { ..., 'NA00001.CNL' => undef, ... }, # no CNL in this record's FORMAT
# ... }
- Defaults.
sepis a tab andcommentis##, so the##meta-information lines are skipped and the#CHROM POS ID ...line is the header. The#comes off#CHROM, so the first column isCHROM. - The columns. The eight fixed columns come first, then
<sample>.<key>for every sample and every key.FORMATcan differ from record to record (GATK writesGT:AD:DP:GQ:PLon most andGT:AD:DP:GQ:PGT:PID:PLon phased ones), so the keys are those of every record read, in the order each first appears. A key missing from a record'sFORMATisundef, and so is a value a sample leaves off the end, which the VCF spec allows (./.underGT:AD:DPisGTalone).FORMATand the unsplit sample columns are not returned. A sample with more values than itsFORMAThas keys is an error. - Values are text.
0/1,34,7and73,0,1043are returned as written:AD,PLandINFOare not split further, and.is not missing unless you pass'na_strings' => '.', which then applies to the split values as well as to whole fields. - The key.
CHROM:POS:REF:ALTidentifies a record in practice;IDis usually.. A key that repeats is warned about once, later records winning, as with any hoh.'row_names' => 'POS', or any other column including an exploded one, keys the hash by that column instead. - Other shapes.
'output_type'still gives an aoa, aoh or hoa of the same columns. An aoa is the one to hand towrite_table. filterruns before the split, while the file is read, so it sees the file's own columns:FORMATand each sample's text whole (filter => { FORMAT => sub { /PGT/ } }), notNA00001.GT. The columns are the keys of the records it kept.col_namesrenames the file's columns before the split, so a renamed sample names its exploded columns.explode => 0returns the file's own columns instead, an aoh by default, withFORMATand the samples unsplit.header => 0reads the file that way too, having noFORMATcolumn to split by, and its#CHROMline is the first data row,#and all.explodeis refused for a file not named as a VCF.
Passing sep or comment overrides the VCF default, and comment => '#'
reads the same table. Under any other name, such as .tsv or .txt, the file
is not a VCF to read_table: with comment => '##' the meta lines are still
skipped, but the first column is #CHROM and nothing is split.
The split is done in C. On a 3,499,678-record single-sample GATK .vcf.gz,
the exploded hoh takes 11.7 s, against 9.1 s for the file's own columns as a
hoh, and an exploded aoa 8.4 s, against 7.0 s for the plain one.
numeric columns (colClasses)
Every field is read as text unless you say otherwise. On a 64-bit perl a
short number held as text costs about 70 bytes, and held as a number about
24. colClasses takes R's
spelling and R's meaning: name the columns that are numbers, and they are
stored as numbers as the file is read.
my $d = read_table('cohort.csv', colClasses => { age => 'integer', bmi => 'numeric' });
my $d = read_table('cohort.csv', colClasses => [ 'character', 'integer', 'numeric' ]);
my $d = read_table('counts.tsv', colClasses => 'integer');
| class | stored as | accepts |
| --- | --- | --- |
| numeric (also double, real) | a floating-point number | a decimal number with an optional sign and exponent, or Inf, Infinity or NaN in any case, with blanks either side allowed |
| integer | an integer | an optional sign and digits, a leading blank allowed and nothing after them, within perl's integer range |
| character, or undef | the text | anything (the default) |
- A hash names columns; one the file does not have is warned about, as R
warns about it, and otherwise ignored. A list goes by position and is
recycled when it is short, as R recycles it; a single class applies to every
column. In a hoh the row-name column counts, and a declared one keys each row
by its number, so
004becomes the row named4. - An empty field and an
na_stringstoken areundefin any column.NAis missing only whenna_stringsnames it. - A field that is not a number of the kind declared is an error naming the
column, the data row and the text, rather than a silent
0orundef. - A
filterstill sees each field's text; the rows it keeps are converted. - Where it differs from R: an integer may be anything that fits perl's integer
(64 bits on most perls), where R's stops at 2147483647; a hexadecimal
number such as
0x1Ais refused, where R reads it; and an exponent must have digits, where R reads1eas1.
On a 300,000-row CSV with three of its five columns declared, the table took 74 MB instead of 116 MB, and the read 0.095 s instead of 0.086 s.
missing values (na_strings / na_values / undef_val)
An empty field is always read as undef. Any other text that a file uses to
mean "missing" — NA, N/A, NULL, -, -999 — has to be named. It is one
option under three names, so you can spell it whichever way the rest of your
code already does:
| spelling | whose | use it when |
| --- | --- | --- |
| na_strings | R's read.table | porting R, or with no reason to prefer another |
| na_values | pandas' read_csv | porting Python |
| undef_val | this module's write_table | reading back a file this module wrote |
All three take a string or an array reference of strings, all three mean
exactly the same thing, and passing more than one is an error, exactly as sep
and delim together are:
my $d = read_table('cohort.csv', 'na_strings' => 'NA');
my $d = read_table('cohort.csv', na_values => ['NA', 'N/A', 'NULL', '-']);
my $d = read_table('cohort.csv', 'undef_val' => 'NA');
This matters because the tokens are otherwise ordinary strings, and Perl
numifies a string to 0: an unnamed NA in a numeric column does not stop
mean or sd, it silently drags the answer toward zero (with a warning, which
is fatal under warnings FATAL => 'all' and easy to miss otherwise). It also
gives write_table's undef_val an inverse, so a file this
module wrote can be read back with its missing cells intact — which is what the
third spelling is for, letting both halves of the round trip name the token the
same way:
write_table($rows, 'out.csv', 'undef_val' => 'NA');
my $back = read_table('out.csv', 'undef_val' => 'NA'); # undef again
Note that write_table's undef_val is one token, being what it writes, while
read_table's accepts a list, being every token it should recognise.
Details worth knowing:
- Off by default. R's
read.tabledefaults tona.strings = "NA"and pandas recognises a whole list, butread_tablerecognises nothing beyond the empty field unless you ask, so a literalNAstays a string in code that predates this option. - Your list replaces the set, it does not extend one — R's behaviour.
'na_strings' => 'baz'mapsbazand leavesNAandNaNalone. pandas would map all three. - The match is on the exact field text, case-sensitively and with no
whitespace stripped, which is also R's rule:
' NA'is not'NA', and'-999.000'is not'-999.0'(pandas numifies and would match both). List every spelling a file actually uses. - The header is never mapped, so a column may legitimately be named
NA. - A
filterruns after the mapping, so it seesundefrather than the token; select the present rows withsub { defined $_ }. - It applies to
.xlsxreads too, and to all threeoutput_typeshapes. Forhoh, a mapped row-name cell is a missing row name and is refused the same way an empty one is.
commented-out headers
A header that is itself commented out is detected and used automatically, so
# PDB score
1a2b 10
3c4d 20
reads as though the header were PDB, score (the comment marker and any
following whitespace are stripped from the first column). A commented first
line is only taken as the header when its field count matches the line after
it, and that line looks like data: a number or an na_strings token in one of
its fields, or nothing but empty fields. So
# written by foo, v2
id,val
1,2
reads with the header id, val, as R and pandas read it: the comment is as
wide as the header, but id,val has no number in it, so it is the header and
the comment is a comment. The rule cannot tell a commented-out header over rows
with no numbers in them from a comment, and reads the first of those rows as
the header.
When several comment lines come before the header, it is the last of them, the one next to the data, that is tried as the header, and the rest are comments:
#written by foo
#id,val
1,2
reads with the header id, val. If the last one fails the test above, the
line after the comments is the header, so R's own
#comment
#another
C1 C2 C3
"Panel" "Area Examined" "# Blemishes"
reads with the header C1, C2, C3, as read.table(header = TRUE) reads it.
Only lines before the header are looked at this way: a line starting with the
comment marker after the header, if the marker hugs its text (#3,4), is a
data row, while one with a blank after the marker (# note) is a comment
wherever it is.
A marker inside quotes is text, as R's read.table reads it: a header written
"#a",b has the columns #a and b, and a quoted "#x" or "# x" is a
field like any other, never a comment. write_table quotes a first field that
starts with # for this reason, so that it reads back as written.
You may name a commented-out header's column in a filter either
as it appears in the file or by its clean name:
read_table('ranks.tabular.tsv', filter => { '# PDB' => sub { $_ == 2 } });
Excel (.xlsx) files
A file whose name ends in .xlsx — or .xlsm, .xltx or .xltm, the
macro-enabled and template workbooks, which hold their sheets the same way —
is read directly, with no extra
dependencies — the core IO::Uncompress::Unzip module pulls the parts out of
the (zipped) workbook and the worksheet XML is parsed in XS, through the same
fast path a delimited file takes: read_table reads the header in Perl and the
rows are assembled in C. All output_type, filter, and row_names options
work exactly as they do for text files:
my $data = read_table('samples.xlsx');
my $data = read_table('samples.xlsx', sheet => 'Results'); # by name
my $data = read_table('samples.xlsx', sheet => 2); # 1-based index
A sheet is looked up as a name first and as a number only when no sheet has
that name. So in a workbook whose sheets are 2024 and 2023,
sheet => 2023 is the sheet named 2023, and sheet => 2 is the second.
Multiple worksheets. If the workbook has more than one worksheet and no
sheet is given, read_table returns a hashref keyed by worksheet name,
each value being that sheet parsed just as a single table would be (honouring
output_type, filter, etc.):
my $book = read_table('report.xlsx'); # { Sheet1 => [...], Sheet2 => [...] }
my $rows = $book->{Results};
A workbook with a single worksheet, or a call that names a sheet explicitly,
returns that one table directly (not wrapped in a hash). A worksheet with no
name is keyed SheetN, N its position, or the next number no other sheet is
named with, so it never replaces a sheet that really has that name.
The XML is read as an XML parser would read it: comments are skipped (a
commented-out row is not data), a CDATA section is its literal text, and a
line end written as CR LF or a lone CR is LF, while one written as
stays a CR. Rich-text runs are concatenated into a single value, and the
phonetic guide (<rPh>, the furigana Japanese Excel records for text typed
through the input method) is left out of it, as openpyxl leaves it out. The
shared-string table is found through the workbook's relationships, so it is
read whatever the writer named it. Excel's own escape for a character XML
cannot hold, _x and four hex digits and _ (_x0000_ for NUL, _x005F_
for a literal underscore), is decoded in string cells as Excel and LibreOffice
decode it, so a control character that write_table wrote reads back as
itself; a formula's cached result is left as written.
Limitations: dates and times are returned as their raw Excel serial numbers
(cell number formats are not applied); a cell that has formatting but no value is a
blank, whether it is written <c s="2"/>, <c s="2"></c> or with an empty
<v></v>, and blanks past a row's last value do not add columns (readxl and
pandas leave them out too); and two things the format does not allow are
read as if they were not there — a cell reference past XFD, the last of the
16,384 columns a worksheet has, places the cell in the next column instead, and
a numeric character reference to something XML does not allow as a character
— � and the other control characters but tab, LF and CR, a UTF-16
surrogate, , , or anything past  — is left in
the text rather than decoded. The sep, delim, and comment options do not
apply to .xlsx files, so a cell such as #id is read as it is. A workbook
whose elements carry a namespace prefix (<x:row>, as the Open XML SDK writes
them) is read like any other. Tested in t/read_table.xlsx.t,
t/read_table.xlsx.parser.t and t/read_table.xlsx.xml.t.
rename_cols
rename_cols($df, old => new, ...)
rename_cols($df, { old => new, ... })
Rename one or more columns of a data frame. Works on the labelled shapes
(AoH, HoA, HoH); an AoA has no column names and dies (convert to
AoH/HoA first). Identifiers are the inner-row keys for AoH/HoH and the
top-level keys for HoA.
Behaviour depends on calling context:
- Non-void (scalar or list context) returns a fresh shallow view and
never mutates the source. Row shapes (
AoH/HoH) share the cell scalars by reference via XS; aHoAaliases the whole column arrayrefs under their new keys. - Void context renames the source in place and returns nothing: the
edit lands in each
AoH/HoHrow hash, or on the top-level keys of aHoA.
# HoH: rename an inner-row key in every row, in place
rename_cols(\%d, resolution => 'Resolution (Å)');
# capture a fresh view instead; %d is left untouched by rename_cols itself
%d = %{ rename_cols(\%d, resolution => 'Resolution (Å)') };
# pairs or a single hashref; both forms are equivalent
my $view = rename_cols($aoh, a => 'x', c => 'z');
my $view = rename_cols($hoa, { b => 'B' });
Both the in-place and view paths are swap-safe (gather-then-set), so an exchange renames correctly:
rename_cols($sw, a => 'b', b => 'a'); # {a=>1,b=>2} -> {b=>1,a=>2}
Ragged AoH/HoH frames stay ragged: an old key that is absent from a given
row is simply skipped for that row. For a HoA, the renamed key points at the
same column arrayref (no copy), so a later push/splice on it is shared
with the source.
Dies (all validation runs before any mutation, so a dying void call leaves the source unchanged):
- an old column that is not present anywhere in the frame,
- a new name that is
undef, - a rename whose target collides with a kept column or another renamed target,
- an odd-length
old => newargument list, - an
AoA(no column names to rename).
Note: \%d = rename_cols(...) is not valid Perl — a reference constructor
is not an lvalue before 5.22 refaliasing, which is out under the module's 5.10
back-compatibility. Use the void form or the %d = %{ ... } capture idiom
above.
_rename_inplace
_rename_inplace($df, $shape, \%map)
Private helper (not exported) that backs rename_cols's void-context path;
rename_cols performs all argument checking first, so this never has to croak.
For a HoA it renames the top-level column keys; for AoH/HoH it renames
the keys inside each row hash. It gathers the moved values before re-storing
them, which makes it swap-safe, and it only touches keys that actually exists
in a given row, which preserves ragged frames. Mutates $df and returns
nothing.
rnorm
Make a normal distribution of numbers, with pre-set mean mean, standard deviation sd, and number n.
my ($rmean, $sd, $n) = (10, 2, 9999);
my $normals = rnorm( n => $n, mean => $rmean, sd => $sd);
roc
Build a ROC curve from predicted scores and 0/1 labels: the AUC (c-statistic) with a DeLong confidence interval, the sensitivity/specificity at every threshold, and the best cut-off by Youden's J. The standard way to judge how well a score separates cases from non-cases.
use Stats::LikeR 'roc';
my $r = roc(\@scores, \@labels);
print $r->{auc}; # 0.848
print "@{ $r->{'auc_ci'} }"; # 0.649 1.000
my $cut = $r->{youden}; # best operating point
print "$cut->{threshold}: sens=$cut->{sensitivity} spec=$cut->{specificity}";
Options: positive (positive-class label, default 1), direction ('>'
default, or '<'), conf_level (default 0.95). Result keys: auc, auc_se,
auc_ci, n_pos, n_neg, youden, and curve (one point per threshold). For
just the number, use auc.
rownames
Return the row names of a data frame, as a list (like R's rownames).
Only HoH carries genuine row labels; the other shapes are positional and
so yield 0-based indices, again matching view:
AoA/AoH—0 .. $#$df(one index per top-level element)HoA—0 .. longest_column-1HoH— the string-sorted outer keys (the row labels)
In scalar context it returns the count, so scalar rownames($df) equals
nrow($df) for a rectangular frame.
my $hoh = { r2 => { x => 1 }, r1 => { x => 2 }, r3 => { x => 3 } };
my @rows = rownames($hoh); # ('r1', 'r2', 'r3') -- sorted labels
my $aoh = [ { a => 1 }, { a => 2 } ];
my @rows = rownames($aoh); # (0, 1)
my $hoa = { a => [1,2,3], b => [4,5,6] };
my @rows = rownames($hoa); # (0, 1, 2)
my $n = rownames($hoh); # 3 (scalar context == nrow)
notes
Shape is detected with the same _df_shape classifier agg uses, so both
functions accept exactly the frames agg/view accept. A ragged frame is
tolerated for enumeration: colnames spans the widest row and rownames
the longest column. An empty frame returns an empty list. Because the
classifier is ref-based (not reftype), pass an unblessed frame — blessed
frames are the one case ncol/nrow accept that this family does not.
runif
Make an approximately uniform distribution into an array
named arguments
my $unif = runif( n => $n, min => 0, max => 1);
where n is the number of items, the values are between min and max
positional args
this is to match R's behavior:
runif( 9 )
will make 9 numbers in [0,1]
runif(9, 0, 99)
will match n, min, and max respectively
sample
take a sample of hash or array slices.
my $h = sample(\%h, 4); # take 4 hash keys and their values into $h
or, alternatively, with arrays:
my $arr = sample(\@arr, 3); # take 3 indices of an array
The sample is drawn without replacement, so n may not exceed the number of
elements or keys there are to draw from; asking for more is an error, as it is
in R (cannot take a sample larger than the population when 'replace = FALSE'):
sample([1, 2, 3], 10); # dies: cannot take a sample of 10 from a population of 3
Through 0.314 the two shapes disagreed about this and neither said so — a hash
quietly returned fewer keys than were asked for, and an array padded the result
out to n with undef, so sample([1,2,3], 10) came back as three values and
seven undefs that no caller could tell apart from real data.
scale
my @scaled_results = scale(1..5);
You can also pass options, either as a trailing hash reference or as trailing name/value pairs — the two are equivalent:
my @scaled_results = scale(1..5, { center => 0, scale => 1 });
my @scaled_results = scale(1..5, center => 0, scale => 1);
center and scale each take a number to use instead of the mean or the
standard deviation, or one of mean/sd, true/false, none, 1/0 and
the empty string, matched case-insensitively. With center => 0 the divisor
is R's: the root mean square about zero, sqrt(sum(x^2)/(n-1)), not the
standard deviation.
It fully supports matrix operations. By passing an array of arrays, scale processes the data column by column independently:
my $scaled_mat = scale([[1, 2], [3, 4], [5, 6]]);
sd
my $stdev = sd(2,4,4,4,5,5,7,9);
Correct answer is 2.1380899352994
sd can accept both array references as well as arrays:
my $stdev = sd([2,4,4,4,5,5,7,9]);
sd will croak/die if any undefined values are provided.
select_cols
Return a new data frame containing only the named columns, in the order
requested — the Stats::LikeR form of pandas df[['a','b']]. Works on all
four frame shapes. For AoA the identifiers are 0-based integer positions;
for AoH, HoA, and HoH they are column names. Columns may be given as a
list or as a single arrayref.
my $aoh = [ { a => 1, b => 2, c => 3 },
{ a => 4, b => 5, c => 6 } ];
my $sub = select_cols($aoh, 'a', 'c');
# [ { a => 1, c => 3 }, { a => 4, c => 6 } ]
my $hoa = { a => [1,4], b => [2,5], c => [3,6] };
my $sub = select_cols($hoa, ['c', 'a']); # order preserved
# { c => [3,6], a => [1,4] }
my $aoa = [ [1,2,3], [4,5,6] ];
my $sub = select_cols($aoa, 0, 2);
# [ [1,3], [4,6] ]
A column that appears in only some AoH/HoH rows is filled with undef in
the rows that lack it, so the selection comes back rectangular:
select_cols([ {a=>1,b=>2}, {a=>3,c=>9} ], 'a', 'c');
# [ { a => 1, c => undef }, { a => 3, c => 9 } ]
seq
Works as closely as I can to R's seq, which is very similar to Perl's for
loops. Returns an array, not an array reference.
Specifically it mirrors base::seq.default, which is what R's seq()
dispatches to, and not the seq.int() primitive: the two do not agree, and
the disagreements are visible from Perl. Takes from, to, and an optional
by.
Standard integer sequence
say 'seq(1, 5):';
my @seq = seq(1, 5);
say join(', ', @seq), "\n";
say 'seq(1, 2, 0.25):';
@seq = seq(1, 2, 0.25);
Fractional steps
say 'seq(1, 2, 0.25):';
@seq = seq(1, 2, 0.25);
say join(", ", @seq), "\n";
for (my $idx = 2; $idx >= 1; $idx -= 0.25) { # count down to pop
is_approx(pop @seq, $idx, "seq item $idx with fractional step");
}
Negative steps
say 'seq(10, 5, -1):';
@seq = seq(10, 5, -1);
say join(", ", @seq), "\n";
for (my $idx = 5; $idx <= 10; $idx++) { # count down to pop
is_approx(pop @seq, $idx, "seq item $idx with negative step");
}
Leaving by out
Without a by, seq is R's from:to: unit steps in whichever direction to
lies. So seq(5, 1) is 5 4 3 2 1, the same as R. Only an explicit by
whose sign disagrees with the direction of travel is an error.
from:to is also a different function from by = 1, with a looser fuzz
factor, which is worth knowing before you supply a by you think is
redundant:
scalar @{[ seq(1, 4.9999999) ]}; # 5 -- 1 2 3 4 5
scalar @{[ seq(1, 4.9999999, 1) ]}; # 4 -- 1 2 3 4
R does the same thing, for the same reason: 1:4.9999999 adds
1 + FLT_EPSILON before truncating, and seq(1, 4.9999999, by = 1) adds
1e-10.
How many values you get
Nothing accumulates: element i is from + i * by, and the count is
int((to - from)/by + 1e-10) + 1. Both formulae are R's. The 1e-10 is
why seq(0, 1, 0.1) has eleven values and not ten — (1 - 0)/0.1 is not
quite 10 in binary floating point. The last value is then pinned to to
if the fuzz carried it past, which R added in 2.9.0, so
(seq(0, 1, 0.00025 + 5e-16))[-1]; # exactly 1, not 1 + 2e-12
When one value comes back instead of many
Three cases collapse to a single value rather than raising an error, all following R:
byis0andfrom == to, which returnsfrom;to - fromis0andtois0, which returnstowhateverbyis;fromandtoare indistinguishable at the working precision — that is,abs(to - from) / max(abs(to), abs(from))is below100 * DBL_EPSILON. This is whyseq(1e15, 1e15 + 20, 2)is the single value1e15and not eleven values: at that magnitude adoublecannot tell1e15from1e15 + 20well enough for the step to mean anything. Widen the gap and the sequence comes back —seq(1e15, 1e15 + 200, 2)is 101 values.
Errors
All five messages are R's own wording:
fromortoisNaNor infinite —seq: 'from' must be a finite number, or the same for'to'.byhas the wrong sign for the direction of travel —seq: wrong sign in 'by' argument.byis0withfrom != to, orbyisNaN—seq: invalid '(to - from)/by'.- the sequence would have more than
INT_MAXvalues —seq: 'by' argument is much too small. from:towould span more thanINT_MAX—seq: result would be too long a vector.
The fourth of these used to be silent: up to 0.314 a count that overflowed
size_t returned the empty list, so seq(0, 1e30, 1) and seq(0, 1, 1e-11)
both handed back nothing at all, and seq(NaN, 5) died inside perl with
panic: stack_grow() negative count. seq(5, 1) croaked
wrong sign in 'by' argument in that release too.
Integers come back as integers
When every value in the sequence is an exact integer no larger than 2**53,
seq returns Perl integers (IVs) rather than floats — which is also what R
returns for the same call, an integer vector. The numbers are identical
either way, but the representation is much cheaper to use: stringifying the
result never goes through Gconvert, so on this machine
join ',', seq(1, 1_000_000);
dropped from 409 ns per element to 83, and building the list itself from 16.3
to 12.7, putting seq level with perl's own 1 .. 1_000_000. A sequence
with a fractional step stays floating point, as it must.
One consequence is cosmetic: a large integral value now prints in full rather
than in exponent form, so seq(1e15, 1e15 + 200, 2) starts
1000000000000000 where it used to start 1e+15.
Context
seq is a list function and the array is the point of it, but the other two
contexts are cheap rather than wasteful: in void context it builds nothing,
and in scalar context it builds only the value the caller can see, which is
the last one — what perl gives for any list-returning sub. So
seq(1, 10_000_000); # costs nothing
my $last = seq(1, 10); # 10, without ten million SVs behind it
There is no length.out and no one-argument form; seq(17) is an error
rather than R's 1:17.
shapiro_test
tests to see if an array reference is normally distributed, returns a p-value and a statistic
my $shapiro = shapiro_test(
[1..5]
);
and returns the hash reference:
{
p_value 0.96717393596804,
statistic 0.986762155447719,
W 0.986762155447719
}
matching R's shapiro.test(1:5) to the last digit it prints. Values that are
undef or NaN are dropped first, exactly as R's complete.cases() drops
them, and the remaining sample must hold between 3 and 5000 values.
skew
Sample skewness — the direction and degree of a distribution's asymmetry. Positive means a long right tail (the usual shape of lab values, costs and lengths of stay), negative a long left tail, and about zero a symmetric sample. Validated numerically against R.
skew(2, 4, 4, 4, 5, 5, 7, 9); # 0.8184875533568
Below, three samples standardized to mean 0 and standard deviation 1, each
against the same N(0, 1) curve in grey: a log-normal sample mirrored into a
long left tail, a normal sample, and the log-normal itself. The sign of skew
is which side of the median the mean has ended up on — the long tail pulls the
mean towards itself and leaves the median behind, which is why a skewed lab
value is usually better summarized by its median than by its mean.
Arguments work as they do for sd and var: plain numbers, array references, or any mixture of the two, all flattened into one sample.
my @x = (2, 4, 4, 4, 5, 5, 7, 9);
skew(@x); # a list
skew(\@x); # an array reference
skew([2, 4, 4], 4, [5, 5, 7, 9]); # mixed; same sample
skew(x => \@x); # named, if you prefer it
type
There are three conventions in circulation for turning the moment ratio into a
sample statistic, and they disagree noticeably on small samples. type picks
one; the default is 2.
| type | Statistic | Also known as |
|--------|-----------|---------------|
| 1 | g1 | the plain moment ratio; R's moments::skewness |
| 2 | G1 | the default; SAS, SPSS, Stata, Excel's SKEW(), scipy.stats.skew(bias => FALSE) |
| 3 | b1 | e1071::skewness's own default |
where, writing m2 and m3 for the second and third central moments (each
divided by n):
g1 = m3 / m2**1.5 # type 1
G1 = g1 * sqrt(n * (n - 1)) / (n - 2) # type 2, the default
b1 = g1 * ((n - 1) / n)**1.5 # type 3
my @x = (1, 2, 4);
skew(\@x, type => 1); # 0.3818017742 plain moment ratio
skew(\@x); # 0.9352195296 G1, the default
skew(\@x, type => 3); # 0.2078265621 b1
type => 2 is the estimator that is unbiased for a normal sample, which is why
it is the default and why it is what every general-purpose statistics package
reports. It divides by n - 2, so it needs at least three values; the other two
need at least two.
Both statistics are computed in one pass over the sample, so a whole column can be summarized without materializing it twice:
my $df = read_table('labs.tsv');
printf "%-24s skew %7.3f kurtosis %7.3f\n", $_,
skew($df->{$_}), kurtosis($df->{$_}) for qw(alt ast bilirubin);
Errors
skew croaks, naming the offending position, on an undefined value:
skew(1, undef, 3);
# skew: undefined value at argument index 1
skew([1, 2, undef]);
# skew: undefined value at array ref index 2 (argument 0)
and on a sample too small for the chosen type, on a type outside 1 .. 3, or
on a constant sample, which has no shape to report:
skew([7, 7, 7, 7]);
# skew: zero variance (all 4 values are equal), so skewness is undefined
See also
kurtosis for the fourth moment, sd and var for the second, shapiro_test to test normality rather than describe the departure from it.
smd
Standardized mean difference between two continuous groups, standardizing by the
simple (unweighted) average of the group variances — the convention used for
covariate-balance diagnostics in "Table 1" (R's tableone / stddiff). Returns
the signed value. Validated numerically against R.
my $balance = smd(\@exposed_age, \@unexposed_age); # |smd| < 0.1 is well balanced
Unlike cohen_d (which pools by sample size), smd weights the two
group variances equally, so the two diverge when the groups differ in size.
sum
returns sum, but using both arrays and array references.
my $test_data = [1..8];
sum($test_data)
which I prefer, compared to List::Util's required casting into an array:
sum(@{ $test_data });
which passing a reference is shorter and much easier to read. Stats::LikeR, however, will work for both
sum will cause the script to die if any undefined values are provided
Compared with List::Util
min, max and sum pass List::Util's own tests for the same names
(t/min.max.sum.ListUtil.t carries them) except where the two differ on
purpose:
| | List::Util | Stats::LikeR |
|---|---|---|
| an array reference | a number (its address) | its elements, read as data |
| a blessed array reference that overloads 0+ | one number | still its elements, read as data |
| no arguments | undef | dies: sum needs >= 1 element (and likewise for min and max) |
| a string that is not a number, such as 'abc' | 0 | dies, naming the argument |
| NaN anywhere | depends on where it is: min(NaN, 1, 2) is NaN but min(1, 2, NaN) is 1 | NaN, wherever it is, as in R |
| the result | an IV while every value fits one, so sum(1<<60, 1) is exact | an NV, so on a double perl sum(1<<60, 1) == 1<<60, as R's sum gives too |
| a Math::BigInt | a Math::BigInt | the NV its 0+ overload gives |
Anything else that is a number is taken as one: an object that overloads 0+
(when it is not a blessed array reference), a tied scalar, $#array, or a
substr() lvalue. Each is fetched once. The same rules hold for mean,
median, sd, var, mode, uniq, scale, skew and kurtosis.
summary
Analogous to R's summary: a five-number-plus-mean description (# values, Min., 1st Qu., Median, Mean, 3rd Qu., Max.) of the data as entered (it does not summarise fitted-model objects). It produces one statistics row per numeric variable and renders the table exactly like view — the same colourised, wide-character-aware, terminal-fitting output — through the same internal renderer, so all of view's display options apply.
Which variable becomes a row depends on the shape (every shape view accepts is accepted here):
| input | one row per… | label column |
|---|---|---|
| flat vector — summary(@x), summary(\@x), or a bare list | the whole vector | (none) |
| array of arrays (AoA) | inner array | Index |
| hash of arrays (HoA) | key | Key |
| array of hashes (AoH) / hash of hashes (HoH) | column, gathered across rows | Column |
The AoH/HoH case is the per-column summary R gives for a data frame — so the array-of-hashes that read_table returns by default summarises column-by-column:
summary(read_table('data.csv')); # one row per column
summary(\%hoh, nrows => 20); # cap the rows shown
summary(\@x, color => 1); # force colour (default: auto on a TTY)
my $txt = summary(\%hoa, return_only => 1); # capture instead of printing
Non-numeric and undefined cells are ignored: they never count toward # values, and a variable with no numeric values shows 0 and na. For example, summary of an AoH:
# summary: 2 rows x 7 cols (showing 2)
Column # values Min. 1st Qu. Median Mean 3rd Qu. Max.
x 3 1 1.5 2 2 2.5 3
y 3 10 15 20 20 25 30
summary prints the table (unless return_only is set) and returns it as a string. nrows (synonyms nrow, n, rows) caps the rows shown, and the view display options na, color, colors, max_width, ellipsis, gap, width, to, and return_only all apply.
survfit
The Kaplan–Meier survival curve: the probability of surviving past each time,
estimated from right-censored data. The starting point of most survival
analysis; matches R's survival::survfit.
Give times and an event flag (1 = event, 0 = censored); add group for one
curve per group:
use Stats::LikeR 'survfit';
my $f = survfit(\@time, \@status, group => \@arm);
my $s = $f->{strata}{treatment}; # keyed by group label ('' if no group)
print $s->{median}; # median survival time
print "@{ $s->{surv} }"; # S(t) at each time
Option conf_level (default 0.95). Each stratum has arrays time, n_risk,
n_event, n_censor, surv, std_err, lower, upper, plus median, n,
and events. Compare curves with logrank_test; model
covariate effects with coxph.
svyglm
Design-based regression for survey data, survey::svyglm() on a
survey::svydesign(): point estimates weighted by the sampling weights, and
standard errors by Taylor linearization that respect the strata and the
clustering into primary sampling units (PSUs). Putting the sampling weights
into glm's weights gives the same point estimates but standard
errors that are wrong for a complex sample.
use Stats::LikeR 'svyglm';
my $s = svyglm(formula => 'api00 ~ ell + meals + mobility', data => \%apistrat,
weights => 'pw', strata => 'stype');
my $c = svyglm(formula => 'sch.wide ~ ell', data => \%apiclus1, family => 'quasibinomial',
weights => 'pw', cluster => 'dnum', fpc => 'fpc');
| Option | Default | Description |
| --- | --- | --- |
| formula | (required) | Formula as for glm, with offset() terms allowed. |
| data | (required) | HoA, AoH or HoH. |
| family | 'gaussian' | 'gaussian', 'binomial', 'quasibinomial', 'poisson' or 'quasipoisson'. The quasi names give the same fit, as in survey. |
| weights | 1 | Sampling weights (svydesign(weights = )): a column name or an array ref. |
| strata | none | Stratum of each row. |
| cluster | one PSU per row | The PSU of each row (svydesign(ids = )); also accepted as ids, id or psu. |
| fpc | none | Finite population correction: the population size of the stratum, or the sampling fraction (a value at most 1), as svydesign(fpc = ) reads it. |
| nest | 0 | svydesign(nest = TRUE): PSU labels are only unique within a stratum. |
| offset | none | A column, an expression or an array ref. |
| conf_level | 0.95 | Level of conf_int. |
The result holds coefficients, summary (per term Estimate, Std. Error,
t value, Pr(>|t|)), vcov, conf_int, terms, fitted_values,
deviance, dispersion (summary.svyglm's), df_residual, degf (the
design degrees of freedom, PSUs minus strata, which the t tests use), rank,
nobs, n_psu, n_strata, converged and iter. Only single-stage designs
are implemented (the first stage's PSUs and strata, as survey uses by
default). Validated against survey's own tests on the api data.
table_one
The stratified descriptive "Table 1" that opens most clinical papers: for each
variable, a per-group summary — mean (sd) for numbers, n (percent) for
categories — plus a group-comparison p-value.
use Stats::LikeR 'table_one';
my $t1 = table_one(\@cohort, by => 'arm');
print view($t1); # returns a plain AoH you can view() or write_table()
Types are detected automatically (all-numeric = continuous, else categorical)
and the test follows: t-test / ANOVA for continuous (Wilcoxon / Kruskal with
nonparametric => 1), chi-squared for categorical. Options: by, vars
(which columns), types (override a column's type), nonparametric, digits,
pct_digits. Each returned row has variable, level, one column per group,
Overall, and — on a variable's row — p_value and test.
t_test
There are 1-sample and 2-sample t-tests, from one or two arrays:
my $t_test = t_test( $array1, mu => 0.2334 );
or 2-sample:
$t_test = t_test(
$array1, $array2,
paired => 1
);
returns a hash reference, which looks like:
conf_int => [
-0.06672889, 0.25672889
],
df => 5,
estimate => 0.095,
p_value => 0.19143688433660,
statistic => 1.50996688705414
the two groups compared can be specified, though not necessarily, as x and y, just like in R:
$t_test = t_test(
'x' => $array1, 'y' => $array2,
paired => 1
);
What the test is asking
Every t-test is the same three numbers. estimate is what the data say — a
mean, or a difference of means. mu is what the null hypothesis says. The
standard error is how far apart those two would ordinarily drift by chance
alone, and statistic is the distance from mu to estimate measured in
standard errors:
statistic = (estimate - mu) / SE
df says which t distribution that statistic would follow if the null were
true, and p_value is the area of that distribution further out than the
statistic — the chance of landing this far from mu, or further, when mu is
right. Below, R's sleep data as a paired test: ten patients, each measured on
two drugs, so the ten paired differences are one sample and mu = 0 is "the two
drugs are the same". The middle panel is the whole p-value; the right panel is
one of its two tails, magnified until it can be seen.
Parameters
| Parameter | Type | Default | Description |
| :--- | :--- | :--- | :--- |
| x | Array Reference | Required | The first vector of data. Must have at least 2 non-missing elements, except in a var_equal test, where either x or y may have 1. |
| y | Array Reference | undef | The second vector of data. Required for two-sample or paired tests. An explicit undef means "absent", as R's y = NULL does; anything else that is not an array reference is a fatal error rather than a silently ignored argument. |
| mu | Float | 0.0 | The true value of the mean (or difference in means) for the null hypothesis. Shifts statistic and p_value; conf_int is centred on the estimate and does not move. |
| paired | Boolean | FALSE | If true, performs a paired t-test. x and y must be the same length. |
| var_equal | Boolean | FALSE | If true, assumes equal variances (standard two-sample). If false, performs Welch's t-test with unequal variances. The dotted var.equal is refused as an unknown argument. |
| conf_level | Float | 0.95 | Confidence level for the returned confidence interval, from 0 to 1 inclusive, as in R: 1 gives (-Inf, Inf) and 0 a point at the estimate (or an infinite point for a one-sided test). The dotted conf.level is refused as an unknown argument. See Extreme conf_level for the precision limit past about 0.9999. |
| alternative | String | "two.sided" | Direction of the alternative hypothesis: "two.sided", "less", or "greater". "two-sided" and "two_sided" are accepted as scipy's spelling of the same thing. Anything else is a fatal error — an unrecognised value must not quietly become a two-sided test. |
conf_int
conf_int is the estimate plus and minus a multiple of the same standard error
the statistic divides by, and conf_level picks the multiple — the t quantile
at that level and df. Nothing else goes into it. On the left below, the whole
interval taken apart: for the paired sleep test, 2.26216 * 0.38896 = 0.87989
either side of -1.58. On the right, the same interval at six confidence
levels. A wider conf_level needs a bigger quantile and so gives a wider
interval, and the level at which the interval first reaches mu is exactly
1 - p_value — the second panel from the bottom, whose upper bound lands on
zero.
alternative
alternative decides which part of the null distribution counts against the
null, and therefore both p_value and conf_int. "two.sided" counts both
tails beyond |statistic|, "less" counts only what lies below the statistic,
and "greater" only what lies above; the two one-sided p-values always add to
1, and each is half the two-sided one when it is the smaller. The interval
follows: a one-sided alternative gives a one-sided interval, with the other
bound infinite. The example is t_test($drug1, $drug2) on sleep — the same
twenty numbers as above, but unpaired.
mu, p_value and conf_int say one thing
conf_int is the set of mu the test would not reject. Sweep mu across the
line and re-run the test at each value: the p-value peaks at 1 where mu equals
the estimate, and falls through 1 - conf_level at precisely the two bounds of
conf_int. That is what "the interval excludes zero" and "p is below 0.05" both
mean — they are one statement, not two pieces of evidence.
Which is also why mu never moves conf_int. Changing mu changes which
hypothesis is being tested, so statistic and p_value move with it; the
interval is built around the estimate and stays where it is.
What a falling p-value looks like
The same thing seen from the data's side: two samples drawn from two different
distributions, pulled steadily apart. Each column below is one t_test of the
sleep groups with drug 1 shifted — the top panel is the two distributions, by
this module's own density, and the bottom panel is the conf_int
that comes back. The columns are four p-values five orders of magnitude apart.
Only one thing about the interval changes: where it sits. df stays at
17.7765 and its width stays at 3.5710 down the whole row, because shifting a
sample changes neither the spread nor n, and those are all the standard error
is made of. What moves is the distance from mu — and the second column is the
hinge: at p_value = 0.05 the interval's upper bound is 0.0000, sitting
exactly on mu, because "p below 0.05" and "the 95% interval clear of mu" are
the same event.
Reading the two together is the point. p_value reports the distance from mu
in standard errors and nothing else, so it says how surely the difference is not
zero, never how big it is; conf_int reports the difference itself, in hours of
sleep. The other route to a small p is a smaller standard error — more
observations, or less spread — and that one drives p_value down by narrowing
the interval around an estimate that has not moved at all.
paired and var_equal
The same twenty numbers give three different answers depending on what is
assumed about them. paired => 1 says the two vectors are two measurements of
the same ten subjects and tests the ten differences, which removes the
subject-to-subject variation and here turns p = 0.079 into p = 0.0028.
Unpaired, var_equal => 1 pools the two variances into one and spends
n(x) + n(y) - 2 degrees of freedom; the default Welch test does not pool, and
buys that safety with a fractional df from the Welch–Satterthwaite equation.
Welch's df is at most n(x) + n(y) - 2, reaching it only when the two spreads
match, and falls toward n - 1 of whichever sample dominates the standard error
as they separate. The middle and right panels sweep t.test(1:10, 7:20) — the
other example in R's ?t.test — scaling the spread of y about its own mean:
var_equal keeps claiming 22 degrees of freedom throughout, and pays for the
claim with a p-value that is wrong by three orders of magnitude at the left-hand
edge.
Extreme conf_level
conf_int is exact to the last few digits at ordinary confidence levels, and the
t quantile behind it neither saturates nor loses accuracy as the data's scale
grows. Past about conf_level => 0.9999, though, the interval's accuracy is
capped by the argument, not by the quantile — and no implementation can do
better, R's included.
The reason is that conf_level arrives as a float, so the tail has to be
recovered as (1 - conf_level) / 2, and that subtraction discards most of the
tail it is trying to express. The nearest double to 0.99999999 puts the tail at
5.0000000251e-9 rather than 5e-9 — a relative error of 5.0e-9 — and for
0.9999999999 the error is 8.3e-8. Since qt(p, 1) ~ 1/(pi * p), the
quantile, and therefore each interval bound, inherits that relative error
exactly.
One consequence worth knowing: the answer depends on your perl's nvtype. A
long double build (perl -V:nvtype) represents 0.99999999 to 19 digits and
so recovers the tail correctly, while an ordinary double build cannot:
# t_test([1, 3], conf_level => 0.99999999), upper bound minus the mean
# nvtype double 63661976.9168721 (5.0e-9 low)
# nvtype long double 63661977.2367910 (5.2e-13 low)
# qt(5e-9, 1, lower.tail = FALSE) in R = 63661977.2367581
If you need a tail that small exactly, compute it yourself and work from the
quantile rather than passing a conf_level that cannot hold it.
Missing values
undef and NaN are dropped, as R's t.test drops NA; infinities are kept,
as R keeps them. A one-sample or unpaired two-sample test filters each vector on
its own, so the two may lose different numbers of observations and df reflects
what survived. A paired test filters on complete cases: if either side of a pair
is missing the pair goes whole, keeping the differences aligned.
Errors
Dies if:
xis missing or is not an array reference, oryis defined but is not onealternativeis not one of the values aboveconf_levelis below 0, above 1, orNaNmuorconf_levelisundefor a reference (R's "must be a single number"), ormuisNaN; an object that overloads numification is a numberpairedis set without ay, or with anxandyof different lengths- fewer than 2 observations survive: 2 in
xfor a one-sample test, 2 complete pairs whenpaired, and for two samples R's own thresholds — a Welch test needs 2 on each side, whilevar_equalaccepts a side of 1 (it contributes no sum of squares to the pooled variance) so long as the two together reach 3 - the data are essentially constant, meaning the standard error has fallen below
10 * DBL_EPSILONtimes the magnitude of the estimate. The comparison is relative, so a sample whose spread a double cannot resolve at its own scale is rejected instead of being reported as an enormousstatistic. R returnsNaNrather than raising for the exactly-zero case; this raises for both.
Return Hash
| Key | Description |
| :--- | :--- |
| statistic | The computed t-statistic. |
| df | Degrees of freedom for the test. |
| p_value | The calculated p-value based on the test directionality. |
| conf_int | An Array Reference containing two elements: [lower_bound, upper_bound]. |
| estimate | The estimated mean of x (one-sample) OR the mean of the differences (paired). |
| estimate_x | The estimated mean of the x vector (only returned in two-sample tests). |
| estimate_y | The estimated mean of the y vector (only returned in two-sample tests). |
| stderr | The standard error statistic divides by, as R has returned it since 3.6.0. |
Accuracy
The variance is R's: a mean, a correction by the mean of the residuals, then
the squared deviations about it. Two things go beyond R. The deviations are
also summed and their square taken back out (the Chan–Golub–LeVeque
correction), and that same sum is carried into statistic as the part of the
mean no double can hold. That keeps statistic accurate on a sample whose
spread is a few dozen ulps of its mean, where R's is out in the third digit.
The data are also scaled by a power of two before squaring, so a sample whose
squares pass DBL_MAX still gets a finite variance and Welch df, where R's
Welch df is NaN. On ordinary data the two agree to about 1e-13.
Tied arrays, tied elements and tied scalars holding the array reference are
all read through their FETCH, once each.
Validated against R 4.6.1's stats::t.test and against scipy.stats, by
t/t_test.R.scipy.t and t/t_test.tails.R.t. The R cases are every t.test()
call in R's own sources: the examples of ?t.test, ?sleep, ?ks.test,
?array2DF and ?pairwise.t.test, R-intro, the tcltk demo, and
reg-tests-1a.R, reg-tests-1e.R and reg-tests-2.R. Each is checked against
R's pinned .Rout.save output and crossed over every alternative,
var_equal, mu and conf_level. The far tails are checked against
d-p-q-r-tst-2.R's pt() cases. The SciPy cases come from TestTTest_1samp,
TestTTestIndMore, TestTTestRel and TestTTestCI.
The figures above are drawn by t.test.plots.pl in the repository, from the
two examples in R's ?t.test: the sleep data (t = -1.8608, df = 17.776,
p-value = 0.07939 unpaired, t = -4.0621, df = 9, p-value = 0.002833
paired) and t.test(1:10, y = c(7:20)). Every number annotated on them comes
back out of t_test itself, so a figure cannot drift away from the module. It
is an author-only script — it is not installed, and it needs
Matplotlib::Simple, python3 and matplotlib — so re-run it only when a
figure needs to change.
transpose
Transposes a two-dimensional data structure, swapping rows and columns. Accepts either an array of arrays or a hash of hashes. Returns a new reference of the same type; the input is never modified.
Array of array input
Takes a reference to an array of array references and returns a new AoA where output[j][i] = input[i][j].
my $matrix = [[1, 2, 3], [4, 5, 6]];
my $t = transpose($matrix);
# [[1, 4],
# [2, 5],
# [3, 6]]
All rows must be the same length; a ragged input is a fatal error.
undef is valid as an element value and is preserved exactly. An empty outer array or an array of empty rows both return [].
Dies if:
- any inner element is not an array reference
- rows differ in length (ragged array)
Hash of hash input
Takes a reference to a hash of hash references and returns a new HoH where output{col}{row} = input{row}{col}.
my $table = { alice => { score => 97, grade => 'A' }, bob => { score => 84, grade => 'B' } };
my $t = transpose($table);
# { score => { alice => 97, bob => 84 },
# grade => { alice => 'A', bob => 'B' } }
Inner keys do not need to be uniform across rows. If a given column key appears in only some rows, the output hash for that column will simply contain only those rows — no padding or undef-filling is performed.
my $sparse = {
a => { x => 1, y => 2 },
b => { x => 3, z => 4 } };
my $t = transpose($sparse);
# { x => { a => 1, b => 3 },
# y => { a => 2 },
# z => { b => 4 } }
An empty outer hash or an outer hash whose inner hashes are all empty both return {}.
Dies if any inner element is not a hash reference
uniq
Returns the distinct values of its arguments, in first-seen order.
use Stats::LikeR;
my @u = uniq(1, 2, 2, 3, 1); # (1, 2, 3)
my @s = uniq(qw/a b a c/); # ('a', 'b', 'c')
my @f = uniq(1, [2, 2, 3], [3, 4]); # (1, 2, 3, 4)
my $n = uniq(1, 2, 2, 3, 1); # 3
uniq accepts a flat list of scalars, array references, or any mix of the
two. Array references are expanded one level — their elements are treated
as additional arguments, but nested array references are not recursed into and
are compared as opaque values.
Values are compared by stringification, the same eq semantics used by
List::Util::uniq: 1, 1.0, and "1" all collapse to a single result, and
the first value seen is the one returned (as a fresh copy, never an alias to
the input). Order of first appearance is preserved.
This is where uniq parts company with R's unique() and pandas'
pd.unique(), which compare doubles by value. On a build whose NV is a double,
0.1 + 0.2 and 0.3 are two different doubles that both print 0.3, so they
are one value here and two there; 1000000000000000 and 1e15 are the same
number, printed 1000000000000000 and 1e+15, so they are two values here and
one there. Which pairs fall which way moves with the width of the NV, because
the printing does — uniq follows eq on every build.
Compare doubles by value — with a %.17g sprintf, or by rounding — before
calling uniq if that is what you need.
In list context uniq returns the distinct values. In scalar context it
returns the count of distinct values, matching List::Util::uniq. Scalar
context is the cheaper of the two: it never builds the result list.
The UTF-8 flag is part of the comparison key, so a UTF-8 string and a
byte-identical non-UTF-8 string are kept distinct — they are different strings.
Strings that are logically equal and consistently encoded collapse as expected:
a UTF-8 string whose every character is below \x{100} is compared against the
bytes it downgrades to, so "\x{e9}" and "\xe9" are one value, exactly as
eq and a Perl hash key both have it.
The input is left alone. uniq renders a plain number into its own buffer
rather than asking Perl for the number's string, so it does not leave a cached
PV on the caller's SVs — taking the distinct values of a large numeric column
no longer grows that column. Tied arrays and tied elements are read through
their FETCH.
Unlike List::Util::uniq, which passes a single undef through, uniq
croaks on any undefined value, reporting the offending argument index (and
the array-ref index, when the undef came from inside a reference):
uniq(1, undef, 3); # croaks: undefined value at argument index 1
uniq([1, undef, 3]); # croaks: undefined value at array ref index 1 (argument 0)
This matches the undef-handling of mean and the other functions in Stats::LikeR.
vals
Extract a single column from a data frame as a flat array reference, similar to pandas' to_list
my $ages = vals($df, 'age');
vals accepts all three data-frame shapes and always returns a new arrayref of that column's values:
- AoH (array of hashes) -- one value per row, in row order.
- HoA (hash of arrays) -- the named column array, copied.
- HoH (hash of hashes) -- one value per row, in ascending key order (a HoH has no inherent row order, so keys are sorted as strings).
Arguments
| Position | Name | Description |
| --- | --- | --- |
| 1 | $df | An AoH (arrayref), or a HoA/HoH (hashref). The shape is auto-detected by peeking the first hash value: a hashref value means HoH, otherwise HoA. |
| 2 | $col | The column name (must be defined). |
Behavior and notes
- The result is a copy. Every value is duplicated, so mutating the returned array never touches
$df, andundefslots are ordinary writable scalars. - A missing cell is
undef. For AoH and HoH, a row that lacks the column yieldsundeffor that row, as long as at least one row has it. A row that isn't a hashref dies, naming the row. - An absent column dies, in every shape. When no row of an AoH or HoH has the column, or a HoA has no such key,
valsdies withvals: no column named "Method"(andavalswithavals: no column named "Method") instead of returning a column ofundefs, which almost always meant a misspelt name. A column that exists but holds onlyundefis not absent, and neither is a HoA column whose value is not an arrayref, which dies with its own message. - Empty frames return
[]-- an empty AoH or an empty hash both give a clean empty arrayref. - UTF-8 column names and HoH keys are handled correctly (lookups use the key SV; HoH keys sort by Perl string order).
Examples
my $aoh = read_table('patients.csv'); # array of hashes
my $age = vals($aoh, 'Age'); # [ 34, 51, ... ]
my $hoa = read_table('patients.csv', 'output_type' => 'hoa');
my $sex = vals($hoa, 'Sex'); # copy of the Sex column
my $hoh = read_table('patients.csv', 'output_type' => 'hoh');
my $age2 = vals($hoh, 'Age'); # values in sorted row-key order
# feed straight into the numeric routines
my $m = mean( vals($aoh, 'Age') );
value_counts
Count the values in a given data set, return a hash reference showing how many times each particular value is present.
Scalar
$hash = value_counts('c');
returns { c => 1 }
Array reference
value_counts(['a','b','b']);
returns { a => 1, b => 2}
Array
my $value_counts = value_counts('a','b','b');
like an array reference above, returns { a => 1, b => 2}
Array of hashes
my @records = (
{ name => 'Alice', dept => 'Sales' },
{ name => 'Bob', dept => 'Eng' },
{ name => 'Carol', dept => 'Sales' },
);
my $vc = value_counts(\@records, 'dept');
with a key, the value at that key is counted in each hash, so the above returns { Sales => 2, Eng => 1 }. A record that lacks the key is skipped. Passing an array of hashes without a key, or with an element that is not a hash reference, is a fatal error.
Array of arrays
my @rows = (['a', 1], ['b', 1], ['a', 2]);
my $vc = value_counts(\@rows, 0);
when the elements are array references, the key is treated as a numeric column index, so the above returns { a => 2, b => 1 }. A non-numeric index against array-reference elements is a fatal error.
Hash
my $value_counts = value_counts( { A => 'a', B => 'a', C => 'b' } );
returns { a => 2, b => 1}
Hash of array
my $value_counts = value_counts({ 'a' => ['j', 't', 't'], 'b' => ['j', 't', 'v']});
without a key (like above), the occurences of j, t, and v are counted.
With a key, like a for above, only values within that hash key are counted:
my $vc = value_counts({ 'a' => ['j', 't', 't'], 'b' => ['j', 't', 'v']}, 'a');
Hash of hash (table)
$hash = value_counts( {
A => {
a => 'x',
b => 'z'
},
B => {
a => 'x'
},
C => {
a => 'y'
}
}, 'a');
the column, or second hash key, that you wish to count, is specified at the command line
The two new subsections (Array of hashes, Array of arrays) are the only additions; everything else is unchanged. They're placed after the array-container forms to keep array inputs grouped, mirroring how Hash of array / Hash of hash sit together.
var
as simple as possible:
var(2, 4, 5, 8, 9)
var will die if any undefined values are provided
like min, max, etc., var can accept array references, to make code simpler:
my $ref = \@arr;
var($ref) = var(@arr)
var_test
As described by R: Performs an F test to compare the variances of two samples from normal populations
use Stats::LikeR;
my @x = (2.9, 3.0, 2.5, 2.6, 3.2);
my @y = (3.8, 2.7, 4.0, 2.4);
my $vt = var_test(\@x, \@y);
also, conf_level can be set:
$vt = var_test(\@x, \@y, conf_level => 0.99);
as well as a ratio (from R: the hypothesized ratio of the population variances of x and y:
$test_data = var_test(\@xk, \@yk, ratio => 2);
view
An R-style head for the structures read_table returns. Prints the first
few rows of a dataframe as an aligned text table, with numeric columns
right-justified, string columns left-justified, and undefined cells shown as
NA.
| Input type | Perl structure | What view shows |
|------------|--------------------|--------------------------------------------|
| aoa | array of array refs| values gathered column-wise by row index |
| aoh | array of hash refs | one line per row, sequential row numbers |
| hoa | hash of array refs | values gathered column-wise by row index |
| hoh | hash of hash refs | top-level keys become the row label column |
Synopsis
my $aoh = read_table('all.data.tsv', 'output_type' => 'aoh');
view($aoh); # first 6 rows, like head()
view($aoh, n => 20); # first 20 rows
view($aoh, cols => [qw(id age tt)]); # force a column order
view($aoh, 'row_names' => 'id'); # use column 'id' as the row label
view($aoh, na => '.', max_width => 30);
my $txt = view($aoh, return_only => 1); # capture the string, print nothing
view($aoh, to => \*STDERR); # print somewhere other than STDOUT
Output
# AoH: 7 rows x 3 cols (showing 6)
row_name Testosterone, total (nmol/L) age sex
p1 18.2 41 M
p2 NA 7 F
p3 1.05 33 F
p4 22.9 55 M
p5 14 29 M
p6 NA 62 F
# ... 1 more row
The banner reports the structure type, full dimensions, and how many rows are displayed. A footer appears only when rows are hidden.
Arguments
All arguments after the data reference are optional name/value pairs.
| Argument | Default | Meaning |
|-----------------|---------|-------------------------------------------------------------------------|
| n | 6 | Number of rows to show. n greater than the table shows everything. |
| rows | 6 | Number of rows to show. n greater than the table shows everything (synonymous with n)|
| cols / columns | — | Array ref pinning column order (and which columns appear). |
| row_names | — | Column to use as the row label (for aoh/hoa). See ordering note. |
| na | 'NA' | Token printed for undefined cells |
| max_width | 80 | Truncate any cell wider than this (column names are never truncated) |
| ellipsis | '...' | Marker appended to truncated cells |
| gap | 2 | Spaces between columns |
| to | STDOUT | Filehandle to print to. |
| return_only | 0 | If true, return the string and print nothing |
view always returns the formatted string, whether or not it also prints.
A note on column order
read_table stores rows as hashes, so the original CSV column order is not
preserved. view therefore sorts columns by name for a stable, reproducible
layout. Two conveniences soften this:
- A column literally named
row_name(the labelread_tableassigns to a leading blank header) is detected automatically and moved to the left as the row label. - Pass
cols => [ ... ]to control both the order and the selection of columns shown.
When no label column is present, view numbers the rows 1, 2, 3, …, the way
R prints row names for an unnamed data frame.
Edge cases
- Empty input (
[]or{}) prints a clean0 rows x 0 colsbanner. - Tabs, carriage returns, and newlines inside a cell are escaped (
\t,\r,\n) so one record always stays on one line. - A non-reference argument, or a hash whose values are plain scalars, dies with a clear message rather than producing garbled output.
Tests
The behavior above is covered by view.t (run with prove view.t): the three
structure types, n boundaries, alignment, NA rendering, truncation,
row_names/cols handling, control-character escaping, the return_only and
to output paths, empty structures, and the error cases.
vif
Variance inflation factors, the standard multicollinearity diagnostic for a
regression model. For each predictor, vif regresses it on all the other
predictors and reports 1 / (1 - R²); values above ~5–10 flag problematic
collinearity. The second argument is either a formula string (its right-hand-side
terms are used) or an array reference of predictor column names. Validated
numerically against R. Numeric predictors only — categorical predictors would
need a generalized VIF.
my $v = vif(\%data, [qw(age bmi sbp chol)]); # or 'y ~ age + bmi + sbp + chol'
for my $p (sort { $v->{$b} <=> $v->{$a} } keys %$v) {
printf "%-6s VIF = %.2f\n", $p, $v->{$p};
}
Returns a hash of predictor => VIF.
wilcox_test
$test_data = wilcox_test(
[1.83, 0.50, 1.62, 2.48, 1.68, 1.88, 1.55, 3.06, 1.30],
[0.878, 0.647, 0.598, 2.05, 1.06, 1.29, 1.06, 3.14, 1.29]
);
Computes the Wilcoxon rank-sum / Mann-Whitney test (two samples) or the Wilcoxon signed-rank test (one sample or paired), following R's wilcox.test conventions as of R 4.6.1.
This is an alternative to the t-test, that does not assume a normal distribution.
With two array refs and no paired flag it runs the two-sample rank-sum test; with a single sample, or with paired => 1, it runs the signed-rank test. It calculates exact p-values by default for N < 50, including when there are ties or zero differences: as in R 4.6.0 and later, tied data is answered from the conditional (permutation) distribution given the observed ranks rather than falling back to the normal approximation. Optionally it also returns a Hodges-Lehmann point estimate and a distribution-free confidence interval.
Calling conventions
The first one or two array-ref arguments are taken positionally as x and y; everything after that is parsed as key => value pairs. The named forms x => and y => are also accepted and override the positional values. The flat argument list following the positional refs must contain an even number of elements, or the call dies with a usage message.
# positional
wilcox_test(\@x, \@y, paired => 1);
# fully named
wilcox_test(x => \@x, y => \@y, alternative => "greater", exact => 0);
# with a confidence interval and point estimate
wilcox_test(\@x, \@y, conf_int => 1, conf_level => 0.99);
Arguments that R spells with a dot take an underscore here: conf_int, conf_level, digits_rank and tol_root. R's dotted spellings (conf.int, conf.level, digits.rank, tol.root) are refused as unknown arguments.
Input parameters
| Parameter | Type | Default | Description |
|---------------|-----------------|--------------|-------------|
| x | ARRAY ref | (required) | The first sample. Passed positionally or as x =>. Non-numeric, undefined and NaN elements are silently dropped (NaN is R's NA); +Inf and -Inf are kept, since a rank test has no trouble with them. An empty or all-missing x is fatal. In the two-sample test mu is subtracted from each x value. |
| y | ARRAY ref | undef | The second sample. If present and paired is false, a two-sample rank-sum test is run. If paired is true, y is required and must be the same length as x. Omit it, or pass undef, for the one-sample signed-rank test. A y that is present but empty (or entirely missing) is fatal rather than silently becoming a one-sample test. |
| paired | boolean | 0 (false) | Run a paired signed-rank test on the per-element differences x[i] - y[i] - mu. Requires y of equal length. A pair is dropped if either member is missing, or if the difference is NaN (which is what Inf - Inf gives). |
| correct | boolean | 1 (true) | Apply the continuity correction (±0.5) when using the normal approximation. Ignored when an exact p-value is computed. |
| edgeworth | integer 0-3 | 0 | Number of Edgeworth series terms used to refine the normal approximation, for the untied case. This is what R reaches through its integer correct = 1, 2, 3; see the note below on why it is spelled separately here. Ignored on the exact path, and — as in R — ignored when there are ties, or when the signed-rank test dropped a zero difference, because the series is derived for untied ranks. |
| mu | number | 0.0 | Null-hypothesis location shift. Subtracted from x (two-sample) or from each difference (one-sample / paired). Must be finite. |
| exact | boolean / undef | undef (auto) | Tri-state. undef (or absent) selects exact automatically: when both group sizes are < 50 (two-sample), or n < 50 (signed-rank). A true value forces the exact test, a false value forces the approximation. Ties and zero differences no longer disable it. |
| alternative | string | "two.sided" | One of "two.sided", "less", or "greater". Selects the tail(s) used for the p-value. |
| conf_int | boolean | 0 (false) | Also compute a point estimate and confidence interval for the location (one-sample) or location shift (two-sample / paired). |
| conf_level | number in (0,1) | 0.95 | Requested confidence level. The level a rank test can actually deliver is discrete, so the level achieved is reported back in conf_level and is generally not the one asked for. |
| digits_rank | number / undef | undef (Inf) | Round each value to this many significant digits before ranking, so that ties are decided on the rounded values. R's digits.rank, and worth reaching for when the data are the result of arithmetic and two values that ought to tie differ in the last bit. undef means no rounding. |
| tol_root | number > 0 | 1e-4 | Convergence tolerance for the root search behind the asymptotic confidence interval. The exact interval is made of order statistics and does not use it. |
Output
Returns a hash ref with the following keys:
| Key | Type | Description |
|-------------------|--------|-------------|
| statistic | number | The test statistic. For the two-sample test this is the Mann-Whitney W (the x rank sum minus nx*(nx+1)/2). For the signed-rank test it is V, the sum of the ranks assigned to the positive differences. |
| statistic_name | string | "W" or "V", matching what R prints. |
| p_value | number | The p-value for the chosen alternative, capped at 1.0. Two-sided p-values are 2 * min(p_less, p_greater). |
| method | string | A human-readable description of the exact test variant that was run (see below). |
| alternative | string | Echoes the alternative actually used ("two.sided", "less", or "greater"). |
| null_value | number | Echoes mu. |
| null_value_name | string | "location shift" for the two-sample and paired tests, "location" for the one-sample test. |
| estimate | number | (only with conf_int) The Hodges-Lehmann estimator: the median of the Walsh averages (x[i] + x[j]) / 2 in the one-sample case, or of the pairwise differences x[i] - y[j] in the two-sample case. On the asymptotic path it is instead the shift at which the standardised statistic is zero, as in R. |
| conf_int | ARRAY ref | (only with conf_int) Two elements, the lower and upper limits. A one-sided alternative gives an unbounded end (-Inf or Inf). |
| conf_level | number | (only with conf_int) The confidence level actually achieved, which for the exact interval is a step function of the data and rarely equals conf_level. |
The method string reports which path executed:
- Two-sample:
"Wilcoxon rank sum exact test","Wilcoxon rank sum test with continuity correction", or"Wilcoxon rank sum test". - One-sample / paired:
"Wilcoxon signed rank exact test","Wilcoxon signed rank test with continuity correction", or"Wilcoxon signed rank test".
Exact inference with ties
Before R 4.6.0 — and in earlier releases of this module — ties ruled out an exact p-value and the test silently fell back to the normal approximation. It no longer does. When ties are present the exact null distribution is the conditional one given the observed ranks, computed with the Streitberg-Röhmel shift algorithm, and the same holds for zero differences in the signed-rank test. Two consequences are worth knowing about:
- p-values on tied data change from earlier versions. R's own documented example,
wilcox_test(\@x, \@y)on the?wilcox.testdata, moves from0.13292(approximation) to0.12991(exact). - with zero differences, V itself changes. The exact test ranks
|x - mu|over every observation and only then drops the ranks belonging to the zeroes; the approximation drops the zeroes first and ranks what is left.wilcox_test([-1, 0, 1])givesV = 2.5on the exact path andV = 1.5withexact => 0. R behaves the same way.
The exact table is refused rather than attempted if it would need more than 16 million cells, with a message suggesting exact => 0. This is only reachable by forcing exact => 1 on samples far larger than the automatic threshold.
The exact confidence interval on tied data is found as R finds it, by trying the shift between each pair of neighbouring pairwise differences, up to m * n of them, each with its own conditional distribution. That distribution depends only on the ranks, so it is rebuilt only when a shift changes them. Two samples of 49 five-point scores, which take the exact path by default, get their interval in about 0.03 seconds; R 4.6.1 takes 10.
Notes and edge cases
Missing data is handled by listwise removal of non-numeric, undefined and NaN cells before ranking; in the paired case a pair is dropped if either member is missing or if the difference is not a number. An empty x (or a y that is present but empty) after this filtering is fatal. All-zero differences are not: wilcox_test([0, 0, 0, 0, 0]) returns V = 0, p = 1, which is what the permutation distribution over an empty set of sign flips says. A tied array is read like any other, one FETCH per element.
Inf and -Inf are values, not missing data, and a rank test has no trouble with them. In a confidence interval, a difference of two infinities of the same sign (Inf - Inf) is NaN, and it is left out of the differences (or Walsh averages) the estimate and the interval are read from, just as R's sort() leaves it out.
Ties are detected during ranking and trigger the tie-corrected variance in the normal approximation. When exact is left on auto, the size thresholds (< 50 per group, or < 50 observations) are the only thing gating the exact vs. approximate decision.
Differences from R
Three, all deliberate:
correctis a boolean here. R 4.6.0 turned itscorrectinto an integer0:3, in which numeric0still applies the continuity correction and onlyFALSEremoves it. Keeping that would meancorrect => 0no longer meaning "off", which is what it means for every other flag in this module. Socorrectstays a boolean and the Edgeworth terms live underedgeworth: R'scorrect = kforkin1, 2, 3iscorrect => 1, edgeworth => khere, and R'scorrect = 0iscorrect => 1.- A zero variance is reported, not propagated. With
exact => 0and every observation tied there is nothing to divide by; R divides anyway and returnsNaNfor the p-value, and its two-sample confidence interval then dies insideunirootwith missing value where TRUE/FALSE needed. This warns instead, and returnsp = 1and aNaNinterval at level0— which is what R's own one-sample code does. The default path no longer reaches any of this, since the exact test handles all-tied data. - Infinite observations get an answer or a reason, never an error. The asymptotic interval has no finite bracket to search when an observation is infinite. R's two-sample code dies in
unirootwith invalid 'xmin' value, and its one-sample code returns aNaNinterval at level0. Both give thatNaNinterval here, with a warning. The exact one-sample interval on data holding bothInfand-Infstops R with missing value where TRUE/FALSE needed; here it is computed, ranking theNaNthose make last, as R'srank()does.
Everything else is checked against R's and SciPy's own test suites in t/wilcox_test.R.scipy.t.
write_table
mimics R's write.table, with data as first argument to subroutine, and output file as second
write_table(\@data_aoh, $tmp_file, sep => "\t", 'row_names' => 1);
write_table accepts every data-frame shape: a flat hash (one row), a hash of arrays (HoA), a hash of hashes (HoH), an array of hashes (AoH), and an array of arrays (AoA). For an AoA the first inner array is taken as the header row unless col_names is given, in which case every inner array is treated as data:
write_table([[qw(gene score)], ['TP53', 0.9], ['BRCA1', 0.7]], $tmp_file, 'row_names' => 0);
write_table([['TP53', 0.9], ['BRCA1', 0.7]], $tmp_file, 'col_names' => [qw(gene score)]);
A data row longer than the header is not cut short: the header is widened with empty cells over the extra columns, the shape pandas gives DataFrame([[1, 2], [4, 5, 6]]), and write_table warns, naming the first long row.
You can also precisely filter and reorder which columns are written by passing an array reference to col_names:
write_table(\@data, $tmp_file, sep => "\t", 'col_names' => ['c', 'a']);
undefined values are written as empty fields by default, but can be set as you wish using undef_val
write_table(\%data_hoa, '/tmp/undef.val.tsv', sep => "\t", 'undef_val' => 'nan')
A hash of hashes keeps its outer keys as a leading column by default, since that is the only place they exist. Name that column with row_names, or drop it with row_names => 0:
my %taxa = (9606 => { species => 'Homo sapiens' }, 10090 => { species => 'Mus musculus' });
write_table(\%taxa, 'taxa.tsv', 'row_names' => 'taxid'); # taxid species
Leaving that column unnamed writes an empty first header cell, and every reader then has to invent a name for it (read_table calls it row_name, pandas Unnamed: 0). write_table therefore warns and suggests row_names. It also warns when any data column has an empty name, whatever the shape. The empty label cell that row_names => 1 writes for the other shapes is R's own layout, and nothing can name it, so that one is not warned about.
For a hash of arrays or an array of hashes, row_names => 'col' takes the labels from column col and heads the label column col, as pandas heads an index with its name:
write_table(\%hoa, 'out.csv', 'row_names' => 'gene'); # gene,score / TP53,0.9 / ...
A hash of arrays without a column col is an error. An array of hashes may lack it in some rows: those rows are labelled with undef_val, and one warning gives their count.
An array of arrays and a flat hash have no named column to take labels from, so for them row_names => 'name' heads their 1..n label column name, as it heads a HoH's key column. As for a HoH, a name that is already a column's is an error.
A hash of arrays has as many rows as the longest of the arrays it writes; an array that col_names leaves out does not add rows.
An empty {} or [] is a table with no rows, and is written as one: the header col_names and row_names give, if any, and otherwise a single empty record. write_table([], 'out.csv', 'col_names' => ['A'], 'row_names' => 1) writes ,A, as pandas writes DataFrame({"A": []}).to_csv().
Every cell of delimited output is written whole, including one holding a NUL byte, and a cell of a tied hash or array (such as Tie::IxHash) is read through its FETCH. A number is formatted the way perl formats it, but in a copy, so writing a table does not add a string buffer to every numeric scalar in it. Nor does finding an AoH's or a HoH's columns leave an iterator on every row hash, as walking them with keys would. A row that is a restricted hash (Hash::Util::lock_keys) may lack some of the columns; those cells are written empty, where they used to die with Attempt to access disallowed key.
A field is quoted when it holds a quote (which is doubled), a line break or the separator, as Python's csv.writer quotes, and in two more places where read_table would otherwise not see the record at all. A record of a single field that is empty, undef or nothing but spaces and tabs is written quoted, "" or " ", because a blank line is skipped on reading; csv.writer writes [''] and [None] the same way. The first field of a record is quoted when it starts with #, read_table's default comment character.
A reference anywhere in the table is an error, in a header cell (col_names, or an AoA's first row) as in a data cell. For an AoA, an undef in col_names is an empty header cell in its place, since an AoA's columns are positional; for every other shape, which looks its columns up by name, it is skipped.
write_table determines comma and tab-separated delimiters from the filename, but will override if sep or delim are explicitly set. A separator may be more than one character, but not empty, and may not contain a NUL, a quote, a CR or a LF: a file written with one of those could not be split into its fields again. A file name containing a NUL is an error too, as it is to perl's open.
Args can also be accepted:
write_table( 'data' => \%flat, 'file' => $f );
compressed files (.gz, .bz2)
A file name ending in .gz is written gzip-compressed, and one ending in
.bz2 bzip2-compressed:
write_table(\@rows, 'cohort.tsv.gz'); # tab-separated, then gzipped
write_table(\@rows, 'cohort.csv.bz2');
- The rest of the name means what it always did: the default
sepcomes from the part before the suffix, socohort.tsv.gzis tab-separated. The text inside is exactly what the plain file would hold. - It is streamed, compressed as the rows are written, at gzip's and
bzip2's default levels (6 and 9, as R's
gzfileandbzfileuse). A gzip file's header carries no name or time, so the same table always makes the same bytes. - A write that fails partway leaves a truncated file, which
read_tablerefuses, never one that looks whole. A compressed write also croaks if the file cannot be finished. - Only delimited text is compressed. A name such as
table.tex.gzorbook.xlsx.bz2, ortex/xlsxwith a compressed name, is an error. - Both use core modules only. A
.bgzname is an error: it promises bgzip's BGZF, which tabix can index and plain gzip is not. Write.gz, and runbgzipon the plain file if you need BGZF.
The confirmation line
Every successful write prints one line to standard output naming the file, with the name in black on cyan:
wrote output.tsv
This is say 'wrote ' . colored(['black on_cyan'], $file), but the SGR codes (\e[30;46m … \e[0m) are written out inline, so the module takes no dependency on Term::ANSIColor. Every format announces itself the same way — delimited, LaTeX and .xlsx alike — so you always learn where a table went, in the same shape whatever you asked for. Nothing is printed when nothing is written: a write that cannot open its file, or that loses data on the way to it, croaks instead. That includes a full disk, which a buffered write only discovers at the close; every format checks for it, as R's write.table does. The message gives the system's reason, so a full disk reads write_table: could not finish writing 'out.csv': No space left on device, and a quota or an I/O error says so instead; $! is left set to it. A file that cannot be opened gives its reason the same way (Permission denied, No such file or directory). An empty data frame is written, and so announced.
The colour is unconditional; it is not suppressed when standard output is a pipe or a file. Pass quiet => 1 to suppress the line altogether, which is what a script writing to a pipe or a data file usually wants:
write_table(\@rows, 'out.tsv', quiet => 1); # writes the file, says nothing
quiet silences the line rather than decolouring it, because the coloured form is the one contract every format shares. If you want the line but not the escapes, strip them (s/\e\[[\d;]*m//g) or send them somewhere else. Note also that the line goes to file descriptor 1 directly rather than through Perl's STDOUT glob, so local *STDOUT; open STDOUT, '>', \my $buf will not capture it — redirect the file descriptor, or run the write in a child process, if you need to.
LaTeX output (tex)
write_table can write the output file as a LaTeX tabular instead of a delimited table. This is selected either by naming the file *.tex (auto-detected) or by passing tex => 1; an explicit tex => 0 forces a delimited file even when the name ends in .tex. The LaTeX table is built from the same rows as the delimited writer, so it works for every shape above (including arrays of arrays):
write_table(\@data_aoh, 'table.tex'); # .tex name selects LaTeX
write_table(\@data_aoh, $tmp_file, 'tex' => 1); # force LaTeX for any name
The file begins with a %written by <cwd>/<script> provenance comment (the working directory and script name). The header row is bold and the table is ruled with \hline. As with every other format, row_names is off unless you ask for it, except for a HoH: pass row_names => 1 to prepend a label column of 1-based indices. A HoH writes its outer keys as that column by default, and row_names => 0 drops them. Cell text is LaTeX-escaped: #, _, %, and & are backslash-escaped, < and > become \textless{} and \textgreater{} (in LaTeX's default font encoding a bare < prints as ¡; inside $...$ the two macros still print, with a LaTeX warning), and a cell consisting solely of \includesvg{...svg} is passed through untouched. The other LaTeX specials — \, $, {, }, ^ and ~ — are left alone on purpose, so that a cell can hold LaTeX of its own: inline math such as $p^2$, or a macro such as \textit{x}. A cell that means one of them literally writes it escaped (\$, \{, \textasciicircum{}). A table with no columns at all is an error, since LaTeX rejects one, and it is refused before the file is opened. The tex_* options tune the output:
write_table(\@rows, 'table.tex',
'tex_col_align' => 'l', # 'c' (default), 'l', or 'r'
'tex_bold_1st_col' => 0, # default 1: bold the first column
'tex_format' => 1, # %.4g-format numeric cells
'tex_size' => '\small', # size directive after \begin{tabular}
'tex_comment' => ['run 3', 'q < 0.05'], # % comment line(s): string or array ref
);
For a table that must span page breaks, tex_longtable => 1 writes only the table body — the bold header row and the data rows, ruled with \hline — but no \begin{tabular}/\end{tabular} and no column spec, so you can \input{} it into a longtable environment you write yourself. Setting tex_longtable implies tex => 1, so it applies to any file name (and overrides tex => 0). After the provenance comment (and any tex_comment lines) the file emits a % \begin{longtable}{...} hint with one tex_col_align character per column, so you can copy a column spec with the right count. In this mode tex_col_align affects only that hint — the real alignment lives on your own \begin{longtable}; the other tex_* options (tex_bold_1st_col, tex_format, tex_size, tex_comment) still apply:
write_table(\@rows, 'output.file.tex', 'tex_longtable' => 1);
writes a body-only file such as
%written by /home/con/Scripts/stats/make_table.pl
% \begin{longtable}{ccc}
\hline
\textbf{a} & \textbf{b} & \textbf{c} \\ \hline
1 & 2 & 3\\
\hline
which you wrap yourself:
\begin{longtable}{ccc}
\input{output.file.tex}
\caption{}
\label{}
\end{longtable}
In that plain form the header is an ordinary first row, which is not the header LaTeX freezes at the top of each page: a longtable repeats only what sits inside \endfirsthead / \endhead. Hand-writing those blocks means retyping the column labels, and they then silently stop matching col_names the first time the column order changes — the frozen header says one thing while the columns underneath say another, and the generated header shows up a second time as the first body row. tex_longtable_head closes that gap by generating the repeat machinery from the same header record as the body:
write_table(\@rows, 'output.file.tex',
'col_names' => ['a', 'b', 'c'],
'tex_longtable_head' => '(continued)', # or just 1 for no continuation caption
);
%written by /home/con/Scripts/stats/make_table.pl
% \begin{longtable}{ccc}
\textbf{a} & \textbf{b} & \textbf{c} \\ \hline
\endfirsthead
\caption[]{(continued)}\\
\hline
\textbf{a} & \textbf{b} & \textbf{c} \\ \hline
\endhead
\hline
\endfoot
1 & 2 & 3\\
Setting tex_longtable_head implies tex_longtable (and so tex => 1). A true-but-numeric value emits the machinery with no continuation caption; any other true value is the caption text for every page after the first, written verbatim so LaTeX macros survive, with an empty \caption[] optional argument so the continuation stays out of the List of Tables. \endfoot carries the closing \hline and no \endlastfoot is emitted, so every page — the last one included — gets a bottom rule. The wrapper then holds nothing that has to track the data:
\begin{longtable}{ccc}
\caption{}\label{}\\ \hline
\input{output.file.tex}
\end{longtable}
The trailing \hline on the caption line is the rule above the header on the first page, and it has to live there rather than in the generated file: \hline expands to \noalign, and TeX has already begun a table row by the time it expands your \input, so a rule as the file's first token is a Misplaced \noalign error. A bare \hline encodes neither column order nor column count, so unlike a hand-written header it cannot go stale — drop it if you do not want a top rule. Every other \hline in the generated file follows a \\ inside that file, where it is legal.
Excel output (xlsx)
write_table can write a real Excel .xlsx workbook. It is selected either by naming the file *.xlsx (auto-detected) or by passing xlsx => 1; an explicit xlsx => 0 forces a delimited file even for a .xlsx name. Like LaTeX, it is built from the same rows as the delimited
writer, so it works for every shape above:
write_table(\@data_aoh, 'table.xlsx'); # .xlsx name selects Excel
write_table(\%data_hoa, $tmp_file, 'xlsx' => 1); # force Excel for any name
A number is written as a number cell, and every other non-empty cell as an
inline string (undef/empty cells are omitted). A value perl holds as a number
is a number cell, unless it is infinite or NaN, which are written as text. A
string is a number cell only when Excel would show it as it stands: a plain
decimal (an optional -, digits with at most one ., an optional exponent),
with no leading zeros but the one in 0 or 0.5, at most 15 significant
digits, and a magnitude Excel holds (up to 9.99999999999999E+307). So 007,
+5 and a 20-digit accession number stay text, where Excel used to show them
as 7, 5 and 1.23457E+19; pandas likewise writes a str as a string. The
result reads straight back with read_table.
XML 1.0 cannot hold a NUL, most other control characters, the noncharacters
U+FFFE and U+FFFF, or a surrogate, and a workbook holding one is refused by its
readers. In a cell each is written as Excel's own escape, _xHHHH_ (\r is
_x000D_), which Excel and LibreOffice turn back into the character, as
XlsxWriter does. A literal _x0041_ in a cell is written _x005F_x0041_ so
that it is not mistaken for one, and so is every other underscore that would
open an escape, overlapping ones included, so that a reader decoding left to
right gets back exactly the text written.
In the sheet name and xlsx_comment such characters are dropped. A code point
above U+10FFFF, which no Unicode encoding has, is an error.
Excel's limits are enforced rather than written past: a worksheet holds 1048576 rows (header included) and 16384 columns, and a cell 32767 characters, the checks XlsxWriter and pandas (This sheet is too large!) make. A table that is too long is refused before the file is opened, except a hash of arrays, whose length is only known as its rows are written.
The worksheet is streamed to the file as the rows are formatted, so writing a workbook takes little memory beyond the data itself: a 200000 x 20 array of hashes needs 30 MB for a 308 MB workbook, where it used to need 1.1 GB. Like delimited output, a write that croaks partway (a nested reference in a late row, say) leaves a truncated file behind. A file that cannot seek, such as a pipe, still works; its worksheet is gathered in memory first. A workbook larger than 4 GB, the most a ZIP archive holds without ZIP64, is refused.
Mirroring Excel::Writer::XLSX's
$workbook->set_properties(comments => comments()), the same
written by <cwd>/<script> provenance line the LaTeX writer emits is stored in
the workbook's document comments property (dc:description in
docProps/core.xml); a xlsx_comment string (or array ref of strings) is
appended after it. xlsx_sheet sets the worksheet name (default Sheet1). As
in openpyxl, a name that is empty or holds any of \ * ? : / [ ] is an error, and
one longer than 31 characters draws a warning, since Excel cannot read it:
write_table(\@rows, 'report.xlsx',
'xlsx_sheet' => 'Results',
'xlsx_comment' => 'batch 9',
);
xlsx_freeze_rows and xlsx_freeze_cols freeze that many leading rows/columns in place (Excel's freeze panes), so they stay visible while scrolling — most often used to pin the header row. They go up to 1048575 and 16383, one short of the sheet's limits:
write_table(\@rows, 'report.xlsx', 'xlsx_freeze_rows' => 1); # pin the header row
write_table(\@rows, 'report.xlsx', 'xlsx_freeze_rows' => 1, 'xlsx_freeze_cols' => 2); # pin header + first two columns
tex and xlsx are mutually exclusive. Note: dates/times are written as their
raw values (no cell number formats), matching the round-trip behaviour of
read_table.
Options
| option | default | applies to | meaning |
|---|---|---|---|
| data (1st positional, or data =>) | required | both | the table: flat hash, HoA, HoH, AoH, or AoA |
| file (2nd positional, or file =>) | required | both | output path; written as a delimited table, or as LaTeX when tex is on |
| sep / delim | from extension (, for .csv, tab for .tsv), else , | delimited | field separator; the two are aliases. Not empty, and no NUL, quote, CR or LF |
| row_names | 0 (off); 1 (on) for a HoH | both | true prepends a label column (numeric 1-based index, or the outer key for a HoH); 0 omits it. Off by default in every format — delimited, LaTeX and .xlsx alike — for every shape but a HoH. (R's write.table defaults it on and this once followed suit for LaTeX; it no longer does.) A HoH defaults it on, because its outer keys are the row identifiers and exist nowhere else. For a HoA/AoH a non-numeric column name uses that column's values as the labels and drops it from the body; a HoA without that column dies, and AoH rows without it are labelled undef_val, with a warning. For a HoH, an AoA or a flat hash a non-numeric string names the label column (the outer keys, or 1..n), so row_names => 'taxid' heads it taxid instead of leaving the header cell empty; it dies if that name is also a column being written. A reference dies |
| col_names | all columns, sorted | both | array ref selecting and ordering columns; for an AoA it also supplies the column names |
| undef_val | '' (empty field) | both | text written for an undefined/missing cell, e.g. 'NA' |
| tex | auto: 1 when file ends in .tex, else 0 | LaTeX | write the output file as a LaTeX tabular instead of a delimited table; tex => 0 forces delimited even for a .tex name |
| tex_col_align | 'c' | LaTeX | per-column alignment: 'c', 'l', or 'r'; with tex_longtable on it sets only the % \begin{longtable}{...} hint |
| tex_bold_1st_col | 1 (on) | LaTeX | bold the first column of each data row |
| tex_format | 0 (off) | LaTeX | render numeric cells with %.4g |
| tex_size | (none) | LaTeX | size directive emitted after \begin{tabular}, e.g. \small |
| tex_comment | (none) | LaTeX | % comment line(s) at the top of the LaTeX file: a string (an object is stringified), or an array ref of strings. Every line of each is a comment: a line break inside one opens a new % line |
| tex_longtable | 0 (off) | LaTeX | write only the table body (header + data rows + \hline, no \begin{tabular}/\end{tabular} or column spec) for \input{} into a caller-supplied longtable; implies tex => 1, and emits a % \begin{longtable}{...} hint with one tex_col_align char per column |
| tex_longtable_head | 0 (off) | LaTeX | generate longtable's repeat-header machinery (\endfirsthead / \endhead / \endfoot) from the table's own header, so the header frozen at every page break tracks col_names instead of being hand-written; a non-numeric value is the continuation caption. Implies tex_longtable. Put the first page's top rule on your own \caption line (\\ \hline) — a leading \hline in an \inputed file is a Misplaced \noalign error |
| xlsx | auto: 1 when file ends in .xlsx, else 0 | Excel | write a real .xlsx workbook (dependency-free, built in XS) instead of a delimited table; xlsx => 0 forces delimited even for a .xlsx name. Mutually exclusive with tex |
| xlsx_sheet | 'Sheet1' | Excel | worksheet name |
| xlsx_comment | (none) | Excel | extra line(s) appended after the provenance in the workbook's document comments property (dc:description): a string (an object is stringified), or an array ref of strings |
| xlsx_freeze_rows | 0 (none) | Excel | number of leading rows to freeze in place (freeze panes), e.g. 1 to pin the header row; at most 1048575 |
| xlsx_freeze_cols | 0 (none) | Excel | number of leading columns to freeze in place (freeze panes); at most 16383 |
Numerical accuracy
zerotrunc
A count regression truncated at zero, countreg::zerotrunc(): the model for a
count that is only observed when it is at least 1, such as length of stay among
those admitted. Fitting an ordinary Poisson or negative binomial to such data
underestimates the mean at low counts, because it expects zeros that can never
be seen.
use Stats::LikeR 'zerotrunc';
my $z = zerotrunc(formula => 'days ~ hours + age', data => \%admitted,
dist => 'negbin');
printf "theta = %.3f\n", $z->{theta};
| Option | Default | Description |
| --- | --- | --- |
| formula | (required) | Formula as for glm, with offset() terms allowed. |
| data | (required) | HoA, AoH or HoH. The response must be positive integers. |
| dist | 'poisson' | 'poisson', 'negbin' or 'geometric'. |
| theta | estimated | For negbin, a fixed dispersion instead of an estimated one, as countreg's theta = . |
| offset | none | A column, an expression, or an array ref. |
| weights | none | Case weights. |
| conf_level | 0.95 | Level of the Wald intervals in summary. |
The result holds coefficients, summary (per term Estimate, Std. Error,
z value, Pr(>|z|), CI_lower, CI_upper), vcov, terms, loglik,
aic, df_residual, df_null, nobs, converged and iter; theta and
SE_logtheta for negbin, as countreg reports them; fitted_values, the
truncated mean mu / (1 - f(0)), and Pearson-style residuals. The fit is a
damped Newton iteration on the exact likelihood and its analytic Hessian.
Validated against countreg and against mpmath at 60 digits.
F and z tail p-values
A p-value is an upper-tail probability, and the obvious way to get one from a
CDF — subtract it from 1 — throws the answer away exactly when the answer
matters most. 1 - pf(F, df1, df2) cannot represent anything below the ulp of
1.0, about 2.2e-16, so every p-value past that point comes back as a flat
0, and relative precision is already eroding from roughly 1e-9 down. The
same applies to 2 * (1 - pnorm(|z|)) for a Wald z.
Every F and z p-value in Stats::LikeR is therefore evaluated in the tail
itself:
- F tests (
oneway_test,aov,anovain both its forms,lm'sf_pvalue, andvar_test) use the regularized-incomplete-beta symmetry1 - I_x(a, b) = I_{1-x}(b, a). Withx = df1·F / (df1·F + df2), the complement1 - xis justdf2 / (df1·F + df2), which is formed without any subtraction, so the tail keeps full relative precision. - Normal / z tails (
glm'sPr(>|z|), andcor_test's large-sample approximation for thespearmanandkendallmethods) use2 * pnorm(-|z|)two-sided andpnorm(-z)for the upper one-sided alternative.pnormis0.5 * erfc(-x/√2), anderfcis accurate deep into its own tail, so evaluating at-|z|rather than subtracting at+|z|costs nothing and loses nothing. R writes it the same way. - Two-tailed t (
t_test,cor_test's Pearson path, and thePr(>|t|)columns oflmandglm) was always computed as a direct two-tail incomplete-beta probability, so it never had the problem. So were the exact permutation p-valuescor_testuses for small n.
Three functions outside this set still form a normal-tail p-value
subtractively, so a p-value from them below about 1e-16 reads as 0:
wilcox_test (the greater alternative of the normal approximation, in both
the two-sample and the one-sample/paired branch — its two.sided and less
alternatives are already computed on the correct side), prop_test (the
greater alternative; two.sided goes through the chi-squared path instead)
and dunn_test (the two-sided per-comparison p-values that p_adjust then
corrects).
The practical difference: lm on a near-noiseless fit reports
f_pvalue = 7.0165242049e-220 where the subtractive form returned 0, and
anova's sequential table reports 1.1543232446e-171 for the same reason.
Where the true value underflows a double even when computed correctly — a Wald
z beyond about 38.5 — the result is 0, and R and SciPy return 0 there too.
Verified against R 4.6.1 (oneway.test, anova(aov()), anova(lm()),
summary(lm())$fstatistic, summary(glm())$coefficients) and against SciPy's
f.sf / norm.sf and statsmodels' anova_oneway; see
t/model_pvalue_tails.t and t/oneway_test.R.scipy.t.
COPYRIGHT AND LICENSE
This software is free. It is licensed under the same terms as Perl itself
Thanks
A lot of this work used Claude AI, which was paid for by the University of Idaho's IMCI